
IPV-Bench
IPV-Bench (Impossible Videos; Show Lab, NUS) flips the usual physics question. It asks whether models can depict counterfactual, physically impossible events — and whether video-understanding models can recognize them. The taxonomy covers physical, biological, geographical, and social impossibilities. Two tracks:
- Generation (IPV-Txt) — visual quality and prompt following;
impossible_video_scoreis the share of clips that are both high-quality and prompt-faithful. - Understanding (IPV-Vid) — judgement, multi-choice QA, and open QA against official labels.
ipv_bench_average aggregates whatever official families you supply.
Paper: Impossible Videos. Code: showlab/Impossible-Videos.
WorldFoundry normalizes official CSV/JSON exports for both tracks. It does not run the official judges or understanding models in tree. --run-fixture is wiring only.
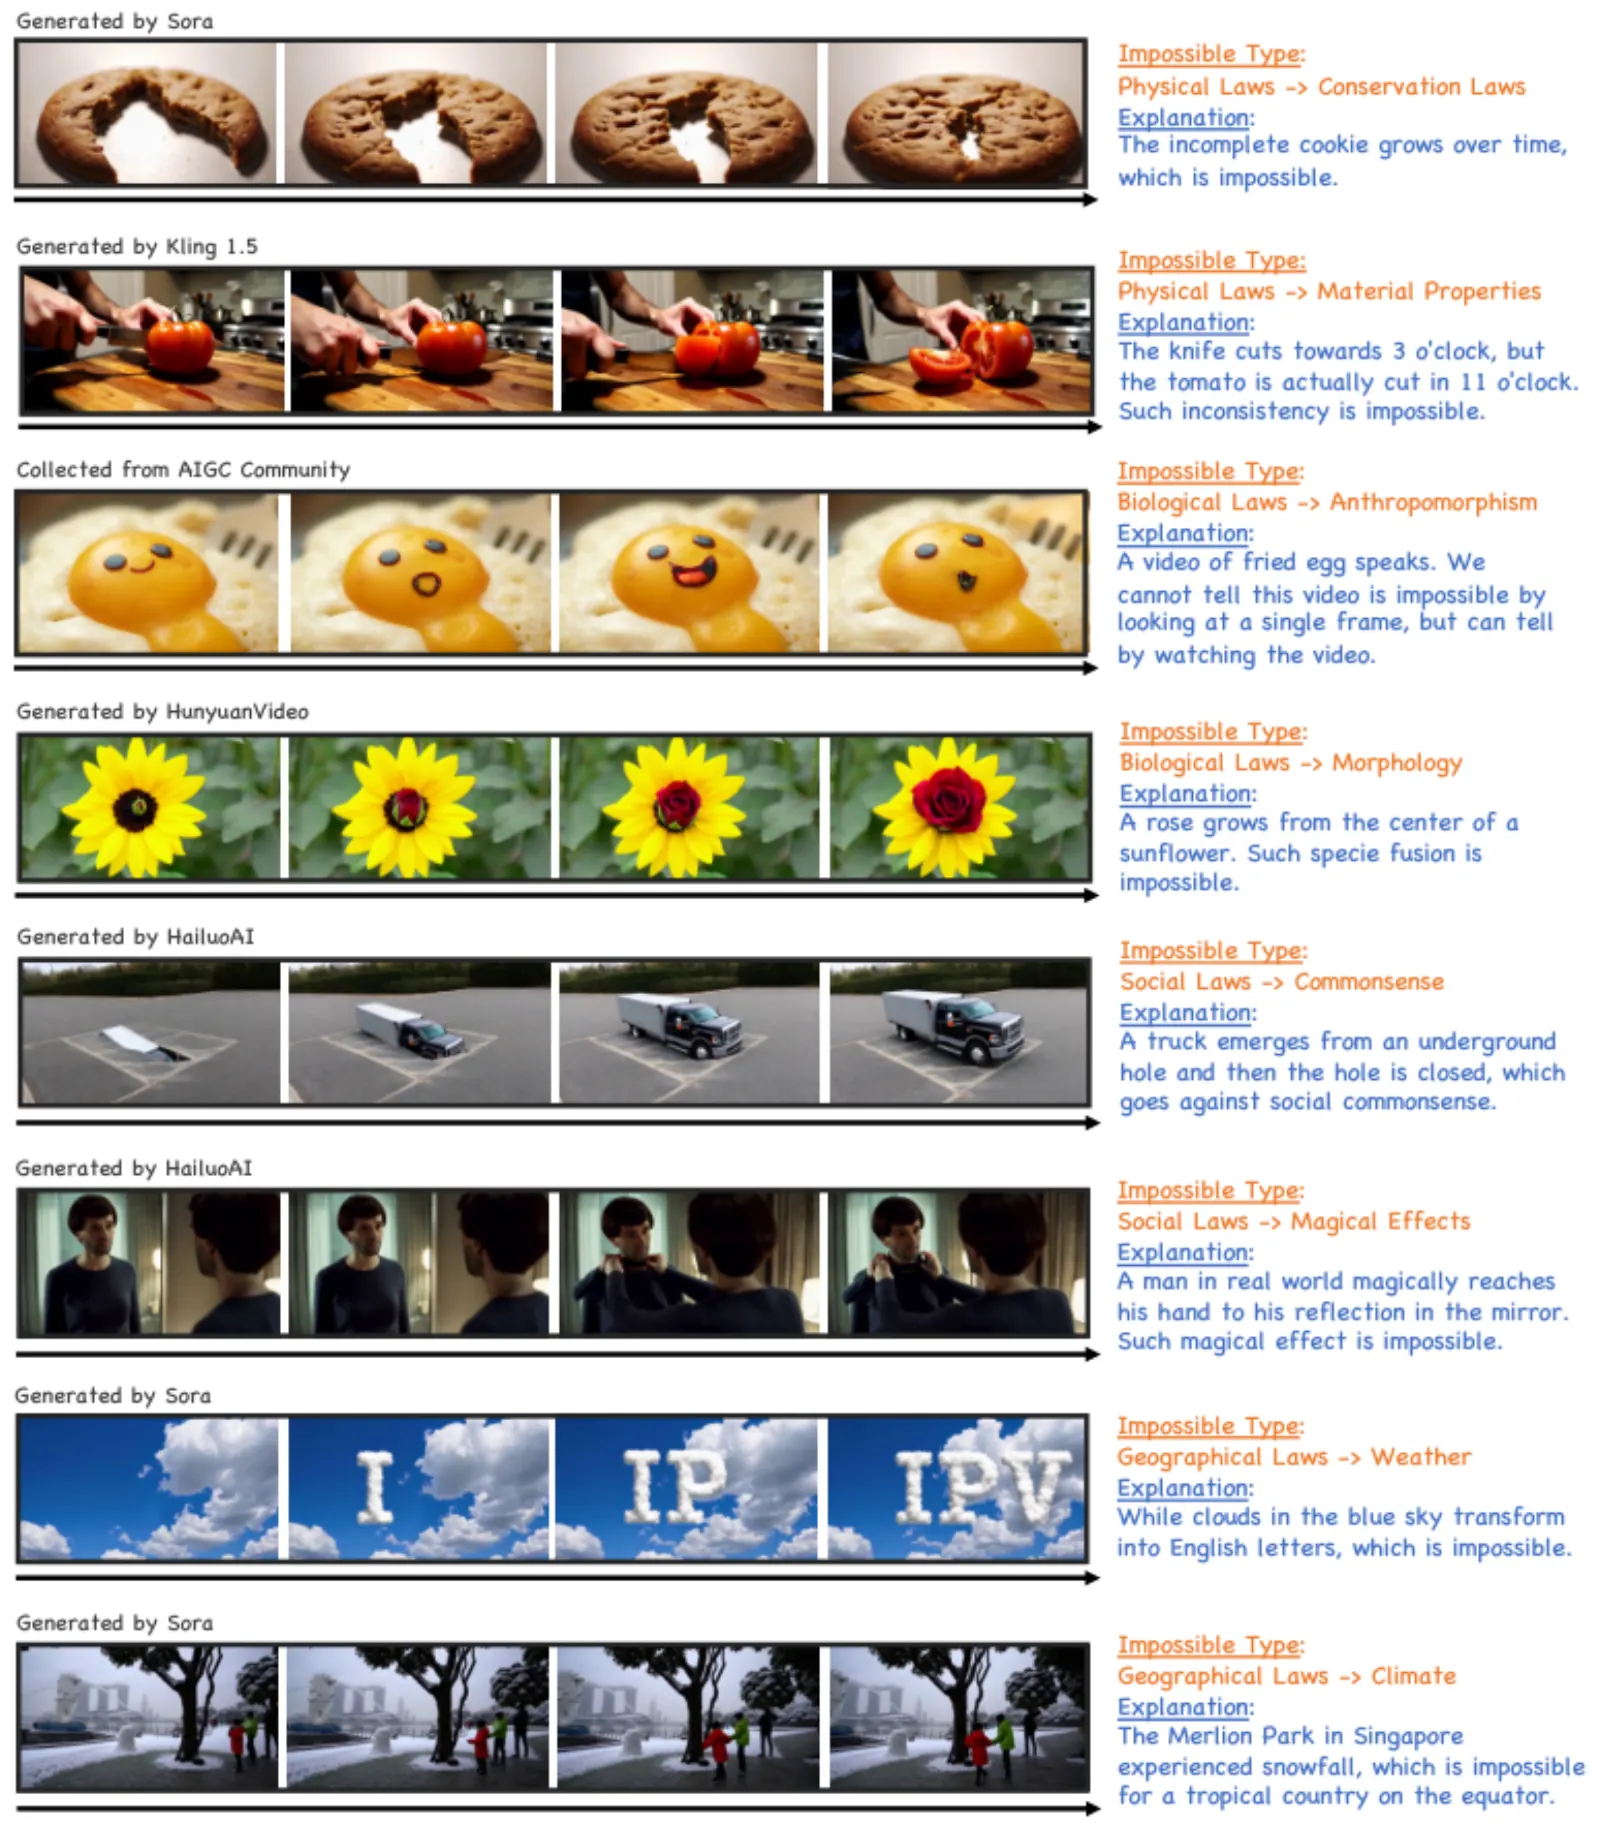
Dimensions
- IPV-Txt generationKindTrack
Visual quality and prompt following; impossible_video_score is the share of clips that are both high-quality and prompt-faithful.
- IPV-Vid understandingKindTrack
Judgement, multi-choice QA, and open QA against official labels.
Data composition
- Size
NUS Show Lab Impossible Videos: generate and recognize physically, biologically, geographically, and socially impossible events. Two tracks (IPV-Txt / IPV-Vid).
- Sources
github.com
- Modalities
text · video
- Notes
WorldFoundry normalizes official CSV/JSON. It does not run the official judges or understanding models.
Metrics
Metric
- DirectionHigher is better
visual_qualityIPV-Bench human or official judge annotation for generated-video visual quality.
- DirectionHigher is better
prompt_followingIPV-Bench human or official judge annotation for prompt following.
- DirectionHigher is better
impossible_video_scorePercentage of generated videos that are both high quality and good prompt following under the IPV-Bench protocol.
- DirectionHigher is better
judgement_accuracyIPV-Bench video-understanding judgement task accuracy against official labels.
- DirectionHigher is better
mcqa_accuracyIPV-Bench multi-choice QA accuracy against official labels.
- DirectionHigher is better
open_qa_scoreIPV-Bench open-ended QA score from official evaluator or judge outputs.
- DirectionHigher is better
ipv_bench_averageIPV-Bench aggregate when supplied by official annotations, judge outputs, or normalized result files.
PrimaryIPV-Bench Average
Leaderboard
Results from the paper (not a live board; not WorldFoundry-run scores). Impossible Videos (2025).
| Model | IPV score |
|---|---|
| Mochi 1 | 37.3 |
| Pyramid-Flow | 19.6 |
| CogVideoX-1.5 | 16.9 |
| Open-Sora | 15.8 |
| LTX | 10.0 |
How to run
worldfoundry-eval zoo benchmark-run \
  --benchmark-id ipv-bench \
  --mode official-validation \
  --official-results-path <official_results.csv> \
  --generated-artifact-dir <generated_videos> \
  --output-dir tmp/ipv-bench/official-validation \
  --json
Default import: WORLDFOUNDRY_IPV_BENCH_RESULTS_PATH. Optional root / backend: WORLDFOUNDRY_IPV_BENCH_ROOT, WORLDFOUNDRY_IPV_BENCH_RUNTIME_BACKEND. No Hugging Face dataset is required by the contract.
In-tree pointers: worldfoundry/data/benchmarks/tasks/external/ipv-bench.yaml, worldfoundry/evaluation/tasks/execution/runners/ipv_bench.
Outputs include scorecard.json (primary ipv_bench_average) and raw_metric_table.jsonl.