Toward a general infrastructure for world intelligence
WorldFoundry
Discover, run, inspect, and evaluate world models under one operational definition — without flattening them into a single interface.
275 model entries · 74 browsable benchmarksWorld models stay heterogeneous. Shared catalogs, artifacts, and scorecards are what make them comparable.
Try it out
Choose a real catalog entry. Runtime and version facts come from the repository manifests, and the command stays copyable.
worldfoundry-eval run wan2.2 \
--pipeline.task-profile text-to-videoWhy WorldFoundry
Shared catalogs, durable artifacts, and evidence-aware scorecards — while native inputs, execution semantics, and evaluation protocols stay model-specific.
Declarative model and benchmark manifests, plus explicit runtime and asset management, make heterogeneous systems discoverable before compute is spent.
Durable request and result contracts decouple generation from scoring. Videos, geometry, actions, and traces can be inspected or rescored without reloading the model.
Scorecards keep declared support, operational readiness, and validated performance separate, so a catalog entry or a demo is never mistaken for a benchmark claim.
Catalog
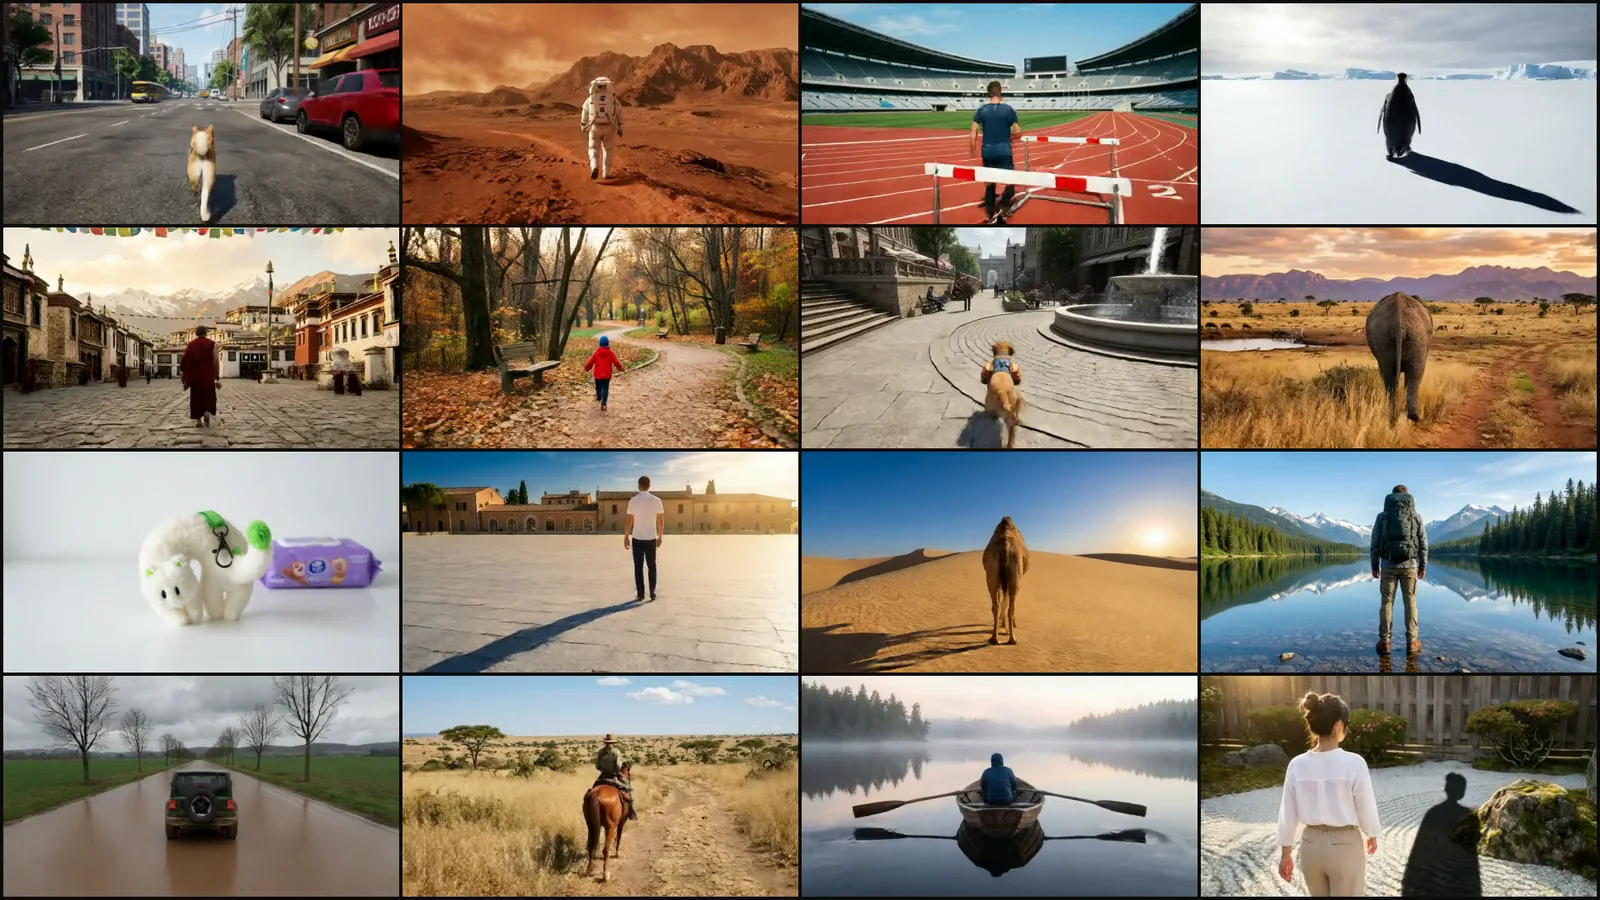
Video, 3D/4D, interactive worlds, and embodied systems share manifests and readiness signals. Catalog inclusion is not uniform runtime maturity.
275 models74 benchmarks
Video
Capability progression
Visual plausibility is not world modeling. A system exhibits stronger competence as representations become persistent, transitions become intervention-responsive, and predictions become useful in a closed loop.
Interpret, reconstruct, or synthesize observations. This is the perceptual basis for state inference — not yet a persistent model of the environment.
World-model spine
persistent state → dynamics prediction → interactive feedback
Infer and maintain structured environmental state across observations, identities, geometry, and partial views.
Predict coherent transitions under endogenous processes, actions, and interventions, so earlier events constrain later outcomes.
Act, observe, and update the same state. Feedback revises what the model believes before the next prediction.
Selectively edit represented content while leaving the rest intact. Manipulation can strengthen any stage, but it is not by itself dynamics or interaction.
End to end
Catalog, runtime, workspace, and evaluation share identities and durable outputs.
Manifests expose stable IDs, sources, capabilities, assets, runtime bindings, readiness, and blockers before compute is allocated.
See what is includedPipelines preserve model-native I/O while TUI, CLI, Studio, Python, and MCP reuse the same execution contracts.
Understand the designVideos, geometry, actions, trajectories, and traces stay visible on disk and in Studio instead of disappearing inside scripts.
Explore StudioBenchmark runners preserve per-sample outcomes, coverage, provenance, blockers, reports, and scorecards.
Read about evaluationFive-stage pipeline
Every surface follows the same sequence. The artifact is the handoff between model execution and benchmark evaluation.
Discover
Catalog manifests expose stable IDs, capabilities, readiness, assets, and blockers.
Prepare
Resolve the conda profile, checkpoints, datasets, metric weights, and credentials.
Run
TUI, CLI, scripts, and Studio dispatch to a pipeline and operator.
Inspect
Videos, geometry, actions, traces, and metadata remain visible and reusable.
Evaluate
Metrics and official runners write reports, blockers, and a normalized scorecard.
Everyone welcome
Whether you're just getting started or debugging a complex run, the community is open to everyone. No question is too basic.
Around the project
Notes, events, and sibling projects in the OpenEnvision network.
Updates, technical notes, and release highlights.
Meetups, demos, benchmark sprints, and milestones.
The lab organization behind WorldFoundry.
Curated papers, models, and resources for world modeling.
Curated index for technical AI research blogs and writing.
Source, issues, discussions, and releases.