Emu3.5
Checkpoint-backed interleaved text and image generation through the official runtime.
Emu3.5 is BAAI's model for interleaved text and image generation. WorldFoundry calls a pinned checkout of the official implementation and returns its protobuf response. It does not generate video.
A checkpoint-backed howto run through the WorldFoundry pipeline produced three text segments and two decoded 384×384 PNG images. Larger image sizes and byte-for-byte parity with a separate official CLI invocation remain unverified.
Code: baaivision/Emu3.5. Weights: BAAI/Emu3.5 and BAAI/Emu3.5-VisionTokenizer.
Build your run
Emu35Pipelineworldfoundry.pipelines.emu35.pipeline_emu35worldfoundry.pipelineworldfoundry-eval run \
emu3.5 \
--pipeline.task-profile multimodal-generation \
--jsonWhat it is for
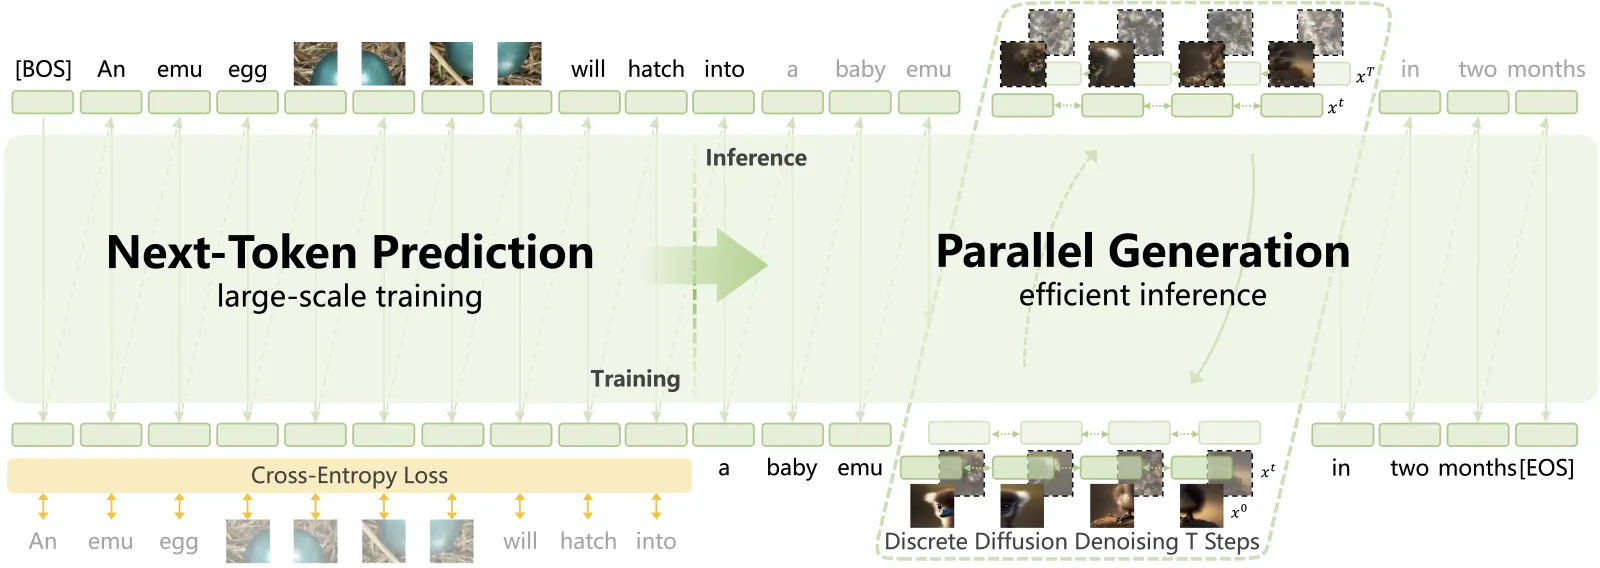
The story and howto tasks take a text prompt and optionally a reference image. Emu3.5 predicts a unified text/image token sequence, generates visual tokens with discrete diffusion, and decodes images with its separate vision tokenizer. The response may contain text and images; it is stored as an official .pb artifact.
Runtime contract
The runtime requires both checkpoints and the official source at revision 8fcf1da48f9c5252fe0a0b8dc842e07b6efcd745. Set WORLDFOUNDRY_HFD_ROOT to the directory containing BAAI--Emu3.5 and BAAI--Emu3.5-VisionTokenizer, and WORLDFOUNDRY_EMU35_REPO_ROOT to the checkout. Model loading uses the official Emu3 class with eager attention; the vision tokenizer, generation, decoding, and protobuf writer also come from the official release.
WorldFoundry checks local assets before inference and does not download weights at runtime. The checkpoint-backed howto response was parsed with three text segments and two decoded images. Byte-for-byte parity with a separate official CLI invocation remains unverified.
Running in WorldFoundry
Use the emu3.5 pipeline binding with a prompt and optional image. The default output is emu3.5.pb; task_type selects story or howto. Optional target_height and target_width set the visual-token grid together (a 24×24 grid decodes to 384×384 pixels). Give max_new_tokens enough room to finish the image; a shorter cap can yield a valid protobuf containing only text. The model needs a GPU with enough memory for the large main checkpoint and the vision tokenizer.