CALVIN
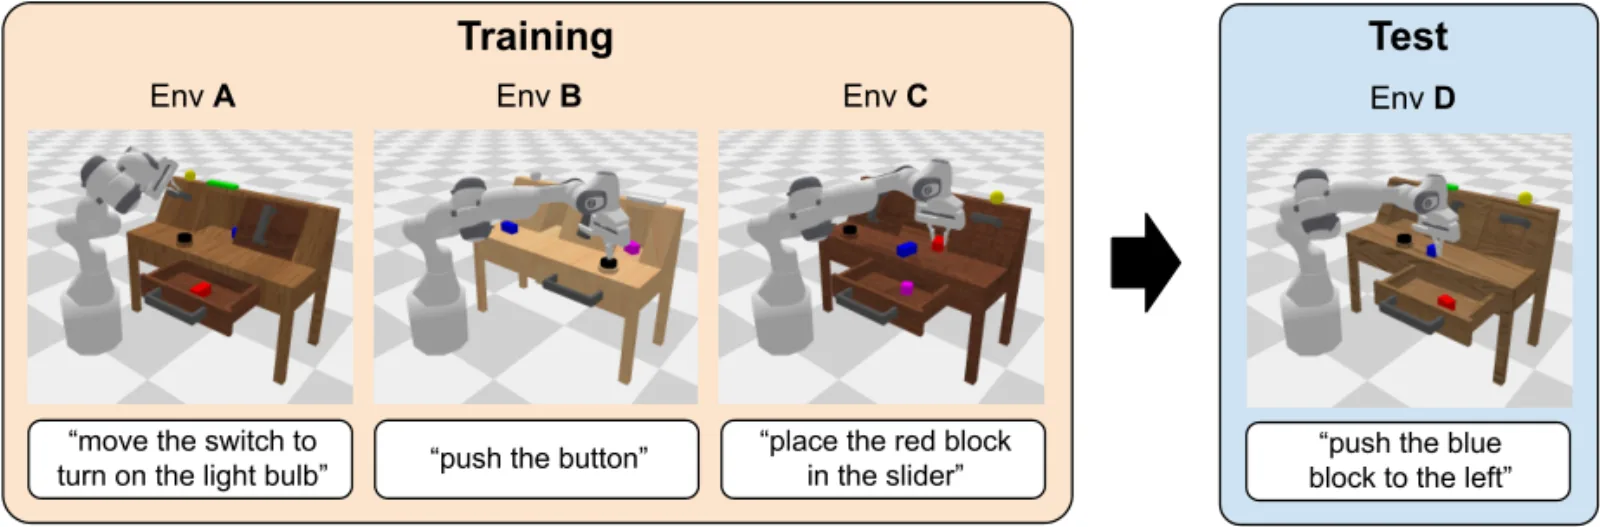
CALVIN (Composing Actions from Language and Vision) is the University of Freiburg's long-horizon, language-conditioned manipulation benchmark (IEEE RA-L 2022). A policy in a PyBullet tabletop must chain up to five language instructions. Four environment configurations A/B/C/D test zero-shot transfer: the signature split trains on A/B/C and evaluates on unseen D. The paper reports success at each chain length and the average number of completed instructions, not a single binary episode bit.
Paper: CALVIN (also discussed at calvin.cs.uni-freiburg.de). Code: mees/calvin (MIT).
WorldFoundry is an official-results importer. You run the upstream sequence evaluator, then normalize the export. Simulator, dataset roots, and policy checkpoints follow the official CALVIN docs. Repo mirror: cache/vla_va_wam/repos/mees--calvin.
Dimensions
- Train ABC → test DKindSplit
Zero-shot transfer: train on environments A/B/C, evaluate on unseen D.
- Instruction chain length 1–5KindAxis
Official protocol reports success at each chain length and mean completed instructions.
Data composition
- Size
Long-horizon language-conditioned tabletop (PyBullet) from University of Freiburg: up to five language instructions in sequence across four environment configurations (A/B/C/D).
- Sources
github.com
- Splits
abc · d
- Modalities
language · vision · action · state
- License
mit
- Notes
WorldFoundry normalizes official sequence-evaluation exports. Dataset roots and policy checkpoints follow the mees/calvin docs.
Metrics
Metric
- DirectionHigher is better
success_ratePrimary episode success rate over evaluated rollouts.
PrimarySuccess Rate
- DirectionHigher is better
sequence_successSuccess over five-instruction chains (long-horizon protocol).
- DirectionHigher is better
task_successPer-task success aggregate.
- DirectionHigher is better
completionAverage number of completed instructions per sequence.
Leaderboard
Official live board, embedded on this page. Not WorldFoundry-run scores. calvin.cs.uni-freiburg.de.
How to run
worldfoundry-eval zoo benchmark-run \
  --benchmark-id calvin \
  --mode official-validation \
  --official-results-path <official_results.json> \
  --output-dir tmp/calvin/official-validation \
  --json
Default import path: WORLDFOUNDRY_CALVIN_RESULTS_PATH. Manifest: worldfoundry/data/benchmarks/tasks/external/calvin.yaml. Outputs: scorecard.json (primary success_rate; also sequence_success, completion) and raw_results.jsonl.