ManiSkill
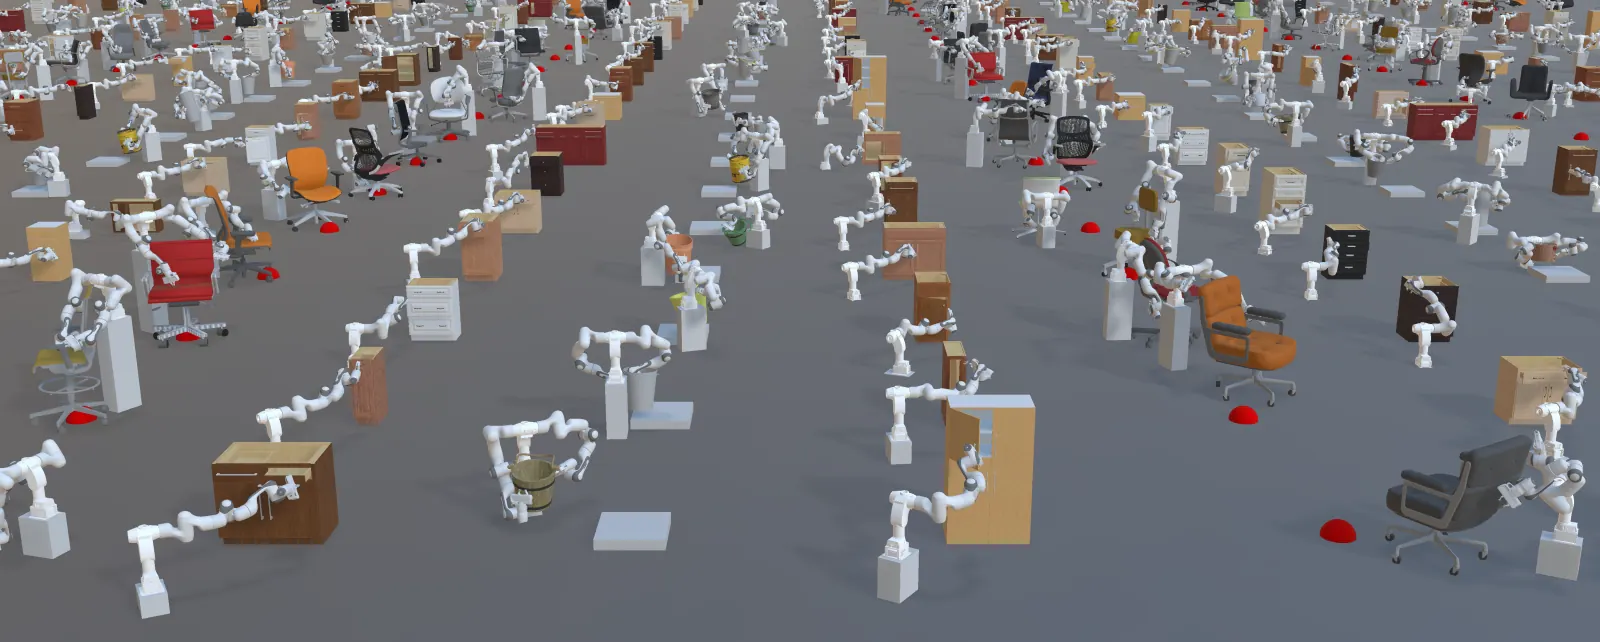
ManiSkill is UC San Diego Hao Su Lab's GPU-parallel manipulation benchmark on SAPIEN: dozens of skill families, multiple robot embodiments, demonstration datasets, and massively parallel rollouts for RL and imitation. The paper is ManiSkill: Generalizable Manipulation Skill Benchmark with Large-Scale Demonstrations. Project: maniskill.ai. Code: haosulab/ManiSkill (Apache-2.0). Later ManiSkill2 / ManiSkill3 releases keep the same lab and engine; this card is the ManiSkill importer, not a silent rename of those pages.
WorldFoundry's path is official-results only. You run the upstream tooling, then official-validation normalizes JSON/CSV rollout summaries into the unified scorecard. Simulator execution, policy loading, and data collection stay explicit and upstream. The repo mirror is cache/vla_va_wam/repos/haosulab--ManiSkill.
Dimensions
- Rigid-body manipulationKindCategory
Pick, stack, insert, and related rigid-object families on SAPIEN.
- Soft / articulated objectsKindCategory
Deformable and articulated assets where contact and joint limits matter.
- Robot embodimentsKindAxis
Multiple arms and grippers; the official suite is GPU-parallelized on SAPIEN.
- Demonstrations vs RLKindTrack
Large demonstration sets for imitation, plus massively parallel RL rollouts.
Data composition
- Size
GPU-parallel SAPIEN benchmark from UCSD Hao Su Lab: dozens of manipulation families, multiple embodiments, and demonstration datasets. WorldFoundry does not run the simulator; it normalizes official rollout exports.
- Sources
github.com
- Modalities
language · vision · action · state
- License
apache-2.0
- Notes
Simulator execution, policy loading, and rollout collection stay upstream. This page is an official-results importer.
Metrics
Metric
- DirectionHigher is better
success_ratePrimary episode success rate over evaluated rollouts.
PrimarySuccess Rate
- DirectionHigher is better
task_successPer-task success aggregate.
- DirectionHigher is better
rewardMean episode reward / return.
- DirectionHigher is better
normalized_returnNormalized episode return.
Leaderboard
Results from the paper (not a live board; not WorldFoundry-run scores). Same official paper as ManiSkill2. From-scratch visual RL on PickCube. ManiSkill2: A Unified Benchmark for Generalizable Manipulation Skills (2023).
| Model | PickCube success (from-scratch visual RL) |
|---|---|
| PPO, point cloud | 0.22 |
| PPO, RGBD | 0.01 |
How to run
worldfoundry-eval zoo benchmark-run \
  --benchmark-id maniskill \
  --mode official-validation \
  --official-results-path <official_results.json> \
  --output-dir tmp/maniskill/official-validation \
  --json
Default import path when you omit --official-results-path is WORLDFOUNDRY_MANISKILL_RESULTS_PATH. Task manifest: worldfoundry/data/benchmarks/tasks/external/maniskill.yaml. Outputs: scorecard.json (primary success_rate) and raw_results.jsonl.