Meta-World
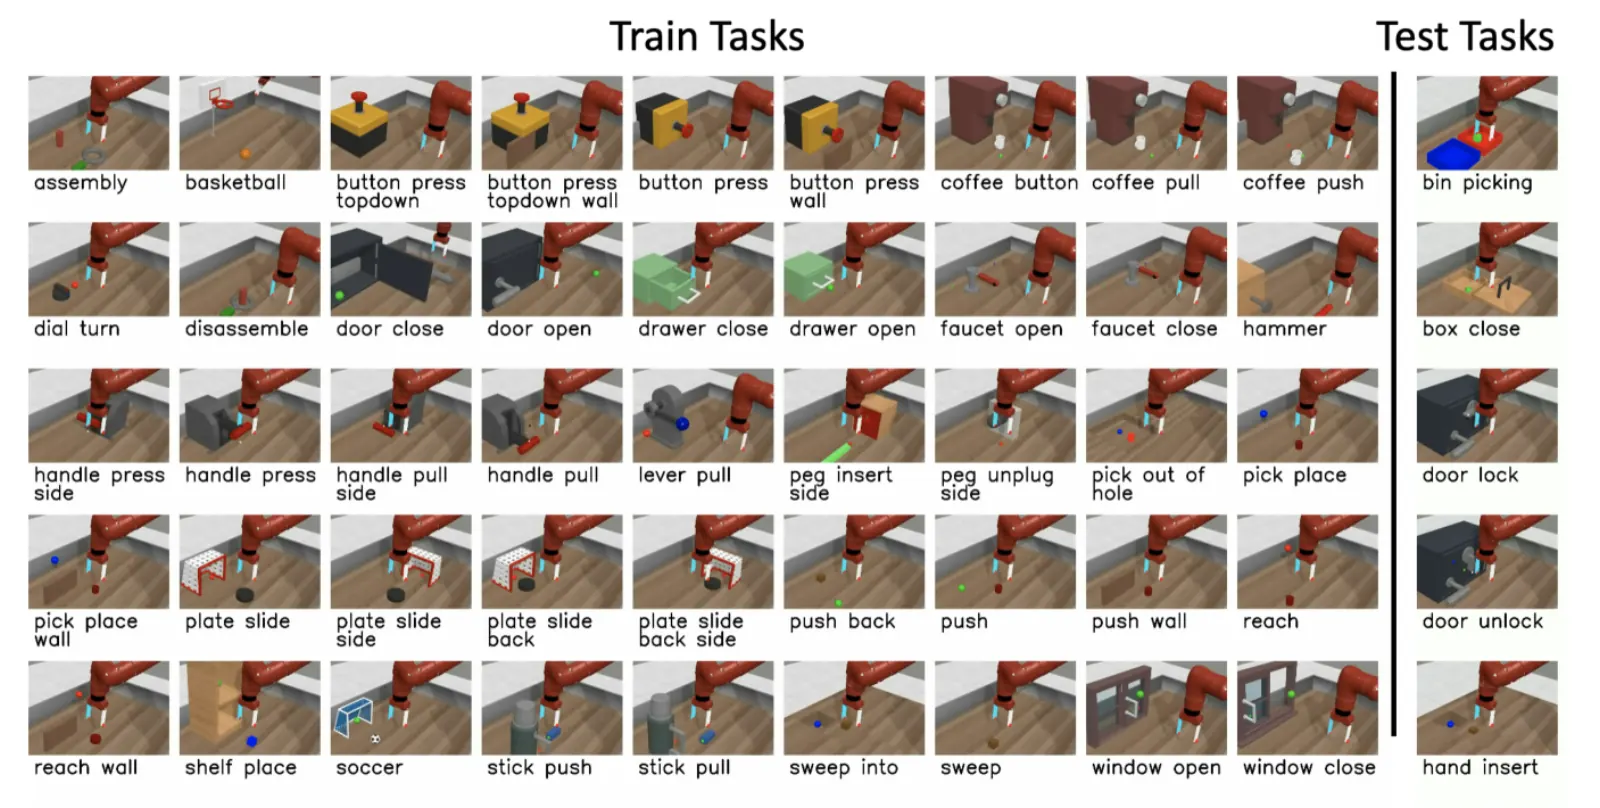
Meta-World (CoRL 2019) is Stanford, UC Berkeley, and USC's multi-task and meta-RL manipulation benchmark, now maintained by the Farama Foundation. A Sawyer arm in MuJoCo must solve 50 distinct tabletop skills (reach, push, drawer, assembly, …). Official evaluation is not one number: you name the suite.
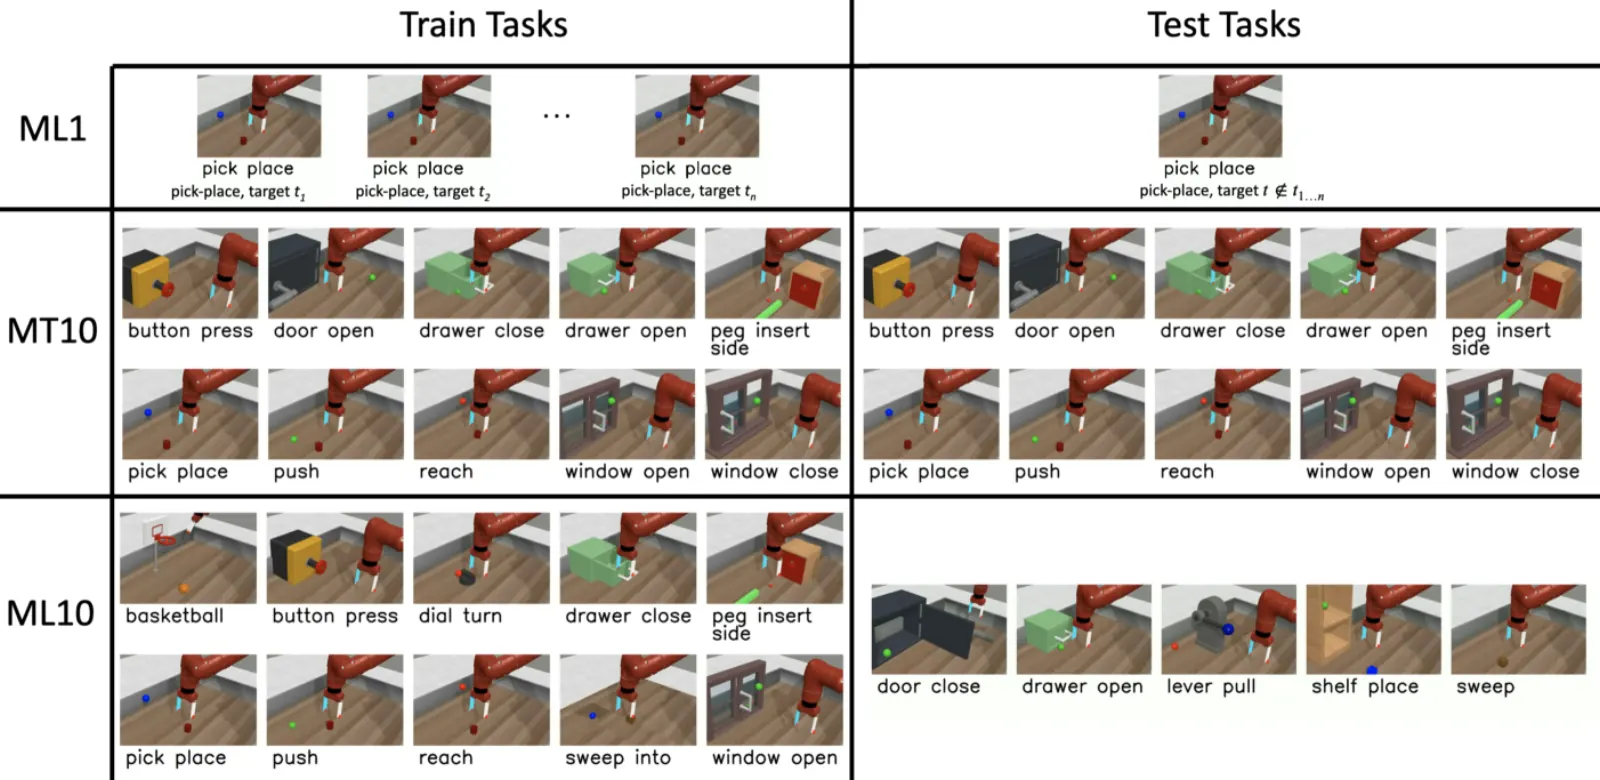
Multi-task (same policy, shared training):
- MT1 — one skill.
- MT10 — ten skills; report mean success.
- MT50 — all fifty.
Meta-learning (adapt to held-out tasks / goals):
- ML1 — one skill, held-out goals.
- ML10 — 10 meta-train / 5 meta-test skills.
- ML45 — 45 meta-train / 5 meta-test skills.
The usual report card is binary success rate, not raw return. Paper: Meta-World: A Benchmark and Evaluation for Multi-Task and Meta Reinforcement Learning. Project: meta-world.github.io. Code: Farama-Foundation/Metaworld (MIT).
WorldFoundry is official-results only. You run Farama Metaworld / MuJoCo upstream, then official-validation normalizes JSON/CSV. No in-tree simulator. Declare the MT/ML suite with the export or the rows cannot be compared.
Dimensions
- MT1KindSuite
Single-task multi-task control: one of the 50 Sawyer skills.
- MT10KindSuite
10-task multi-task suite. Report mean success across the ten skills.
- MT50KindSuite
All 50 tabletop skills trained and evaluated together.
- ML1KindSuite
Meta-learning on one skill with held-out goals.
- ML10KindSuite
10 meta-train skills, 5 held-out meta-test skills.
- ML45KindSuite
45 meta-train skills, 5 held-out meta-test skills.
Data composition
- Size
50 distinct MuJoCo tabletop tasks with a Sawyer arm. Official multi-task suites MT1 / MT10 / MT50 and meta-learning suites ML1 / ML10 / ML45. Maintained by Farama Foundation (MIT).
- Sources
github.com
- Splits
mt1 · mt10 · mt50 · ml1 · ml10 · ml45
- Modalities
vision · action · state
- License
mit
- Notes
WorldFoundry normalizes caller-provided JSON/CSV. Declare the MT/ML suite with the export or rows are not comparable.
Metrics
Metric
- DirectionHigher is better
success_rateBinary episode success averaged over the declared MT/ML suite — the usual Meta-World report card.
PrimarySuccess Rate
- DirectionHigher is better
task_successPer-skill success among the 50 Sawyer tasks in the declared suite.
- DirectionHigher is better
rewardMean episode return if the official dump includes dense reward.
- DirectionHigher is better
normalized_returnReturn scaled to the official per-task range when the export provides it.
Leaderboard
Results from the paper (not a live board; not WorldFoundry-run scores). Multi-task RL baselines from the original paper (not a live board). Meta-World: A Benchmark and Evaluation for Multi-Task and Meta Reinforcement Learning (2019).
| Model | MT10 success |
|---|---|
| Multi-task SAC | 68.3% |
| Multi-task TRPO | 31.3% |
| Multi-task PPO | 30.5% |
| Task embeddings | 20.9% |
How to run
worldfoundry-eval zoo benchmark-run \
  --benchmark-id metaworld \
  --mode official-validation \
  --official-results-path <official_results.json> \
  --output-dir tmp/metaworld/official-validation \
  --json
Default import path when you omit --official-results-path is WORLDFOUNDRY_METAWORLD_RESULTS_PATH. Manifest: worldfoundry/data/benchmarks/tasks/external/metaworld.yaml. Outputs: scorecard.json (primary success_rate) and raw_results.jsonl.