MiKASA-Robo
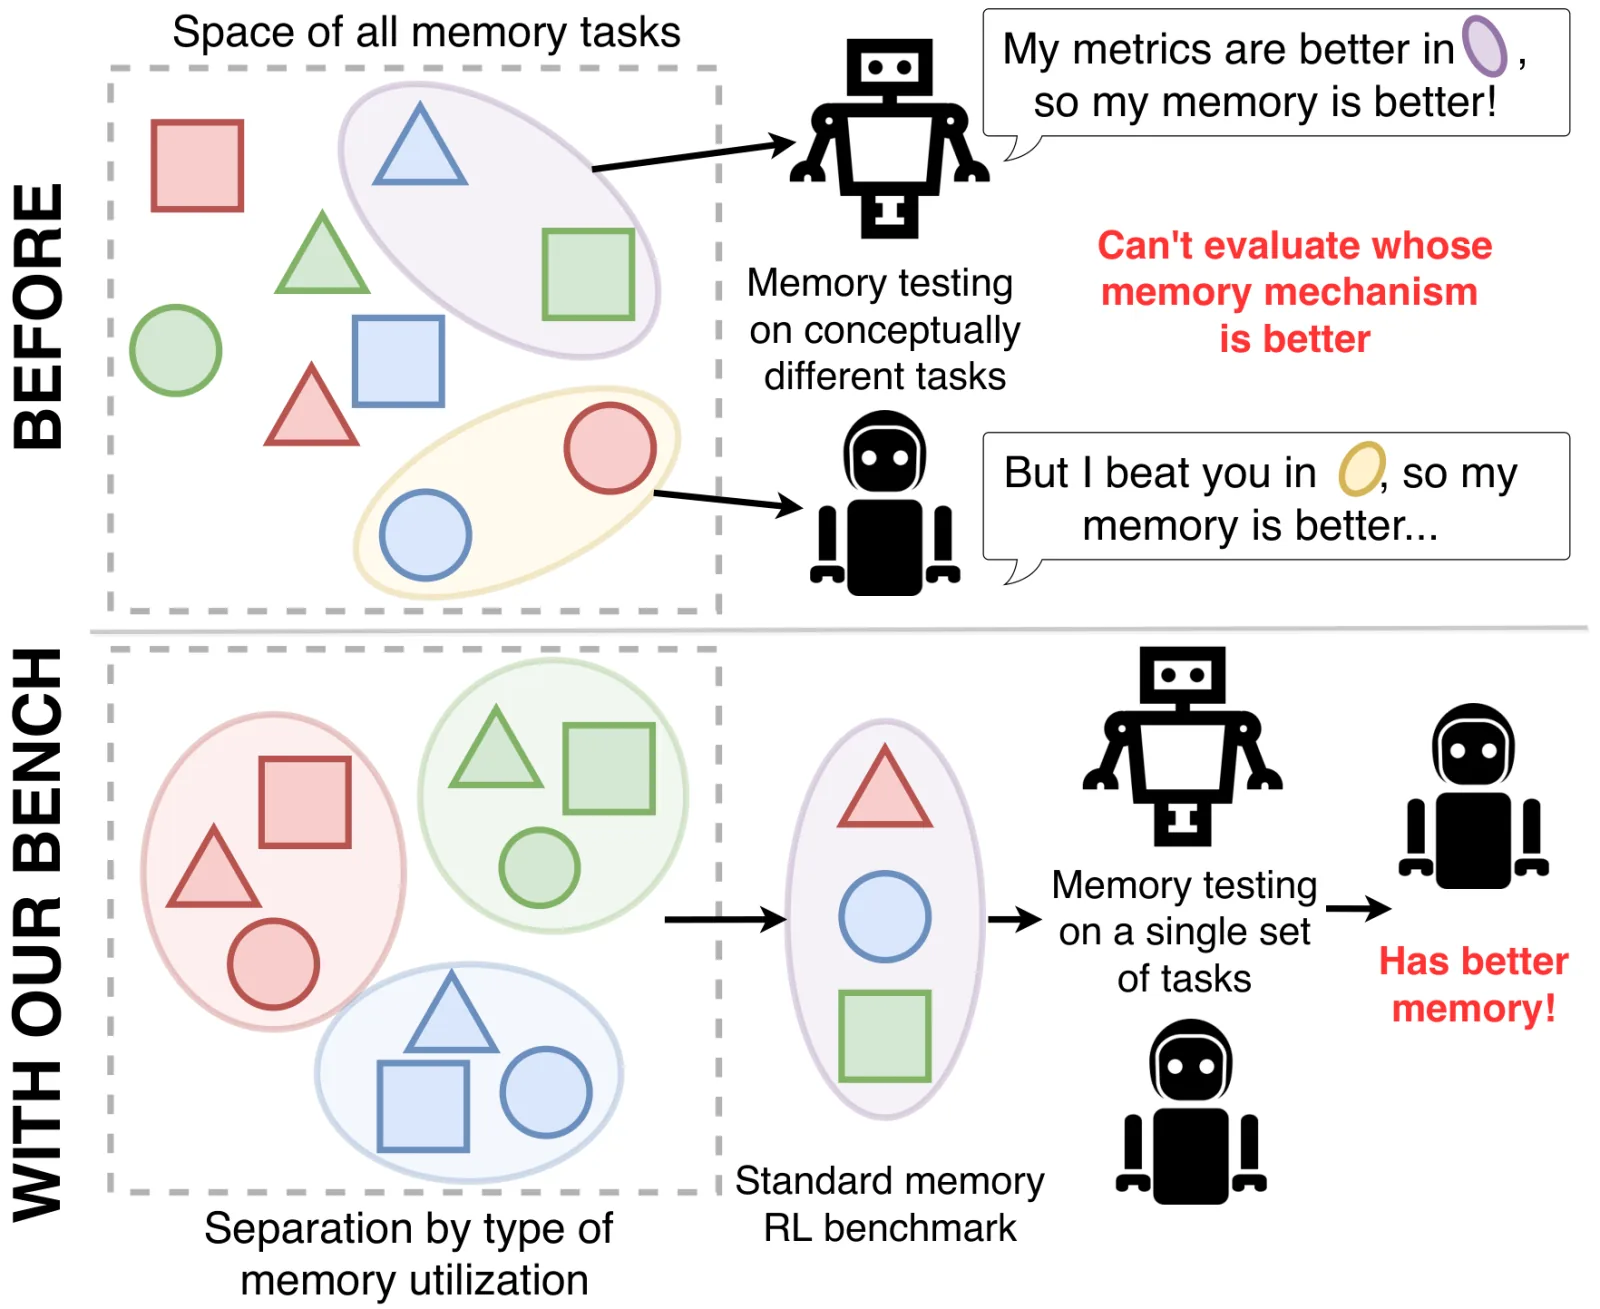
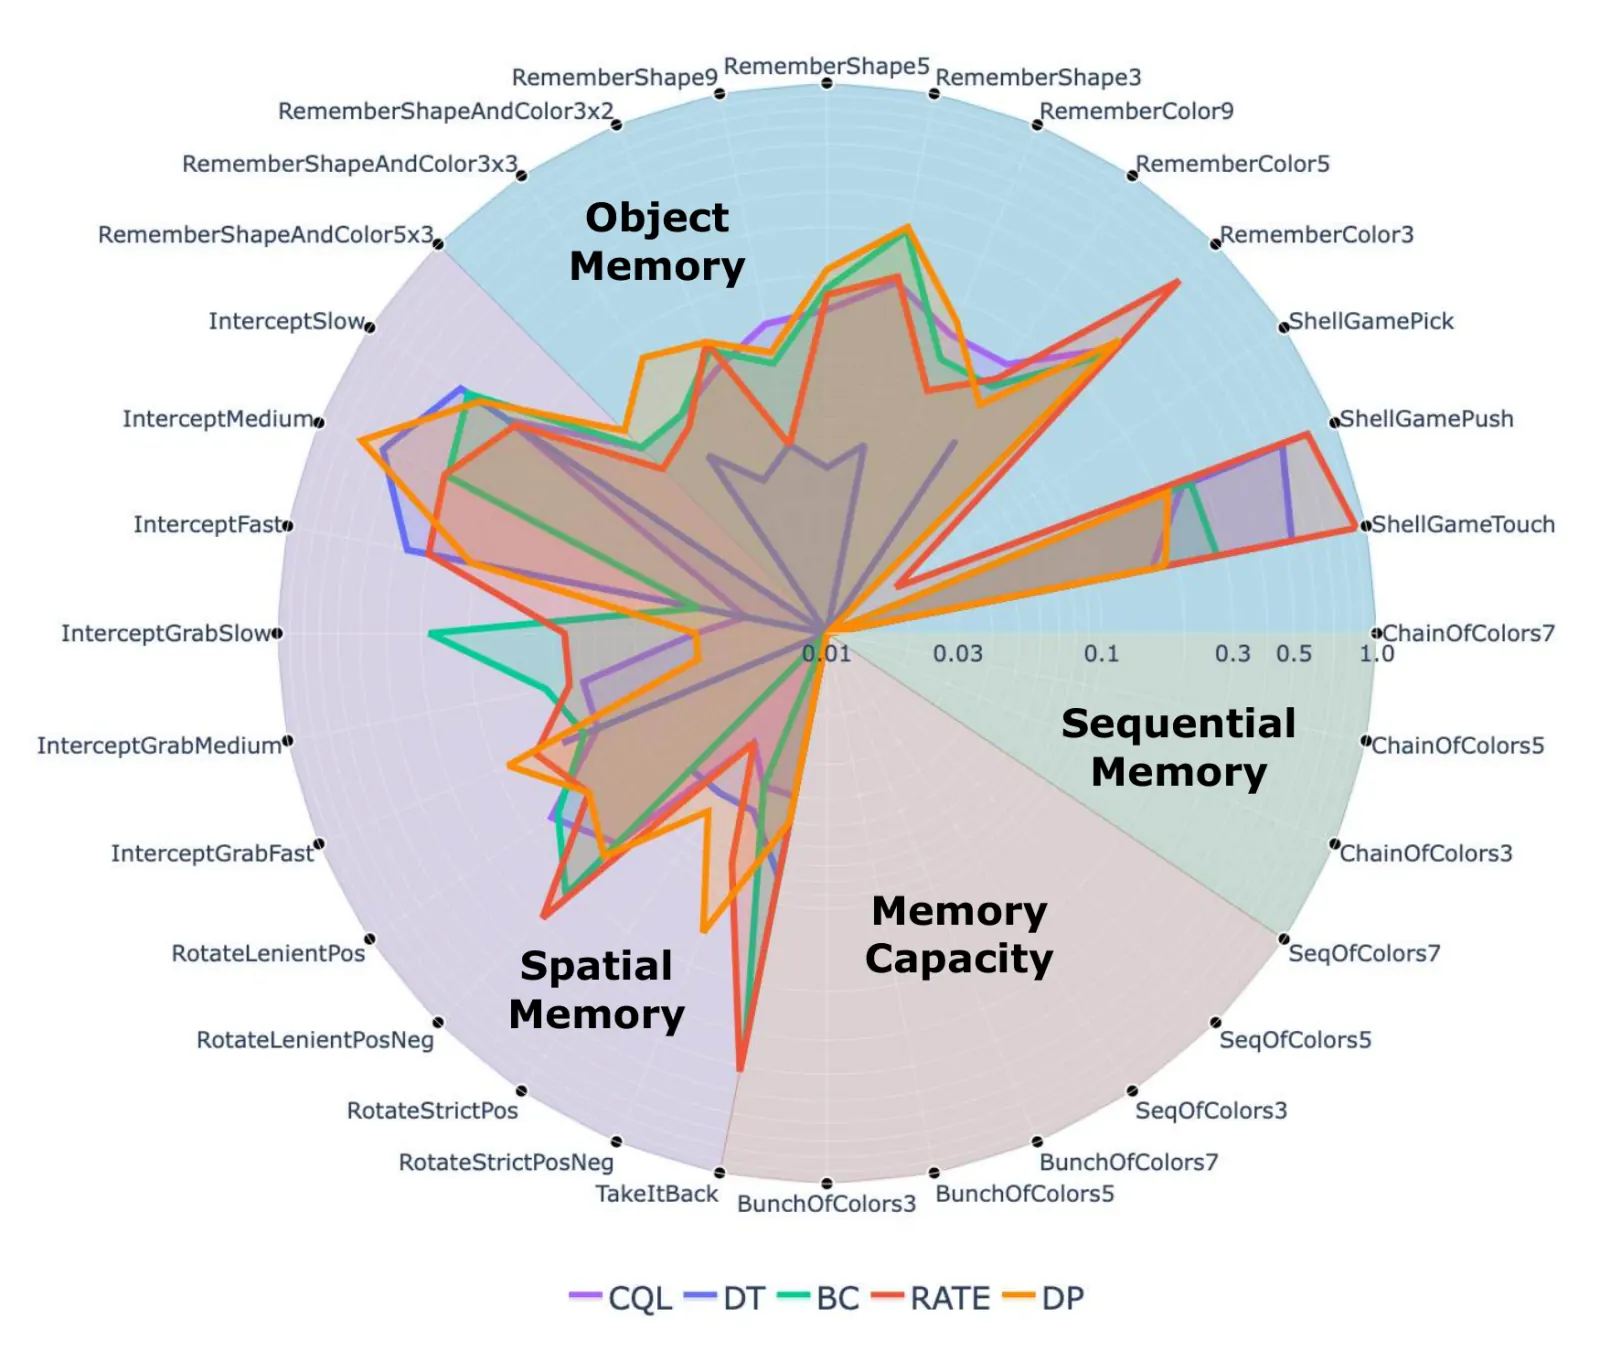
MiKASA-Robo is the tabletop half of MIKASA (Memory-Intensive Skills Assessment Suite for Agents) from AIRI, MIPT, and HSE. The ICLR 2026 paper is 32 ManiSkill RL tasks in 12 groups across four memory types: object, spatial, sequential, and capacity (occlusion recall, prior layouts, long action orders). The later MIKASA-Robo-VLA release grows to 90 language-conditioned tasks (10 memory types), Short / Medium / Long horizons (25–2160 steps), and 22,500 oracle trajectories. Those two releases are not interchangeable.
Paper: Memory, Benchmark & Robots (OpenReview). VLA docs: mikasarobo.github.io. Code: CognitiveAISystems/MIKASA-Robo.
WorldFoundry imports official result exports. It does not run ManiSkill, collect PPO/oracle trajectories, or pick RL vs VLA for you — declare that on the export.
Dimensions
- Object memoryKindCategory
ICLR 2026 RL suite: remember object identity under partial observability.
- Spatial memoryKindCategory
Locate occluded objects and recall prior layouts.
- Sequential memoryKindCategory
Reproduce a required action order over a long horizon.
- Memory capacityKindCategory
How much earlier information the agent must hold to succeed.
- VLA Short / Medium / LongKindSplit
MIKASA-Robo-VLA groups 90 language-conditioned tasks into three horizon splits (25–2160 steps).
Data composition
- Size
AIRI / MIPT / HSE tabletop memory bench on ManiSkill. ICLR 2026 paper: 32 RL tasks in 12 groups across four memory types. The later VLA release grows to 90 language-conditioned tasks (10 memory types) with 22,500 oracle trajectories. WorldFoundry does not pick a release for you — declare RL vs VLA on the export.
- Sources
github.com
- Splits
eval
- Modalities
language · vision · action · state
- License
upstream_terms
- Notes
Paper: arXiv:2502.10550 (OpenReview 9cLPurIZMj). WorldFoundry imports official result files only.
Metrics
Metric
- DirectionHigher is better
success_ratePrimary episode success over imported rollouts.
PrimarySuccess Rate
- DirectionHigher is better
task_successPer-task success aggregate across the named memory group.
- DirectionHigher is better
episode_successPer-episode success indicator aggregate.
- DirectionHigher is better
rewardMean episode reward / return (dense rewards exist in the VLA release).
Leaderboard
The MIKASA paper catalogs 32 memory tasks (Table 1) and reports PPO-MLP / PPO-LSTM as learning curves (Figures 4–9), including a 100% oracle-state ceiling. There is no method×score ranking table to ingest, and no author-maintained live board. Memory, Benchmark & Robots (2025).
How to run
worldfoundry-eval zoo benchmark-run \
  --benchmark-id mikasa \
  --mode official-validation \
  --official-results-path <official_results.json> \
  --output-dir tmp/mikasa/official-validation \
  --json
Optional WORLDFOUNDRY_MIKASA_ROOT points at a local runtime/repo. Default import path: WORLDFOUNDRY_MIKASA_RESULTS_PATH. Manifest: worldfoundry/data/benchmarks/tasks/external/mikasa.yaml. Outputs: scorecard.json (primary success_rate), raw_results.jsonl, evaluation/summary.json.