Physics-IQ Original
Physics-IQ (Google DeepMind) asks whether a video model continues real physics, not whether the pixels look pretty. Each item shows a filmed scene; the model must generate the next 5 seconds. The published protocol has 66 scenarios × 2 views (396 items). WorldFoundry's contract tracks a 198-video single-pass split. Scoring compares the continuation to the real future with motion-mask spatial / spatiotemporal agreement and an MSE penalty, then aggregates into physics_iq_score (official final_score_orig). The current official code also emits a component-clipped physics_iq_stable_score.
Paper: Physics-IQ. Project: physics-iq.github.io. Code: google-deepmind/physics-IQ-benchmark.
Unlike the manipulation importers on this hub, WorldFoundry ships the scoring runtime in tree (run_physics_iq_official_runner.py, shared with physics-iq-verified via --protocol) plus prompt/scenario metadata under worldfoundry/data/benchmarks/assets/physics-iq. Official media (real videos, masks, conditioning frames) still download from DeepMind — they are not in the repo. Physics-IQ Verified uses a different dataset; the two are not interchangeable.
Dimensions
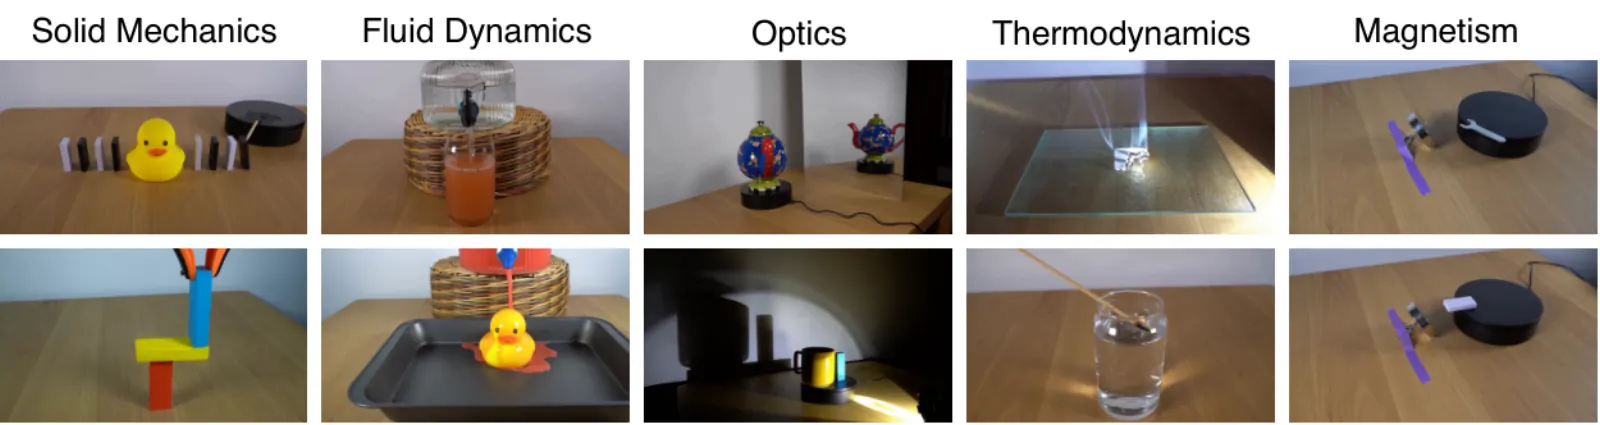
- Solid mechanicsKindCategory
Rigid contact, collisions, and object permanence in real filmed scenes.
- FluidsKindCategory
Pours, splashes, and other fluid continuations.
- OpticsKindCategory
Reflections, refractions, and lighting-dependent motion.
- ThermodynamicsKindCategory
Melting, smoke, and heat-related change.
- MagnetismKindCategory
Magnetic attraction/repulsion filmed in the official set.
- Single-pass 198-video splitKindSplit
WorldFoundry tracks 198 generated 5-second continuations (66 scenarios × views in the released protocol; published papers often average multiple runs).
Data composition
- Size
396 test items in the published protocol (66 real physics scenarios × 2 views). WorldFoundry's in-tree scorer tracks a 198-video single-pass split of 5-second continuations. Official media (real videos, masks, conditioning frames) are downloaded separately from Google DeepMind — not redistributed here.
- Sources
github.com
- Modalities
image · video
- Notes
Original reference videos and masks are officially distributed through Google Cloud Storage and prepared externally; the separate Physics-IQ Verified Hugging Face dataset is not interchangeable.
Metrics
Metric
- DirectionHigher is better
physics_iq_scoreOriginal global-aggregation score (official final_score_orig).
PrimaryPhysics-IQ Score
- DirectionHigher is better
physics_iq_stable_scoreComponent-clipped stable score emitted by the current official implementation.
- DirectionHigher is better
physics_iq_spatiotemporalSpatiotemporal IoU: where and when motion happens vs. the real continuation.
- DirectionHigher is better
physics_iq_spatialSpatial IoU: where action happens, regardless of timing.
- DirectionHigher is better
physics_iq_weighted_spatialWeighted spatial IoU: where and how much action happens.
- DirectionLower is better
physics_iq_mse_penaltyPixel-wise MSE penalty against the real continuation.
Leaderboard
Official live board, embedded on this page. Not WorldFoundry-run scores. physics-iq.github.io (synced from the DeepMind README).
How to run
Import an existing raw_metrics.csv:
worldfoundry-eval zoo benchmark-run \
  --benchmark-id physics-iq \
  --mode official-validation \
  --official-results-path <raw_metrics.csv> \
  --output-dir tmp/physics-iq/official-validation \
  --json
Recompute from 198 generated continuations named by official scenario ids:
export WORLDFOUNDRY_GENERATED_ARTIFACT_DIR=/path/to/physics-iq/generated_videos
${WORLDFOUNDRY_UNIFIED_PYTHON} \
  worldfoundry/evaluation/tasks/execution/runners/physics_iq/run_physics_iq_official_runner.py \
  --protocol physics-iq \
  --run-official \
  --dataset-root /path/to/physics-iq-benchmark \
  --generated-artifact-dir "${WORLDFOUNDRY_GENERATED_ARTIFACT_DIR}" \
  --output-dir tmp/physics-iq/official-run \
  --strict \
  --json
--strict fails on missing scenario videos. --generated-mask-dir can supply precomputed masks; otherwise masks come from the real videos. Outputs include scorecard.json (primary physics_iq_score), raw_metrics.csv, official_metrics.json, and per-sample rows when the source exposes them.