
VideoPhy2
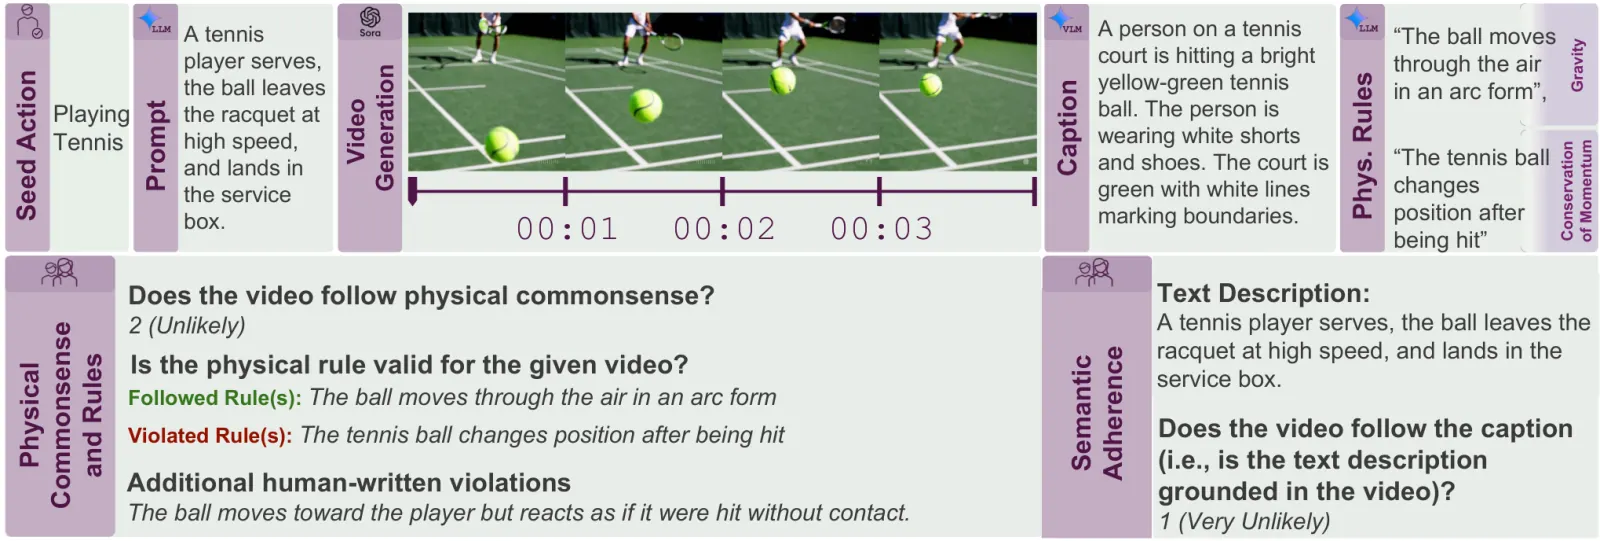
VideoPhy2 (UCLA and Google DeepMind) is the action-centric successor to VideoPhy. The prompt suite focuses on harder physical activities and object interactions (200 claimed actions). AutoEval adds rule-level judgements: which physical rules apply, and whether each is followed or violated (rule_followed_rate), alongside Semantic Adherence, Physical Commonsense, and primary Joint Score.
Paper: VideoPhy-2. Project: videophy2.github.io. Code: Hritikbansal/videophy.
WorldFoundry bundles the prompt list and drives the in-tree AutoEval judge (--autoeval-checkpoint, optional --autoeval-lora-checkpoint). Official scoring path is present; full 200-prompt reproduction is pending. Weights are caller-supplied.
Dimensions
- Action-centric promptsKindSuite
Harder physical activities and object interactions; catalog claims 200 actions.
- Rule-level AutoEvalKindAxis
Which physical rules apply and whether each is followed (rule_followed_rate).
Data composition
- Size
Action-centric successor to VideoPhy. 200 claimed actions. AutoEval adds rule-level judgements plus SA/PC/Joint. Official scoring path present; full 200-prompt reproduction pending.
- Sources
videophysics/videophy2_test · videophysics/videophy2_train · github.com
- Modalities
text · video
- License
MIT
- Notes
AutoEval base + optional LoRA checkpoints are caller-supplied.
Metrics
Metric
- DirectionHigher is better
semantic_adherenceSemantic Adherence normalized benchmark score.
- DirectionHigher is better
physical_commonsensePhysical Commonsense normalized benchmark score.
- DirectionHigher is better
joint_scoreJoint Score normalized benchmark score.
PrimaryJoint Score
- DirectionHigher is better
rule_followed_rateFraction of determined physical rules judged as followed rather than violated.
Leaderboard
Official live board, embedded on this page. Not WorldFoundry-run scores. videophy2.github.io.
How to run
worldfoundry-eval zoo benchmark-run \
  --benchmark-id videophy2 \
  --mode official-validation \
  --official-results-path <official_results.json> \
  --generated-artifact-dir <generated_videos> \
  --output-dir tmp/videophy2/official-validation \
  --json
${WORLDFOUNDRY_UNIFIED_PYTHON} \
worldfoundry/evaluation/tasks/execution/runners/videophy2/run_videophy2_official_runner.py \
--run-official \
--generated-artifact-dir "${WORLDFOUNDRY_GENERATED_ARTIFACT_DIR}" \
--autoeval-checkpoint /path/to/videophy2_autoeval \
--output-dir tmp/videophy2/official \
--jsonEnv: WORLDFOUNDRY_VIDEOPHY2_RESULTS_PATH, WORLDFOUNDRY_VIDEOPHY2_JUDGE_BACKEND. Prompt list: worldfoundry/data/benchmarks/assets/videophy2/prompts.json. Shared asset: videophy2_dataset_assets.
In-tree pointers: worldfoundry/data/benchmarks/tasks/external/videophy2.yaml, worldfoundry/evaluation/tasks/execution/runners/videophy2.
Outputs include scorecard.json (primary joint_score).