
VBench
VBench (S-Lab, NTU and Shanghai AI Laboratory) decomposes text-to-video quality into 16 dimensions, each scored by a dedicated perception model rather than one embedding distance. Three groups:
- Temporality — subject / background consistency, flicker, motion smoothness, dynamic degree.
- Frame quality — aesthetic quality, imaging quality.
- Semantics / text alignment — object class, multiple objects, human action, color, spatial relationship, scene, appearance style, temporal style, overall consistency.
The official total is a 4× quality + 1× semantic mix (overall_quality). WorldFoundry also emits temporal_quality, frame_quality, and text_alignment aggregates.
Paper: VBench. Project: vchitect.github.io/VBench-project. Code: Vchitect/VBench (Apache-2.0). Prompt suite in tree: worldfoundry/data/benchmarks/assets/vbench/VBench_full_info.json (946 rows). VBench-2.0 is a later faithfulness suite; the two are not interchangeable.
WorldFoundry vendors the official runtime. Two modes: custom_input (any video folder; text-dependent dims need --prompt / --prompt-file) and vbench_standard (official names "{prompt}-{index}.mp4", five samples per prompt, index in 0..4). Bounded GPU validation covers aesthetic_quality only.
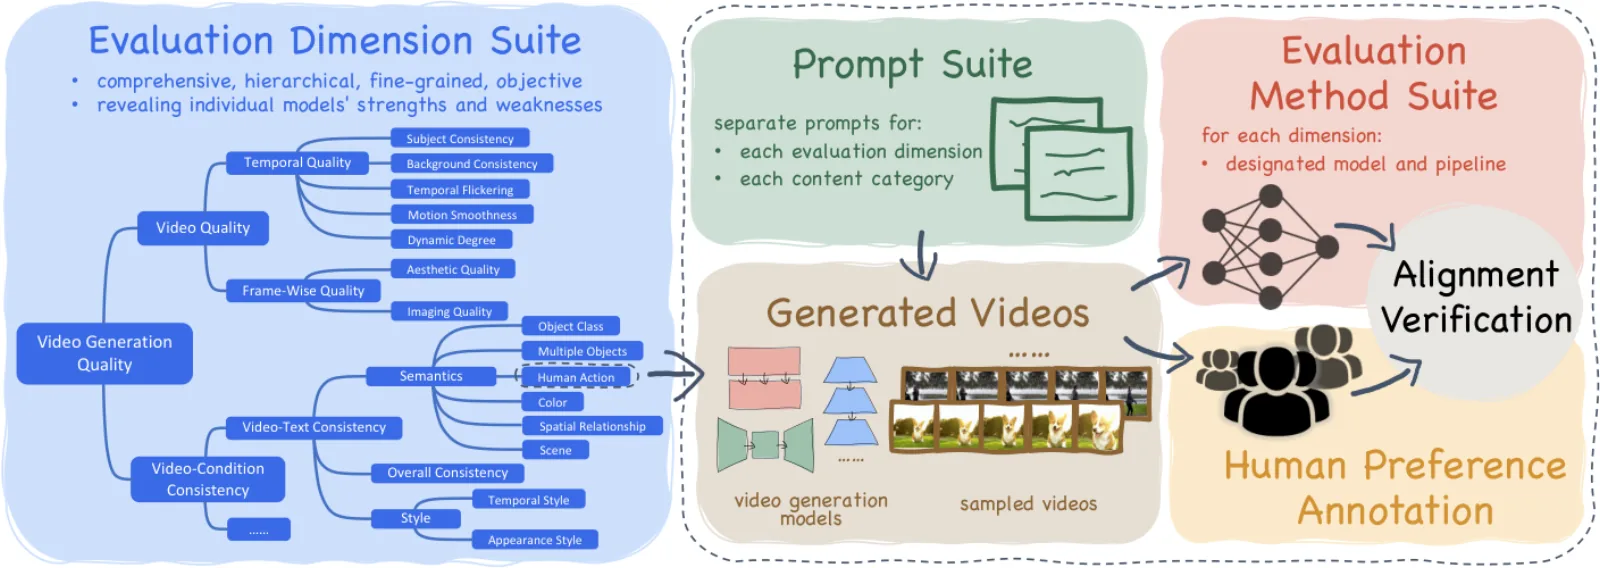
Dimensions
- Temporal qualityKindAxis
Subject/background consistency, flicker, motion smoothness, dynamic degree.
- Frame qualityKindAxis
Aesthetic quality and imaging quality.
- Semantics / text alignmentKindAxis
Object class, multiple objects, human action, color, spatial relationship, scene, appearance/temporal style, overall consistency.
Data composition
- Size
Official VBench_full_info.json: 946 prompt rows across 16 dimensions. vbench_standard expects five samples per prompt named {prompt}-{index}.mp4.
- Sources
github.com
- Modalities
text · video
- License
apache-2.0
- Notes
WorldFoundry vendors the official runtime. Bounded GPU validation covers aesthetic_quality only. No public Hugging Face dataset is required.
Metrics
Metric
- DirectionHigher is better
overall_qualityOfficial-style final VBench aggregate: 4x quality score plus 1x semantic score.
PrimaryOverall Quality
- DirectionHigher is better
temporal_qualityWorldFoundry aggregate of VBench temporal and consistency dimensions.
- DirectionHigher is better
frame_qualityWorldFoundry aggregate of VBench aesthetic and imaging quality dimensions.
- DirectionHigher is better
text_alignmentOfficial-style semantic aggregate over VBench prompt-alignment dimensions.
- DirectionHigher is better
subject_consistencyWhether the main subject stays the same across frames.
- DirectionHigher is better
background_consistencyWhether the background stays stable across frames.
- DirectionHigher is better
temporal_flickeringFlicker / high-frequency temporal instability.
- DirectionHigher is better
motion_smoothnessWhether motion is smooth rather than jittery.
- DirectionHigher is better
dynamic_degreeHow much genuine motion the clip contains.
- DirectionHigher is better
aesthetic_qualityFrame-wise aesthetic score. Bounded official component verified in tree.
- DirectionHigher is better
imaging_qualityFrame-wise imaging / distortion quality.
- DirectionHigher is better
object_classWhether requested object classes appear.
- DirectionHigher is better
multiple_objectsWhether multiple requested objects co-occur.
- DirectionHigher is better
human_actionWhether the requested human action is realized.
- DirectionHigher is better
colorWhether requested colors bind to the right objects.
- DirectionHigher is better
spatial_relationshipWhether requested spatial relations hold.
- DirectionHigher is better
sceneWhether the requested scene type is depicted.
- DirectionHigher is better
appearance_styleAppearance-style alignment to the prompt.
- DirectionHigher is better
temporal_styleTemporal-style / motion-style alignment to the prompt.
- DirectionHigher is better
overall_consistencyOverall video–prompt consistency.
Leaderboard
Official live board, embedded on this page. Not WorldFoundry-run scores. Hugging Face Space (Vchitect).
How to run
Catalog-recorded bounded command:
${WORLDFOUNDRY_UNIFIED_PYTHON} \
  worldfoundry/evaluation/tasks/execution/runners/vbench/run_vbench_official_runner.py run \
  --mode custom_input \
  --dimension aesthetic_quality
Score one dimension on a custom folder:
${WORLDFOUNDRY_UNIFIED_PYTHON} \
  worldfoundry/evaluation/tasks/execution/runners/vbench/run_vbench_official_runner.py run \
  --mode custom_input \
  --dimension subject_consistency \
  --videos-path "${WORLDFOUNDRY_GENERATED_ARTIFACT_DIR}" \
  --output-dir tmp/vbench/custom \
  --json
Import an upstream full_json directory instead of re-running evaluators:
${WORLDFOUNDRY_UNIFIED_PYTHON} \
  worldfoundry/evaluation/tasks/execution/runners/vbench/run_vbench_official_runner.py run \
  --from-upstream-results /path/to/vbench_full_json_dir \
  --output-dir tmp/vbench/imported \
  --json
--load-ckpt-from-local forces local checkpoint resolution. Env: WORLDFOUNDRY_VBENCH_ROOT, WORLDFOUNDRY_GENERATED_ARTIFACT_DIR, WORLDFOUNDRY_VBENCH_CACHE_DIR. Shared stack: vbench_perception_metric_stack.
In-tree pointers:
worldfoundry/data/benchmarks/tasks/external/vbench.yaml
worldfoundry/evaluation/tasks/execution/runners/vbench/runtime
worldfoundry/data/benchmarks/assets/vbench/VBench_full_info.json
Outputs include scorecard.json (primary overall_quality), raw_metric_table.jsonl, and captured upstream logs.