VLABench
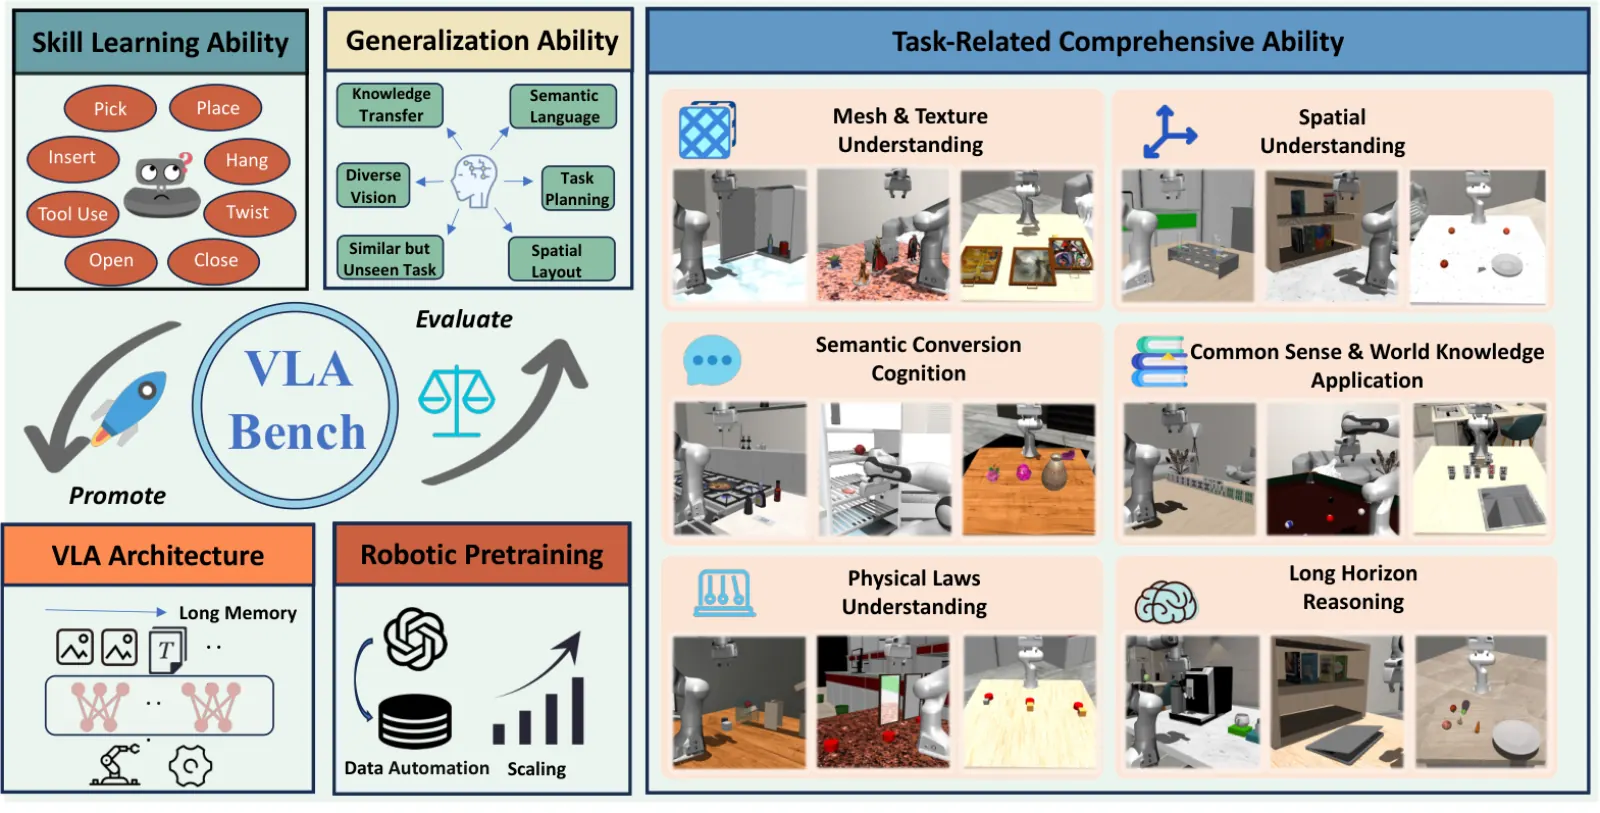
VLABench (OpenMOSS, Fudan University) benchmarks language-conditioned manipulation that needs world knowledge and multi-step reasoning, not just instruction following. Official size: 100 task categories and 2,000+ objects in MuJoCo, probing mesh / texture understanding, spatial and semantic reasoning, physical-law understanding, and long-horizon planning for both VLA policies and VLM planners.
Paper: VLABench. Code: OpenMOSS/VLABench. License: upstream terms.
WorldFoundry is an official-results importer. Simulator execution, policy loading, and rollout collection stay upstream. Scorecard primary: success_rate.
Dimensions
- 100 language-conditioned categoriesKindSuite
World knowledge and multi-step reasoning in MuJoCo; 2,000+ objects.
Data composition
- Size
Fudan OpenMOSS language-conditioned manipulation bench: 100 task categories, 2,000+ objects in MuJoCo. For VLA policies and VLM planners.
- Sources
github.com
- Modalities
language · vision · action · state
- License
upstream_terms
- Notes
WorldFoundry imports official rollouts. It does not boot MuJoCo or load policies.
Metrics
Metric
- DirectionHigher is better
success_ratePrimary episode success rate over evaluated rollouts.
PrimarySuccess Rate
- DirectionHigher is better
task_successPer-task success aggregate.
- DirectionHigher is better
episode_successPer-episode success indicator aggregate.
- DirectionHigher is better
rewardMean episode reward / return.
Leaderboard
Results from the paper (not a live board; not WorldFoundry-run scores). Official VLABench paper table (arxiv 2412.18194). Catalog abs 2502.09858 is a different paper. VLABench: A Large-Scale Benchmark for Language-Conditioned Robotics Manipulation with Long-Horizon Reasoning Tasks (2024).
| Model | Seen-split average success |
|---|---|
| RDT-1B (base) | 15.37 |
| OpenVLA (base) | 11.74 |
| Octo (base) | 1.34 |
How to run
worldfoundry-eval zoo benchmark-run \
  --benchmark-id vlabench \
  --mode official-validation \
  --official-results-path <official_results.json> \
  --output-dir tmp/vlabench/official-validation \
  --json
Default import: WORLDFOUNDRY_VLABENCH_RESULTS_PATH. Optional root: WORLDFOUNDRY_VLABENCH_ROOT.
In-tree pointer: worldfoundry/data/benchmarks/tasks/external/vlabench.yaml.
Outputs include scorecard.json (primary success_rate), raw_results.jsonl, and evaluation/summary.json.