WorldBench
On this page
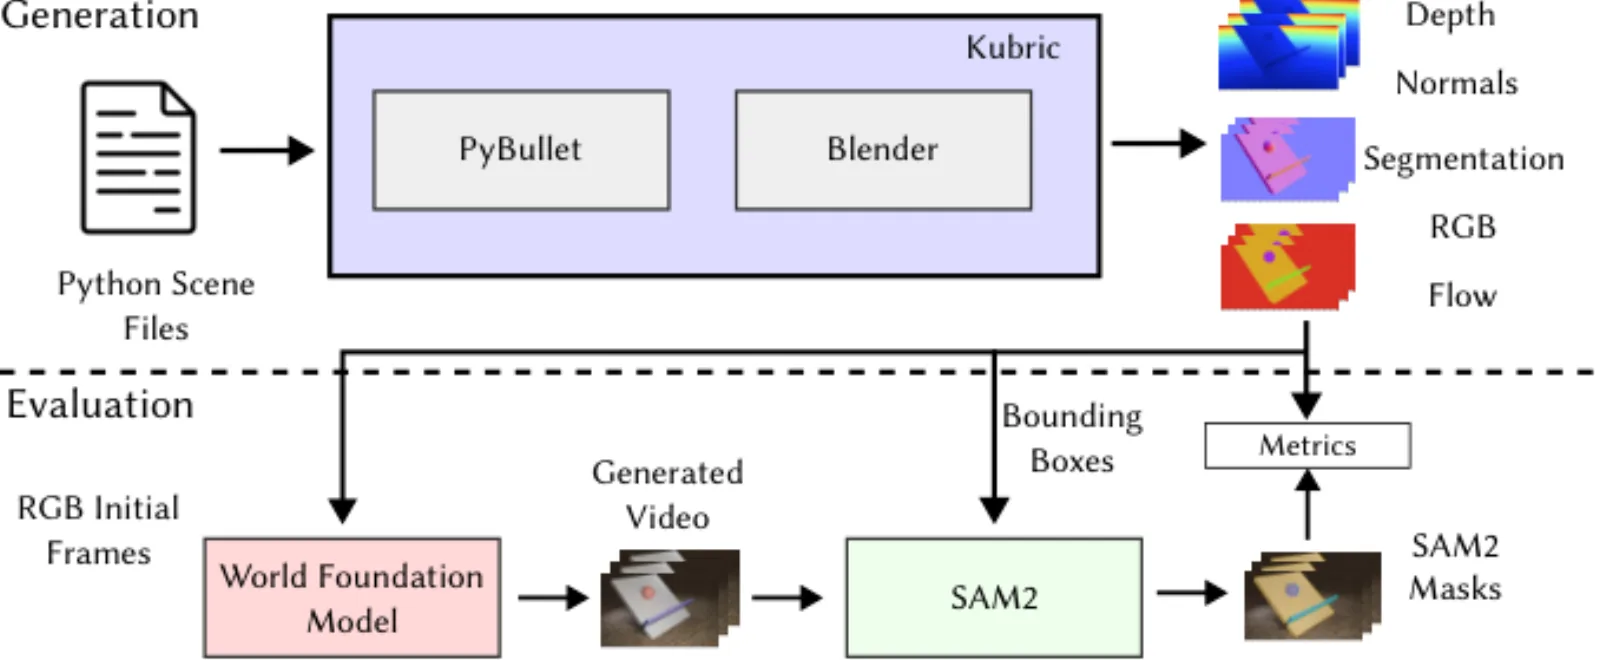
WorldBench (UCLA, with Sony AI, Yale, and DEVCOM ARL) diagnoses how close world models are to physics. Kubric (PyBullet + Blender) renders 425 physically accurate scenes across four concepts — motion physics, object permanence, support relations, scale / perspective — with ground-truth depth, normals, segmentation, and flow. Models generate continuations from initial frames; SAM2 tracks first-frame boxes and masks are compared to simulation (foreground mIoU, background RMSE). A textual subset adds multiple-choice and yes/no QA.
The public evaluator calls Dice “mIoU”. WorldFoundry reports conventional foreground_miou and the release’s foreground_dice compatibility value separately. The inspected HF tree currently has 375 scene directories (15 scenarios × 25) versus the paper’s 425.
Paper: WorldBench. Project: world-bench.github.io. Data: worldbenchmark/IntuitivePhysics. Dataset and evaluator declare no redistribution license.
WorldFoundry implements an in-tree, model-backed runner. Runtime environments still record: no confirmed redistributable official raw-video evaluator, and official-run from videos is not a release claim. Import via WORLDFOUNDRY_WORLDBENCH_RESULTS_PATH is the supported compatibility path.
Dimensions
- Video / SAM2 trackKindTrack
SAM2 tracks first-frame boxes; masks vs Kubric GT (foreground mIoU, background RMSE).
- Text QA trackKindTrack
Multiple-choice and yes/no questions over four physics concepts.
Data composition
- Size
UCLA diagnostic physics bench. Paper: 425 Kubric scenes (motion, permanence, support, scale). Inspected HF tree currently has 375 scene directories. No redistribution license. Public evaluator names Dice as mIoU.
- Sources
worldbenchmark/IntuitivePhysics
- License
not_provided
- Notes
In-tree runner exists, but runtime environments record no confirmed redistributable official raw-video evaluator. official-run from videos is not a release claim.
Metrics
Metric
- DirectionHigher is better
foreground_miouConventional per-object IoU averaged across objects, frames, and scenes.
PrimaryForeground mIoU
- DirectionHigher is better
foreground_diceCompatibility value computed by the public release while naming it mIoU.
- DirectionLower is better
background_rmseRGBA RMSE over pixels labeled as background in the ground-truth segmentation.
- DirectionHigher is better
text_based_accuracyExact normalized answer accuracy over available WorldBench textual questions.
- DirectionHigher is better
multiple_choice_accuracyAccuracy over questions containing an explicit Options list.
- DirectionHigher is better
binary_accuracyAccuracy over WorldBench yes/no questions.
Leaderboard
Results from the paper (not a live board; not WorldFoundry-run scores). WorldBench: Benchmarking Physical Understanding of World Models by Isolating Physics Concepts (2026).
| Model | Average error (lower is better) |
|---|---|
| Cosmos-2.5 2B | 0.217 |
| Hunyuan Video 13B | 0.2275 |
| Cosmos-1 DM 7B | 0.231 |
| Cosmos-2 2B | 0.232 |
| Wan 2.2 5B | 0.253 |
| Cosmos-2 14B | 0.274 |
| Cosmos-1 AR 5B | 0.298 |
How to run
hf download worldbenchmark/IntuitivePhysics --repo-type dataset \
  --local-dir cache/worldfoundry/data/hfd_datasets/worldbenchmark/IntuitivePhysics

${WORLDFOUNDRY_UNIFIED_PYTHON} \
  worldfoundry/evaluation/tasks/execution/runners/worldbench/run_worldbench_official_runner.py \
  --run-official \
  --video-only \
  --dataset-root "${WORLDFOUNDRY_WORLDBENCH_DATASET_ROOT}" \
  --generated-video-dir "${WORLDFOUNDRY_GENERATED_ARTIFACT_DIR}" \
  --sam2-checkpoint "${WORLDFOUNDRY_WORLDBENCH_SAM2_CKPT}" \
  --output-dir tmp/worldbench/video \
  --json
--predicted-mask-dir skips SAM2 when masks already exist. --text-only plus --answer-manifest covers QA. Frame knobs: --ground-truth-start-frame, --generated-skip-frames. Shared assets: worldbench_dataset_assets, facebook/sam2.1-hiera-large.
In-tree pointers: worldfoundry/data/benchmarks/tasks/external/worldbench.yaml, worldfoundry/evaluation/tasks/execution/runners/worldbench.
Outputs include scorecard.json (primary foreground_miou) and worldbench_evaluation.json.
Dataset, videos, and frame alignment
The in-tree runtime does not import an upstream checkout. SAM2 comes from worldfoundry.base_models.perception_core.segment.sam2. Dataset root must be the public HF layout:
<dataset>/
  scenes/<group>/<scenario>/<scene>/
    rgba_00000.png
    segmentation_00000.png
    …
  textual_questions/*.json
Generated continuations can mirror scene ids:
<generated>/<group>/<scenario>/<scene>.mp4
<generated>/<group>/<scenario>/<scene>/output.mp4
<generated>/<group>/<scenario>/<scene>/00000.png
Any other video layout needs --video-manifest (JSON / JSONL / CSV / TSV) with sample_id and video_path. Text predictions use --answer-manifest. Stable question_id is <question-file-stem>:<row>; or include both video_name and question because some videos have two questions.
The bench uses nine conditioning frames. By default, generated frame 0 aligns to GT frame 9 and 24 continuation frames are scored. If the model prepends those nine frames, pass --generated-skip-frames 9. Defaults live in worldfoundry/data/benchmarks/assets/worldbench/evaluator.yaml.
Raw video scoring defaults to facebook/sam2.1-hiera-large. Set WORLDFOUNDRY_WORLDBENCH_SAM2_CKPT to a local file, otherwise the HF cache resolver is used. Import-only path: --official-results-path without --run-official.
Use worldfoundry-unified-cu128. A successful in-tree run is integration evidence, not leaderboard_valid, until full-dataset numerical parity is audited. The inspected upstream pin WorldBenchmark/worldbench_eval@4575a164… has no license file and a broken public evaluator; WorldFoundry keeps provenance in the catalog YAML, not a SOURCE.json.