
WorldModelBench
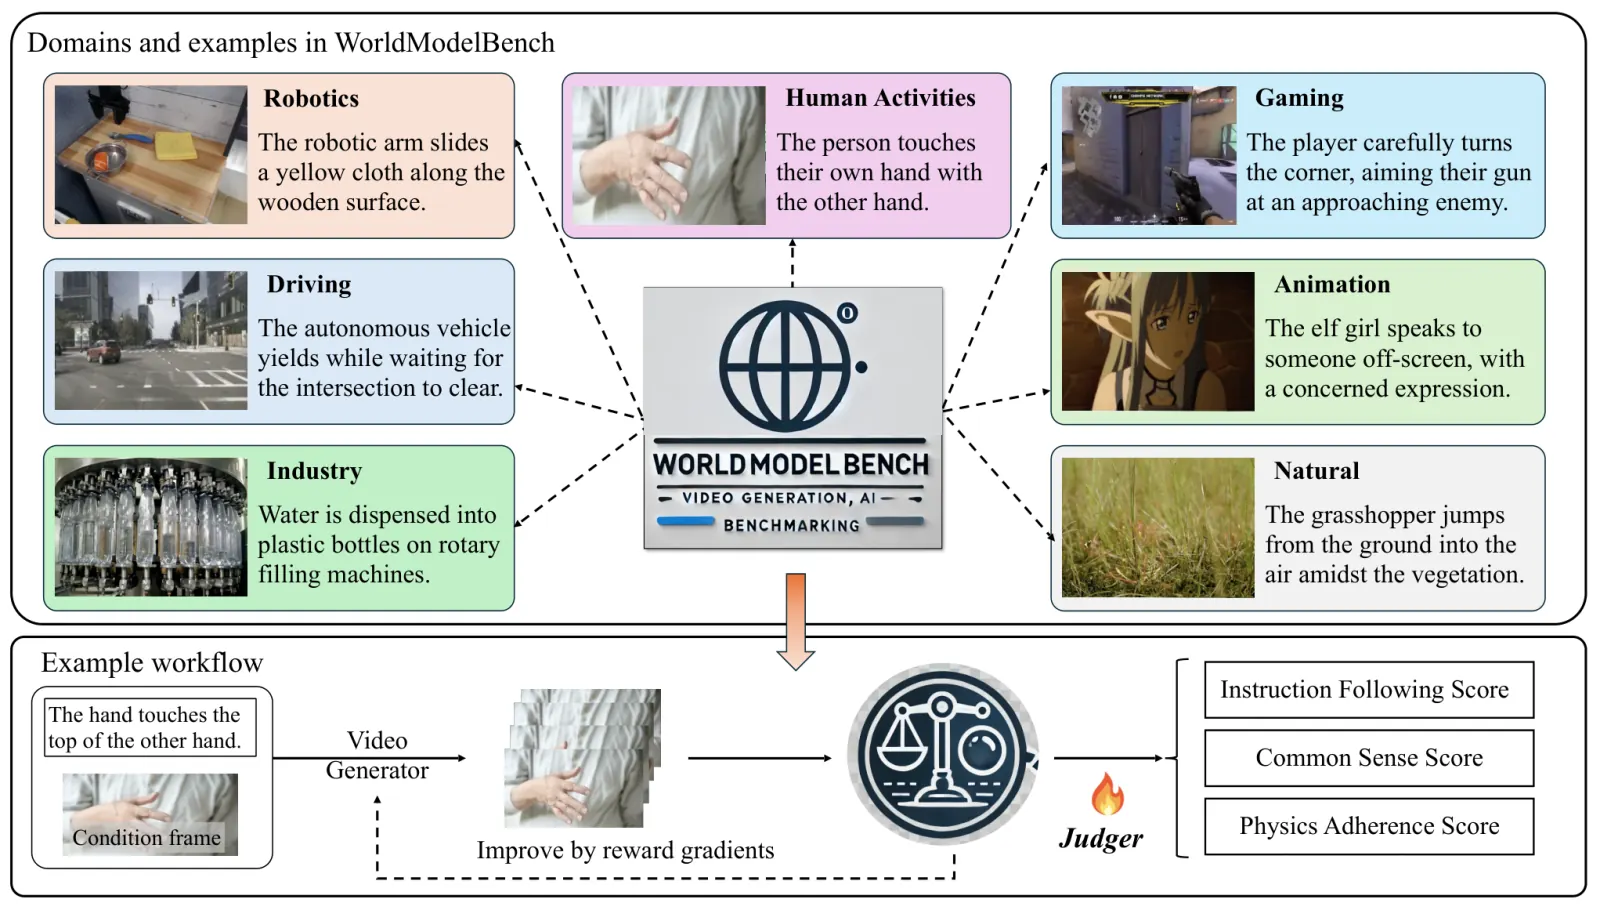
WorldModelBench (NVIDIA, UC Berkeley, UC San Diego, MIT; NeurIPS 2025) judges video generators as world models across 7 application domains / 56 subdomains. Official size: 350 instances, calibrated against 67K crowd-sourced human labels. Three families:
- Instruction following
- Common-sense reasoning
- Physics adherence (e.g. mass-conservation violations such as irregular size changes)
The official judge is a fine-tuned 2B VILA-family multimodal model that the paper reports outperforms GPT-4o at detecting world-modeling violations. world_model_average aggregates public families.
Paper: WorldModelBench. Project: worldmodelbench-team.github.io. Code: WorldModelBench-Team/WorldModelBench. Data: Efficient-Large-Model/worldmodelbench.
WorldFoundry checks in upstream evaluation.py and the 350-instance manifest. Result import and manifest coverage checks are verified; full judge-checkpoint execution is not. Leaderboard answers are withheld upstream.
Dimensions
- Instruction followingKindAxis
Does the rollout follow the instruction?
- Common senseKindAxis
Common-sense reasoning over 7 domains / 56 subdomains.
- Physics adherenceKindAxis
E.g. mass-conservation violations such as irregular size changes.
Data composition
- Size
NeurIPS 2025 world-model judging suite. 350 instances, 67K crowd labels, fine-tuned 2B VILA judge. Leaderboard answers withheld upstream.
- Sources
Efficient-Large-Model/worldmodelbench · github.com
- Modalities
text · image · video
- License
unknown_pending_review
- Notes
Result import and manifest coverage checks are verified. Full judge-checkpoint execution is not.
Metrics
Metric
- DirectionHigher is better
instruction_followingWorldModelBench instruction-following score.
- DirectionHigher is better
common_senseWorldModelBench common-sense reasoning score.
- DirectionHigher is better
physical_adherenceWorldModelBench physical-adherence score.
- DirectionHigher is better
world_model_averageNormalized aggregate across public WorldModelBench metric families.
PrimaryWorld Model Average
Leaderboard
Official live board, embedded on this page. Not WorldFoundry-run scores. worldmodelbench-team.github.io.
How to run
hf download Efficient-Large-Model/worldmodelbench --repo-type dataset \
  --local-dir cache/worldfoundry/data/hfd_datasets/Efficient-Large-Model/worldmodelbench

worldfoundry-eval zoo benchmark-run \
  --benchmark-id worldmodelbench \
  --mode official-validation \
  --official-results-path <official_results.json> \
  --benchmark-data-root <worldmodelbench_data_root> \
  --generated-artifact-dir <generated_videos> \
  --output-dir tmp/worldmodelbench/official-validation \
  --json
Official-run drives evaluation.py with WORLDFOUNDRY_WORLDMODELBENCH_JUDGE (VILA checkpoint or HF model id). The wrapper validates accs/preds shapes against N, 2N, and 5N category lengths and records 350-instance video coverage. Env: WORLDFOUNDRY_WORLDMODELBENCH_RESULTS_PATH, WORLDFOUNDRY_WORLDMODELBENCH_DATA_ROOT. Shared asset: worldmodelbench_dataset_assets. Manifest: worldfoundry/data/benchmarks/assets/worldmodelbench/worldmodelbench.json.
In-tree pointers: worldfoundry/data/benchmarks/tasks/external/worldmodelbench.yaml, worldfoundry/evaluation/tasks/execution/runners/worldmodelbench/runtime/evaluation.py.
Outputs include scorecard.json (primary world_model_average) and judge_responses.jsonl.