RBench
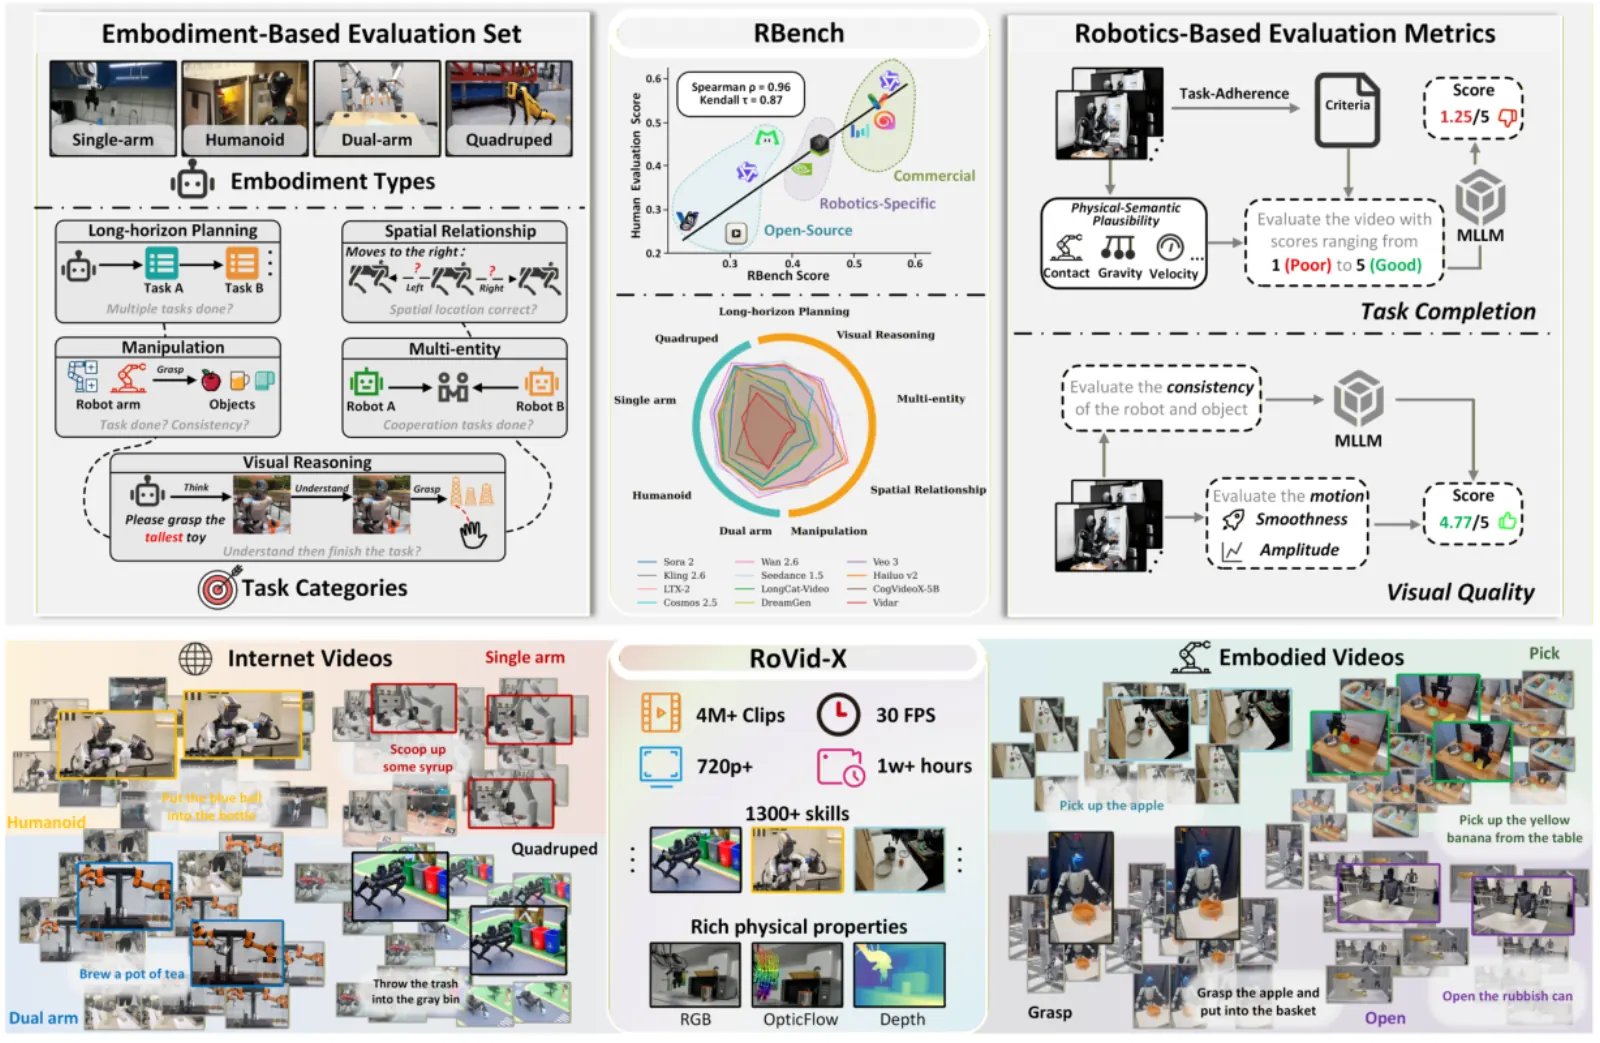
RBench (ReVidgen; Peking University DAGroup and ByteDance Seed; ICML 2026) evaluates robot-oriented image-to-video. 650 image-text cases:
- Task track — 250 cases: common manipulation, long-horizon planning, multi-entity collaboration, spatial relationship, visual reasoning.
- Embodiment track — 400 cases: dual-arm, humanoid, single-arm, quadruped.
Videos are scored by a VLM judge (GPT or Qwen3-VL) on physical plausibility, task adherence, and stability, plus operator metrics (motion smoothness / amplitude) from GroundingDINO / SAM2 / CoTracker / Q-Align. The paper reports 0.96 Spearman with humans. Companion training data: RoVid-X (4M annotated robot clips). License: CC-BY-4.0.
Paper: RBench. Code: DAGroup-PKU/ReVidgen. Data: DAGroup-PKU/RBench.
WorldFoundry reproduces official eval/4_embodiments and eval/5_tasks aggregation (option-to-score mapping, min-max, PAS and consistency penalties, amplitude filter). It does not run the VLM or the operator stack. rbench_overall is a WorldFoundry composite of the two track scores, not a published RBench number. GPT and Qwen outputs are never mixed.
Dimensions
- Task trackKindTrack
250 image-text cases: common manipulation, long-horizon planning, multi-entity collaboration, spatial relationship, visual reasoning.
- Embodiment trackKindTrack
400 cases: dual-arm, humanoid, single-arm, quadruped.
Data composition
- Size
PKU / ByteDance Seed robot I2V bench (ICML 2026). 650 image-text cases. VLM + GroundingDINO/SAM2/CoTracker/Q-Align operators. CC-BY-4.0. Paper reports 0.96 Spearman with humans.
- Sources
DAGroup-PKU/RBench · DAGroup-PKU/RoVid-X · github.com
- Splits
dual_arm · humanoid · single_arm · quad · common_manipulation · long-horizon_planning · multi-entity_collaboration · spatial_relationship · visual_reasoning
- Modalities
image · text · video
- License
CC-BY-4.0
- Notes
WorldFoundry aggregates official eval/4_embodiments and eval/5_tasks trees. rbench_overall is a WorldFoundry composite, not a published RBench number. GPT and Qwen are never mixed.
Metrics
Metric
- DirectionHigher is better
rbench_overallWorldFoundry composite mean of the two official track scores; not a published RBench number.
PrimaryRBench Overall
- DirectionHigher is better
embodiment_overallTask completion and visual quality pooled across the four robot embodiments.
- DirectionHigher is better
task_completionMean of normalized physical plausibility and task adherence consistency.
- DirectionHigher is better
visual_qualityWeighted stability and smoothness score after amplitude and consistency penalties.
- DirectionHigher is better
visual_quality_base0.8 x robot subject stability + 0.2 x motion smoothness before penalties.
- DirectionHigher is better
physical_plausibilityVLM physical plausibility score normalized from the 1-5 scale.
- DirectionHigher is better
task_adherence_consistencyVLM task adherence score normalized from the 1-5 scale.
- DirectionHigher is better
robot_subject_stabilityVLM robot and object stability score normalized from the 1-15 option-mapped scale.
- DirectionHigher is better
motion_smoothnessMotion smoothness operator score.
- DirectionHigher is better
motion_amplitudeRobotic-manipulator perceptible amplitude operator score driving the PAS penalty.
- DirectionHigher is better
task_track_overallALL_TASKS_MEAN pooled over every scored video across the five task splits.
- DirectionHigher is better
common_manipulationNormalized rubric score for the common manipulation split.
- DirectionHigher is better
long_horizon_planningNormalized rubric score for the long-horizon planning split.
- DirectionHigher is better
multi_entity_collaborationNormalized rubric score for the multi-entity collaboration split.
- DirectionHigher is better
spatial_relationshipNormalized rubric score for the spatial relationship split.
- DirectionHigher is better
visual_reasoningNormalized rubric score for the visual reasoning split.
Leaderboard
Results from the paper (not a live board; not WorldFoundry-run scores). Paper human-alignment table, RBench column. Rethinking Video Generation Model for the Embodied World (2026).
| Model | RBench score |
|---|---|
| Wan 2.5 | 0.570 |
| Hailuo v2 | 0.565 |
| Veo 3 | 0.563 |
| Seedance 1.0 | 0.551 |
| Cosmos 2.5 | 0.464 |
| LongCat-Video | 0.437 |
| Wan2.1-14B | 0.399 |
| CogVideoX-5B | 0.256 |
How to run
hf download DAGroup-PKU/RBench --repo-type dataset --local-dir <rbench_data_root>

worldfoundry-eval zoo benchmark-run \
  --benchmark-id rbench \
  --mode official-validation \
  --official-results-path <rbench_results_root> \
  --result-model-id <model_id> \
  --output-dir tmp/rbench/official-validation \
  --json
--track restricts to one track. --vlm-backend selects GPT or Qwen when both trees exist. --generated-artifact-dir adds coverage reporting. Env: WORLDFOUNDRY_RBENCH_RESULTS_PATH, WORLDFOUNDRY_RBENCH_DATA_ROOT, WORLDFOUNDRY_RBENCH_VLM_BACKEND.
In-tree pointers: worldfoundry/data/benchmarks/tasks/external/rbench.yaml, worldfoundry/evaluation/tasks/execution/runners/rbench.
Outputs include scorecard.json (primary rbench_overall) and track_breakdown.json.