WorldOlympiad
On this page
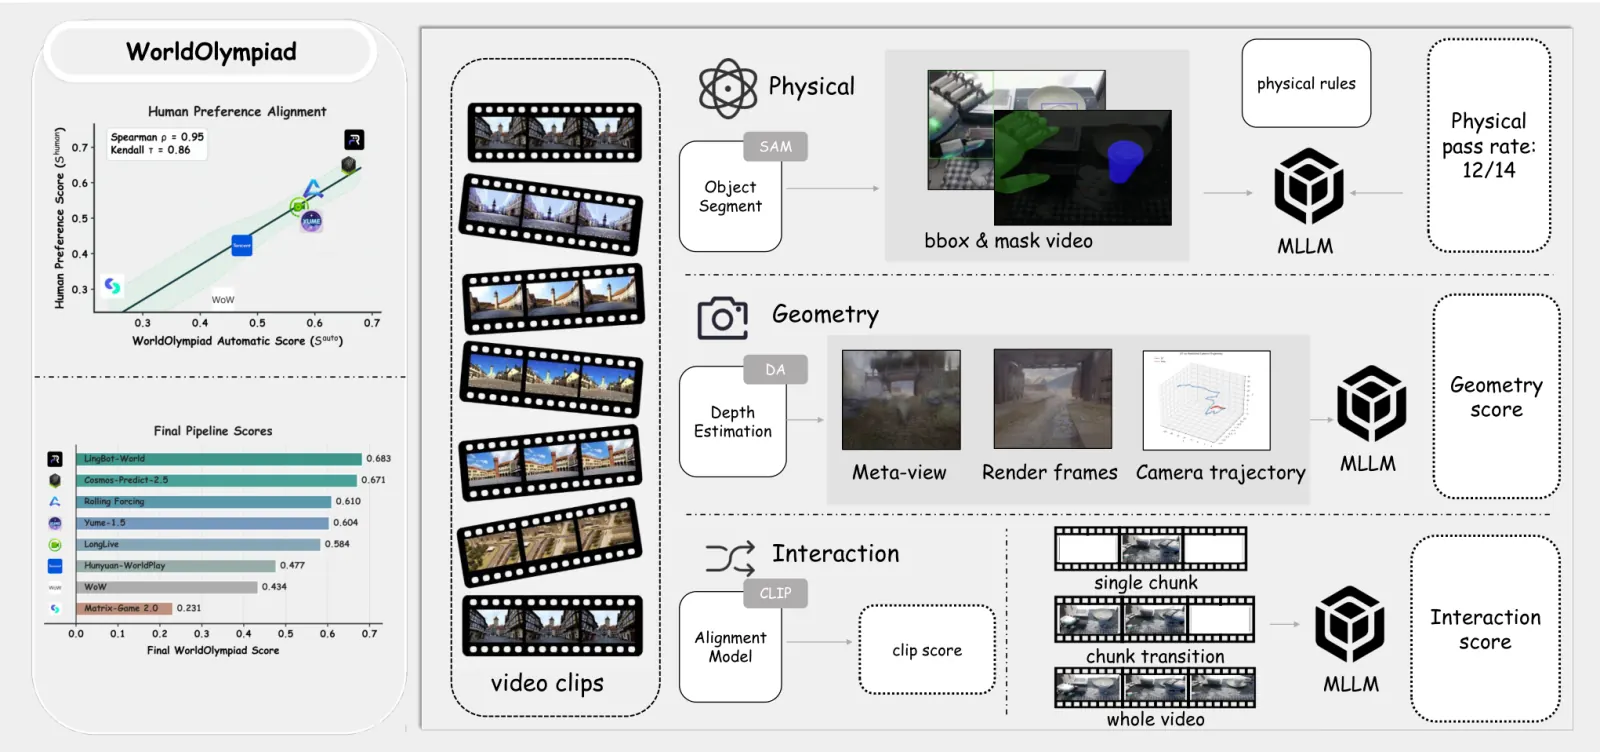
WorldOlympiad (Alibaba DAMO Academy) is a triathlon for long-video world models. Primary combined_score averages three tracks on the unit interval:
- Physical — Qwen3-VL confidence-weighted physics QA across mechanics, thermotics, material
- Interaction — per-chunk instruction following, transition smoothness, global consistency (native 0–5, then normalized)
- Geometry — Depth Anything 3 reconstruction (Gaussian splatting, meta-view, camera-trajectory alignment; native 0–3)
Paper: WorldOlympiad. Project: alibaba-damo-academy.github.io/WorldOlympiad. Code: alibaba-damo-academy/WorldOlympiad. Data: ziplab/WorldOlympiad. Upstream publishes no LICENSE at the pinned revision.
WorldFoundry checks in the official batch evaluator — no external checkout. Scored runs need --da3-src, --weights-dir (DA3 / SAM3 / QwenVL / CLIP), and running QwenVL, SAM3, and DA3 reward services. --run-official --dry-run and judge-output normalization are verified; no scored triathlon run is claimed.
--run-fixture on run_worldolympiad_official_runner.py reads the synthetic judge JSONs under worldfoundry/data/benchmarks/assets/worldolympiad/cases/ (general/case_fixture_001 all three tracks, gaming/case_fixture_002 all three tracks, embodied/case_fixture_003 with geometry skipped). Those files invent videos, prompts, questions, and scores and only match the public judge JSON shape from scripts/score_video_physical_3d.py. They are not comparable to any WorldOlympiad result.
Dimensions
- Physical trackKindTrack
Qwen3-VL confidence-weighted physics QA (mechanics, thermotics, material).
- Interaction trackKindTrack
Per-chunk instruction following, transition smoothness, global consistency (0–5).
- Geometry trackKindTrack
DA3 Gaussian splatting, meta-view, camera-trajectory alignment (0–3).
Data composition
- Size
Alibaba DAMO triathlon for long-video world models. Dataset ziplab/WorldOlympiad. Upstream publishes no LICENSE at the pinned revision. Official split cited as 1,000 videos.
- Sources
ziplab/WorldOlympiad · github.com
- Splits
general · gaming · embodied
- Modalities
text · image · video · action
- License
unlicensed_upstream
- Notes
In-tree batch plan (--run-official --dry-run) and judge-output normalization are verified. No scored triathlon run is claimed.
Metrics
Metric
- DirectionHigher is better
combined_scoreMean of the physical, interaction, and geometry track scores on the unit interval.
PrimaryCombined Triathlon Score
- DirectionHigher is better
physical_scoreConfidence-weighted compliance over the physics questions the MLLM judge marked related.
- DirectionHigher is better
physical_mechanicsPhysical score restricted to mechanics questions.
- DirectionHigher is better
physical_thermoticsPhysical score restricted to thermodynamics questions.
- DirectionHigher is better
physical_materialPhysical score restricted to material-property questions.
- DirectionHigher is better
physical_compliance_rateCorpus-wide compliant questions divided by related questions.
- DirectionHigher is better
three_d_scoreDA3 geometry score normalized from the native 0-3 range.
- DirectionHigher is better
three_d_rawSum of the Gaussian-splatting, meta-view, and camera-motion components on a 0-3 scale.
- DirectionHigher is better
gs_scoreDA3 Gaussian-splatting reconstruction quality component.
- DirectionHigher is better
meta_view_scoreDiagnostic meta-view consistency component of the geometry track.
- DirectionHigher is better
camera_motion_scoreAlignment between the recovered and reference DA3 camera trajectories.
- DirectionHigher is better
interaction_scoreVLM interaction score normalized from the native 0-5 range.
- DirectionHigher is better
interaction_rawMean of the chunk, transition, and global interaction judgements on a 0-5 scale.
- DirectionHigher is better
chunk_instruction_followingPer-chunk prompt adherence judged against the generated chunk timestamps.
- DirectionHigher is better
transition_smoothnessSmoothness across adjacent generated chunk boundaries.
- DirectionHigher is better
global_consistencyWhole-video consistency and global text alignment.
- DirectionHigher is better
clip_semantic_adherenceCLIP similarity between sampled chunk frames and their captions.
Leaderboard
Results from the paper (not a live board; not WorldFoundry-run scores). WorldOlympiad: Can Your World Model Survive a Triathlon? (2026).
| Model | All (S_all) |
|---|---|
| LingBot-Worldgaming WM | 0.683 |
| Cosmos-Predict-2.5robotics WM | 0.671 |
| Rolling Forcing | 0.610 |
| Yume-1.5 | 0.604 |
| LongLive | 0.584 |
| Hunyuan-WorldPlay | 0.477 |
| WoW | 0.434 |
| Matrix-Game 2.0 | 0.231 |
How to run
worldfoundry-eval zoo benchmark-run \
  --benchmark-id worldolympiad \
  --mode official-validation \
  --official-results-path <case_root_or_judge_json> \
  --output-dir tmp/worldolympiad/official-validation \
  --json
--official-results-path accepts a case root, a single judge JSON, summary.jsonl, or an aggregate JSON. Skip tracks with --skip-physical, --skip-interaction, --skip-3d. Env: WORLDFOUNDRY_WORLDOLYMPIAD_RESULTS_PATH, WORLDFOUNDRY_WORLDOLYMPIAD_WEIGHTS_DIR, WORLDFOUNDRY_WORLDOLYMPIAD_DA3_SRC. The runner refuses output / weights paths inside the checked-in runtime.
In-tree pointers: worldfoundry/data/benchmarks/tasks/external/worldolympiad.yaml, worldfoundry/evaluation/tasks/execution/runners/worldolympiad. Extra pip: worldfoundry/data/benchmarks/requirements/worldolympiad.txt.
Outputs include scorecard.json (primary combined_score) and per_case_metrics.jsonl.
Case layout and pipeline prefixes
Batch scoring expects one directory per case under a domain (general, gaming, embodied by default; custom roots use --root + --domain-name):
outputs_batch/<domain>/<case_id>/
  prompt.json
  ref_<case_id>.mp4
  <output_prefix>_gen_<case_id>.mp4
  <output_prefix>_gen_<case_id>_chunk_timestamps.json
Required files: prompt.json; ref_*.mp4; one generated video per pipeline; chunk timestamps named <generated-stem>_chunk_timestamps.json. Scores land next to the videos as <output_prefix>_judge_<case_id>.json. Existing judge JSON is skipped so a batch can resume; --force recomputes.
| Pipeline | Prefix | Example video |
|---|---|---|
cosmos-predict | cosmos | cosmos_gen_<case_id>.mp4 |
hunyuan-gamecraft | hunyuan_gamecraft | hunyuan_gamecraft_gen_<case_id>.mp4 |
hunyuan-worldplay | hunyuan_worldplay | hunyuan_worldplay_gen_<case_id>.mp4 |
lingbot-world | lingbot_world | lingbot_world_gen_<case_id>.mp4 |
longlive | longlive | longlive_gen_<case_id>.mp4 |
matrix-game2 | matrix_game2 | matrix_game2_gen_<case_id>.mp4 |
rolling-forcing | rolling_forcing | rolling_forcing_gen_<case_id>.mp4 |
wow | wow | wow_gen_<case_id>.mp4 |
yume1p5 | yume1p5 | yume1p5_gen_<case_id>.mp4 |
One case may hold several pipelines. --pipelines selects which prefixes to score; each gets its own judge JSON. Non-default names: --gen-pattern, --chunk-pattern, --ref-pattern, --output-name-template.
prompt.json may be a list or an object with chunks / prompts. Each item is a string or an object. Text keys: caption, prompt, text, or description. action, interval, and chunk_index are optional but recommended for interaction scoring:
[
  {
    "interval": "[00:00, 00:15)",
    "action": "turn left",
    "caption": "A vehicle drives through a cone-marked course."
  }
]
Chunk timestamps map each prompt interval onto the generated video:
{
  "version": 1,
  "fps": 28,
  "chunks": [
    {
      "chunk_index": 0,
      "source_interval": "[00:00, 00:15)",
      "frame_start": 0,
      "frame_end": 93,
      "generated_start_sec": 0.0,
      "generated_end_sec": 3.321428
    }
  ]
}
Services, GPUs, and batch outputs
Scored runs need the DA3 source tree (--da3-src, typically a Depth-Anything-3 checkout) plus DA3 / SAM3 / QwenVL / CLIP weights outside the checked-in runtime. You do not reinstall the full DA3 conda env. OpenRouter / OpenAI-compatible VLM scoring can use a .env with base_url and api_key.
Keep persistent services up, then point the official runner at their URLs:
- QwenVL:
start_qwenvl_servers.py --gpus 0,1 --ports 8008,8009 - SAM3:
start_sam3_servers.py(needs the Qwen URLs) - DA3 reward:
start_reward_3d_servers.py(needs the Qwen URLs;--no-lpipsis the usual flag)
Suggested 8-GPU split: GPUs 0–1 QwenVL, 2 SAM3, 3–4 DA3, 5–7 scoring workers.
Vendor evaluate_pipelines.py writes batch_manifests/<domain>_<pipeline>_{all,pending}.jsonl and batch_logs/<domain>_<pipeline>/ (summary_latest.jsonl, score_summary.json, score_cases.csv). Useful flags: --list-pipelines, --limit N, --dry-run, --no-summarize, --skip-pair gaming:lingbot-world. WorldFoundry --run-official --dry-run is the verified path; a scored 1,000-video triathlon is not claimed.
Lower-level vendor tools (debug only): make_manifest.py, batch_scheduler.py, summarize_scores.py, scripts/score_video_physical_3d.py. These paths are relative to worldfoundry/evaluation/tasks/execution/runners/worldolympiad/runtime/worldolympiad/.
Physical-track internals in the vendored tree: SAM3 masks / boxes on GT and generated video, then DA3 centroids in 3D for mechanics; thermotics question bank; material heuristics (color mix, dissolve, flammability, hardness / deformation) optionally mixed with a VLM. Drive them through the official runner, not those folder scripts.