
WRBench
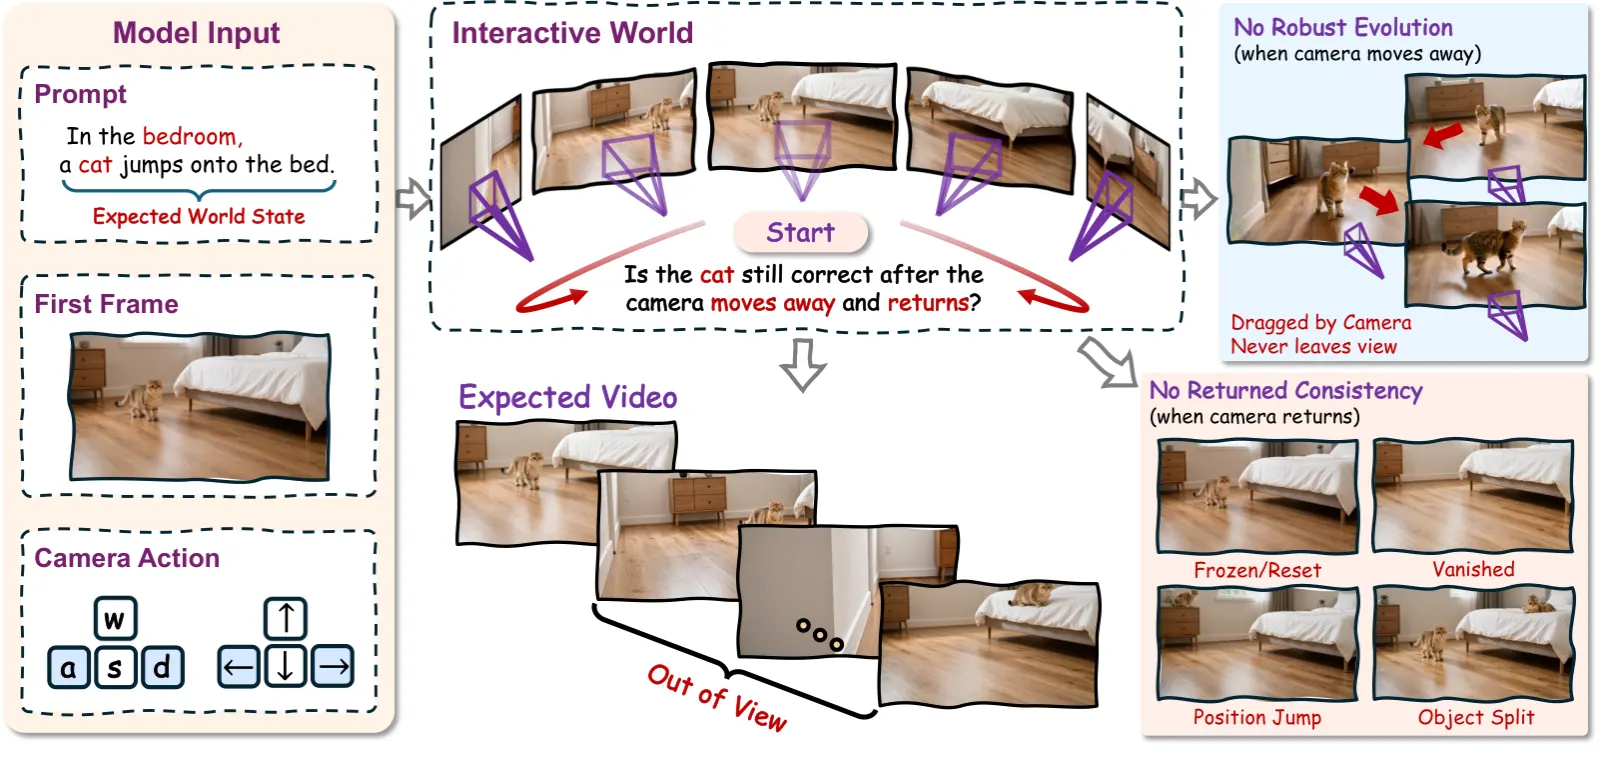
WRBench (“Current World Models Lack a Persistent State Core”; USTC and X-Humanoid / Beijing Innovation Center of Humanoid Robotics) treats camera motion as an observability intervention: an event starts, the camera looks away, and on return the bench asks whether the target advanced to the endpoint or froze. Natural-25 crosses 25 scene families with a four-level event design (spatial change × state change). The canonical camera track expands 100 semantic variants × five camera controls = 500 requests.
Hierarchical D1–D6:
- D1 — requested-camera precision / prompt-camera alignment
- D2 — visual integrity
- D3 / D4 — visible spatial / state consistency
- D5 / D6 — re-observed spatial / state consistency (aggregated only over judgeable hidden-and-returned evidence)
wrbench_average aggregates D1–D6. Paper: WRBench. Project: jinplu.github.io/WRBench. Code: JinPLu/WRBench. Data: WRBench/wrbench-natural25.
WorldFoundry checks in the complete package and Natural-25 assets. Natural-25 request materialization and result normalization are available; full D1–D6 execution is unverified. Scorers: VGGT-Omega, DINOv2, Qwen3.5, Qwen3-VL.
Dimensions
- D1 cameraKindAxis
Requested-camera precision and prompt-camera alignment.
- D2 visual integrityKindAxis
Visual integrity of generated frames.
- D3–D4 visibleKindAxis
Spatial and state consistency while content is visible.
- D5–D6 re-observationKindAxis
Conditional on hidden-and-returned evidence only.
- Natural-25KindSuite
25 scene families × four-level events; 100 semantic variants × 5 camera controls = 500 requests.
Data composition
- Size
USTC / X-Humanoid persistent-state bench. Natural-25: 500 camera-control requests. D1–D6 hierarchical chain. Dataset WRBench/wrbench-natural25.
- Sources
WRBench/wrbench-natural25 · WRBench/wrbench-results · WRBench/wrbench-videos · github.com
- Splits
natural25
- Modalities
text · image · video · camera-trajectory
- Notes
Natural-25 request materialization and result normalization are available. Full D1–D6 execution (VGGT-Omega, DINOv2, Qwen3.5, Qwen3-VL) is unverified.
Metrics
Metric
- DirectionHigher is better
d1_cam_precD1-CamPrec: requested-camera trajectory precision when an explicit target trajectory exists.
- DirectionHigher is better
d1_cam_align_common_yawD1-CamAlign (common yaw): prompt-camera intent alignment for prompt/API camera control.
- DirectionHigher is better
d1_cam_align_static_holdD1-CamAlign (static hold): alignment on hold-still camera requests.
- DirectionHigher is better
d2_visual_integrityD2: visual integrity of the generated frames.
- DirectionHigher is better
d3_visible_spatial_consistencyD3: spatial consistency while content is visible.
- DirectionHigher is better
d4_visible_state_consistencyD4: event-state consistency while content is visible.
- DirectionHigher is better
d5_reobservation_spatial_consistencyD5: spatial consistency when hidden content returns into view.
- DirectionHigher is better
d6_reobservation_state_consistencyD6: event-state consistency of the returned target (did the event advance?).
- DirectionHigher is better
wrbench_averageAggregate over the D1-D6 diagnostic dimensions.
PrimaryWRBench diagnostic average
Leaderboard
Official live board, embedded on this page. Not WorldFoundry-run scores. Hugging Face Space (WRBench).
How to run
worldfoundry-eval zoo benchmark-run \
  --benchmark-id wrbench \
  --mode official-validation \
  --official-results-path <official_results.json_or_csv> \
  --generated-artifact-dir <generated_videos> \
  --output-dir tmp/wrbench/official-validation \
  --json
--run-official scores generated videos plus camera sidecars against Natural-25 (--scorer-profile, --sidecar-profile-gate). Rows without re-observation support are excluded from D5/D6, not counted as failures. Env: WORLDFOUNDRY_WRBENCH_RESULTS_PATH, WORLDFOUNDRY_WRBENCH_ROOT. Shared stack: vggt_omega, dinov2, qwen3_5_vl, qwen3_vl.
In-tree pointers: worldfoundry/data/benchmarks/tasks/external/wrbench.yaml, worldfoundry/data/benchmarks/assets/wrbench, worldfoundry/evaluation/tasks/execution/runners/wrbench/runtime/wrbench.
Outputs include scorecard.json (primary wrbench_average, leaderboard key Avg) and generation_requests.jsonl.
Bundled Natural-25 assets
worldfoundry/data/benchmarks/assets/wrbench/natural25/ ships the prompt grid WorldFoundry materializes (Apache-2.0 with the rest of this repository). Hugging Face mirrors: collection, WRBench/wrbench-natural25, WRBench/wrbench-videos, leaderboard.
| File | Role |
|---|---|
scene_events_25x4.csv | 25 scene families × 4 event axes (none / spatial / state / full) |
families.jsonl | Scene-family metadata and prompt variants |
variants.jsonl | Deterministic TI2V variants: 25 families × 4 event tiers × 4 camera gaps. ti2v_prompt is the first-frame-anchored prompt of record |
variants.legacy_pronoun_20260620.jsonl | Frozen provenance snapshot; currently byte-identical to variants.jsonl |
t2v_layout_anchors.jsonl | Text-only layout facts (subject left, interactor right, open surface, background) |
t2v_event_tails.jsonl | Text-only event/action tails keyed by variant_id |
prompt_profiles/t2v_layout_anchor.json | Text-only prompt profile; bans T2I/TI2V style tokens |
camera_scopes/t2v_rotation_stress_30_60.json | T2V-only rotation-stress scope (static, yaw30_LR, yaw30_RL, yaw60_LR, yaw60_RL) |
first_frames/ + first_frames_manifest.json | Released PNG first frames, one per family_id |
You can regenerate first-frame PNGs with wrbench firstframe or substitute your own T2I images. Human annotation verdicts are released separately. Text-only leaderboard entries should materialize t2v_layout_anchor and the rotation-stress scope rather than the main TI2V/TV2V surface.