WorldReasonBench
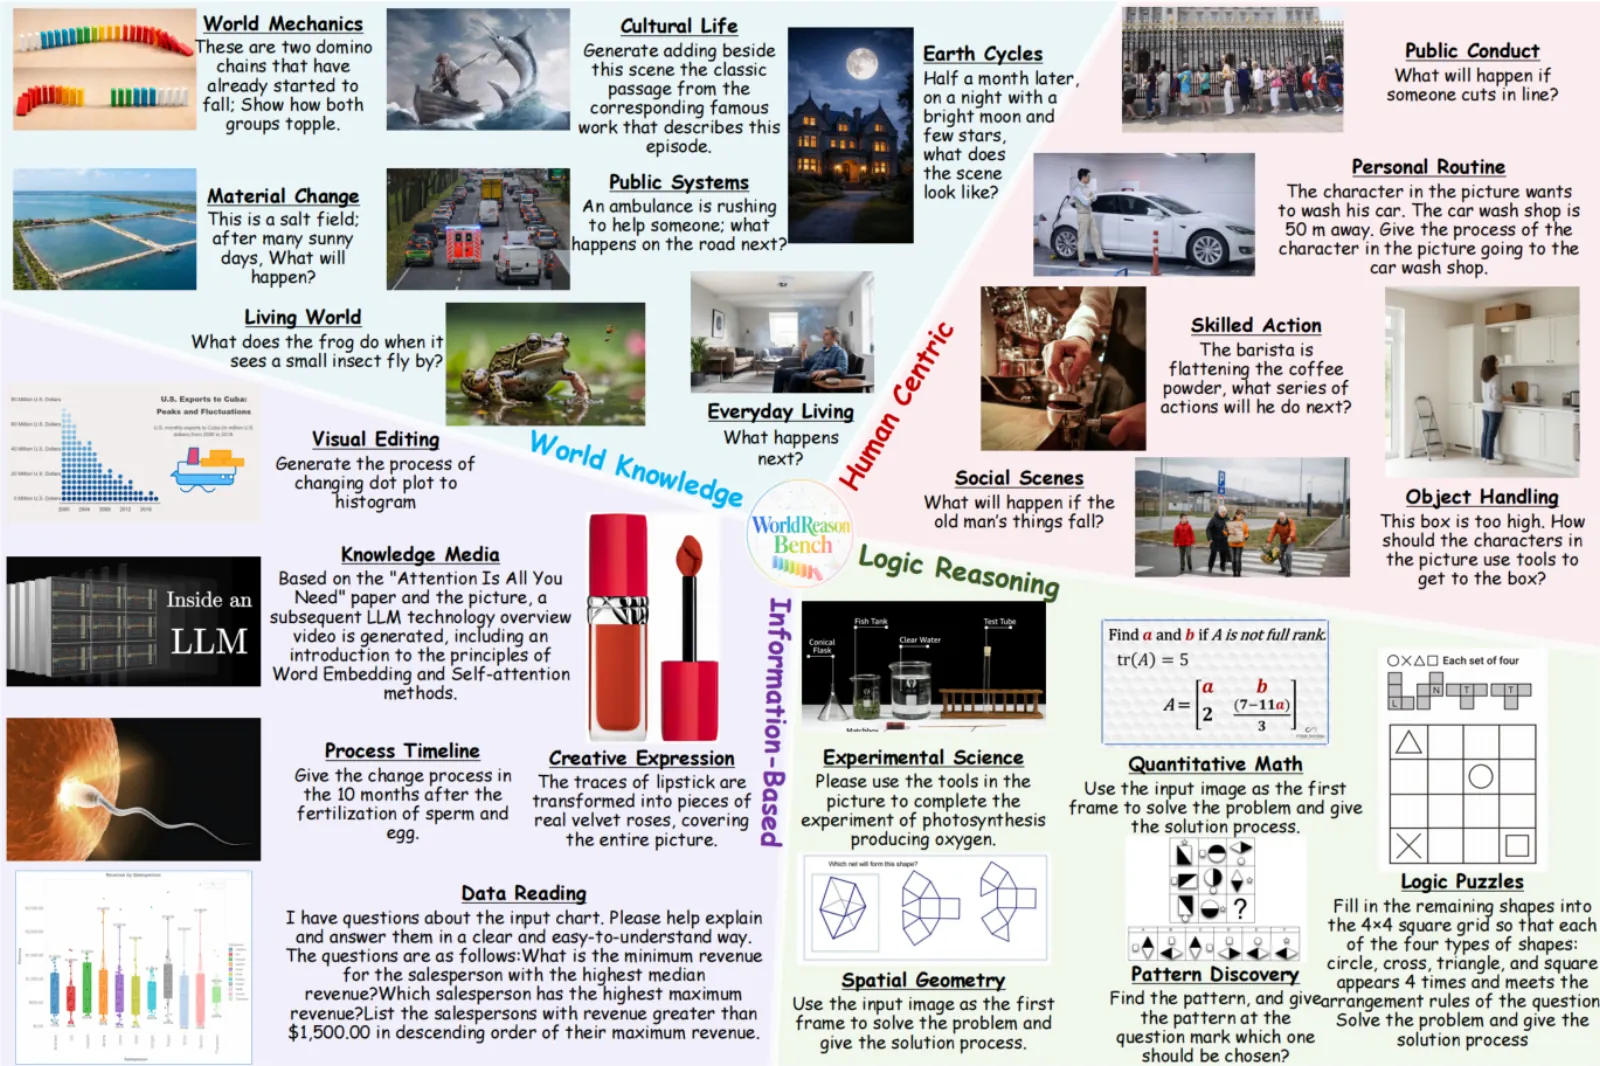
WorldReasonBench (Tsinghua, with NTU and Waterloo) reframes video-generation eval as world-state prediction: given an initial state and an action, can the model generate a future whose evolution stays physically, socially, logically, and informationally consistent? Official size: 436 curated cases with structured QA across four reasoning dimensions / 22 subcategories. Companion WorldRewardBench adds ~6K expert preference pairs.
Two protocols:
- Process-aware Reasoning Verification — structured QA plus reasoning-phase diagnostics. Primary
score_prgeometrically combines QA accuracy with dynamic reasoning.reasoning_gap(static outcome minus dynamic reasoning; lower is better) flags outcome hacking. - Multi-dimensional Quality Assessment — reasoning quality, temporal consistency, visual aesthetics. Reward-model path also reports point-wise / pairwise correlations.
Paper: WorldReasonBench. Project: unix-ai-lab.github.io/WorldReasonBench. Code: UniX-AI-Lab/WorldReasonBench. Upstream README prohibits redistribution, modification, and commercial use without approval despite also referring to MIT.
WorldFoundry hosts the protocol runtime with an OpenAI-compatible multimodal judge. Result normalization / QA component code exists; no complete official judge run is claimed.
Dimensions
- Process-aware Reasoning VerificationKindTrack
Structured QA plus reasoning-phase diagnostics. Primary score_pr. reasoning_gap lower-is-better.
- Multi-dimensional Quality AssessmentKindTrack
Reasoning quality, temporal consistency, visual aesthetics.
- WorldRewardBenchKindSuite
~6K expert preference pairs for point-wise/pair-wise reward-model eval.
Data composition
- Size
Tsinghua world-state prediction bench. 436 cases, 4 reasoning dimensions / 22 subcategories. Restricted: README prohibits redistribution/modification/commercial use without approval.
- Sources
WorldReasonBench · github.com
- Modalities
image · video · text
- License
restricted_noncommercial
- Notes
Result normalization/QA component code exists. No complete official judge run is claimed.
Metrics
Metric
- DirectionHigher is better
score_prGeometric combination of QA accuracy and dynamic reasoning score.
PrimaryProcess-aware Reasoning Score
- DirectionHigher is better
qa_accuracyStructured QA accuracy over ground-truth world-state questions.
- DirectionHigher is better
state_scoreCorrectness of the final predicted world state.
- DirectionHigher is better
process_scoreReasoning-phase diagnostic score over the state-evolution process.
- DirectionHigher is better
fidelity_scoreContent fidelity of the generated evolution.
- DirectionHigher is better
mechanism_scoreCorrectness of the causal mechanism driving the evolution.
- DirectionHigher is better
static_outcome_scoreOutcome score judged from static (final-state) evidence only.
- DirectionHigher is better
dynamic_reasoning_scoreReasoning score judged from the full temporal evolution.
- DirectionLower is better
reasoning_gapStatic outcome score minus dynamic reasoning score; lower values indicate less outcome hacking.
- DirectionHigher is better
pointwise_scorePoint-wise quality score used for reward-model evaluation.
- DirectionHigher is better
reasoning_correctnessMulti-dimensional assessment: reasoning quality.
- DirectionHigher is better
content_fidelityMulti-dimensional assessment: temporal/content consistency.
- DirectionHigher is better
visual_aestheticsMulti-dimensional assessment: visual aesthetics.
- DirectionHigher is better
pointwise_spearmanSpearman correlation of point-wise scores with expert rankings.
- DirectionHigher is better
induced_pairwise_accuracyPairwise preference accuracy induced from point-wise scores.
- DirectionHigher is better
pairwise_accuracy_with_tiesPairwise preference accuracy counting tied pairs.
- DirectionHigher is better
pairwise_accuracy_without_tiesPairwise preference accuracy excluding tied pairs.
Leaderboard
Results from the paper (not a live board; not WorldFoundry-run scores). WorldReasonBench: Human-Aligned Stress Testing of Video Generators as Future World-State Predictors (2026).
| Model | Score PR (%) |
|---|---|
| Seedance2.0 | 39.8 |
| Veo3.1-Fast | 35.3 |
| Sora2-8s | 34.3 |
| Kling | 32.7 |
| Wan2.6 | 32.4 |
| Sora2-12s | 32.4 |
| HunyuanVideo-1.5 | 17.9 |
| Wan2.2-14B | 17.5 |
How to run
worldfoundry-eval zoo benchmark-run \
  --benchmark-id worldreasonbench \
  --mode official-validation \
  --official-results-path <official_results_dir> \
  --output-dir tmp/worldreasonbench/official-validation \
  --json
--protocol selects the protocol. QA / pair files: --qa-json, --pairs-json. Judge: --base-url, --api-key, --model, --judge-model. Default import: WORLDFOUNDRY_WORLDREASONBENCH_RESULTS_PATH.
In-tree pointers: worldfoundry/data/benchmarks/tasks/external/worldreasonbench.yaml, worldfoundry/evaluation/tasks/execution/runners/worldreasonbench.
Outputs include scorecard.json (primary score_pr) and protocol_results.json.