
BEHAVIOR-1K
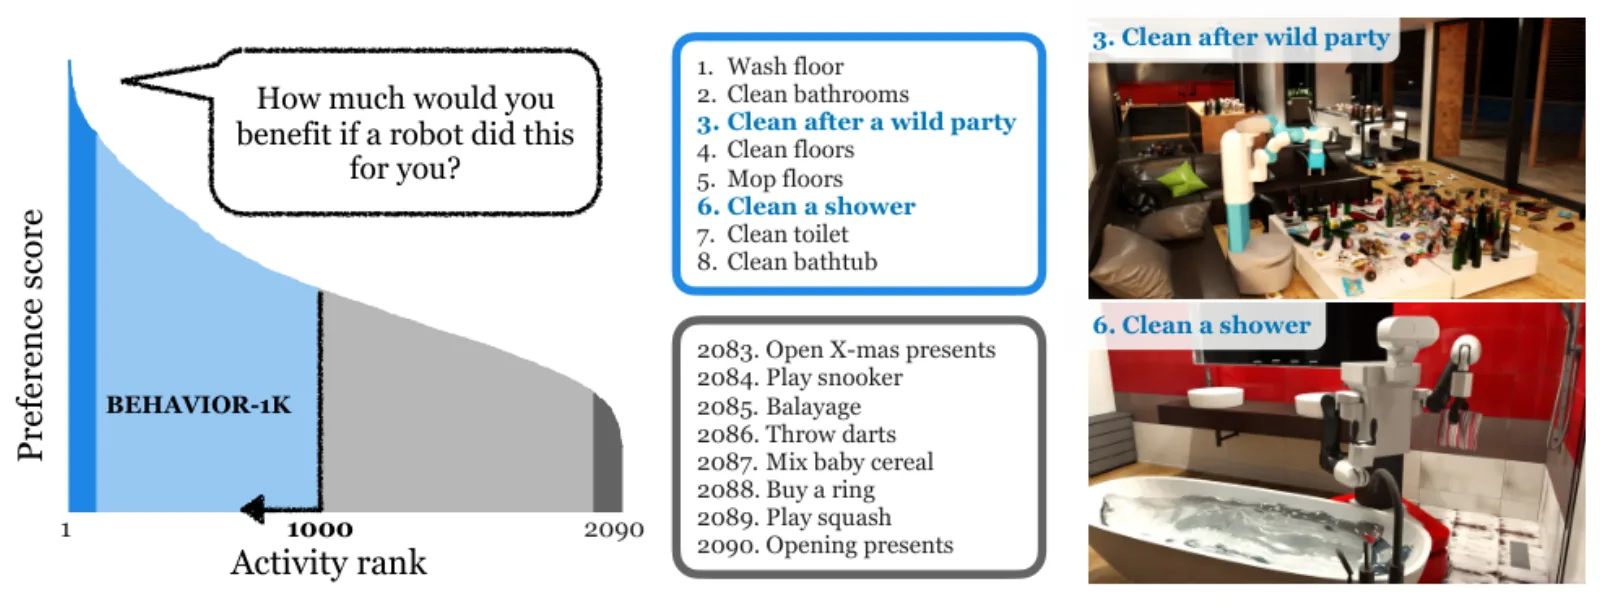
BEHAVIOR-1K is Stanford Vision & Learning Lab's human-centered embodied benchmark: 1,000 everyday activities (cleaning, cooking, tidying) chosen from human time-use surveys, written in the BDDL predicate language, and simulated in OmniGibson with fluids, object states, and household physics. Success is logical goal satisfaction, not a pixel score. Subgoal satisfaction is the partial-credit signal.
Paper: BEHAVIOR-1K. Project: behavior.stanford.edu. Simulator / code: StanfordVL/OmniGibson (upstream_terms in this catalog).
WorldFoundry imports official OmniGibson result exports. It does not vendor OmniGibson, the 1,000 activity definitions, or policy checkpoints. Those follow Stanford's documentation.
Dimensions
- 1,000 household activitiesKindSuite
Activities sampled from human time-use surveys (cleaning, cooking, tidying) and specified in BDDL.
- BDDL subgoalsKindAxis
Success is logical goal satisfaction; subgoal rate is partial credit.
Data composition
- Size
Stanford BEHAVIOR-1K: 1,000 everyday activities in OmniGibson with realistic physics, fluids, and object states. Goals are logical predicates in BDDL, not a single pixel metric.
- Sources
github.com
- Modalities
language · vision · action · state
- License
upstream_terms
- Notes
WorldFoundry imports official OmniGibson result exports; it does not run OmniGibson in tree.
Metrics
Metric
- DirectionHigher is better
success_ratePrimary episode success rate over evaluated rollouts.
PrimarySuccess Rate
- DirectionHigher is better
task_successPer-task success aggregate.
- DirectionHigher is better
episode_successPer-episode success indicator aggregate.
- DirectionHigher is better
subgoal_successBDDL subgoal satisfaction rate (partial credit).
Leaderboard
Results from the paper (not a live board; not WorldFoundry-run scores). Author RL baselines on one of the paper’s three reported activities. BEHAVIOR-1K: A Human-Centered, Embodied AI Benchmark with 1,000 Everyday Activities and Realistic Simulation (2024).
| Model | StoreDecoration success |
|---|---|
| RL-Prim.Hist. | 0.55 |
| RL-Prim. | 0.48 |
| RL-VMC | 0.0 |
How to run
worldfoundry-eval zoo benchmark-run \
  --benchmark-id behavior1k \
  --mode official-validation \
  --official-results-path <official_results.json> \
  --output-dir tmp/behavior1k/official-validation \
  --json
Optional WORLDFOUNDRY_BEHAVIOR1K_ROOT points at a local OmniGibson / activity root. Default import path: WORLDFOUNDRY_BEHAVIOR1K_RESULTS_PATH. Manifest: worldfoundry/data/benchmarks/tasks/external/behavior1k.yaml. Outputs: scorecard.json (primary success_rate; also subgoal_success), raw_results.jsonl, and evaluation/summary.json.