EWMBench
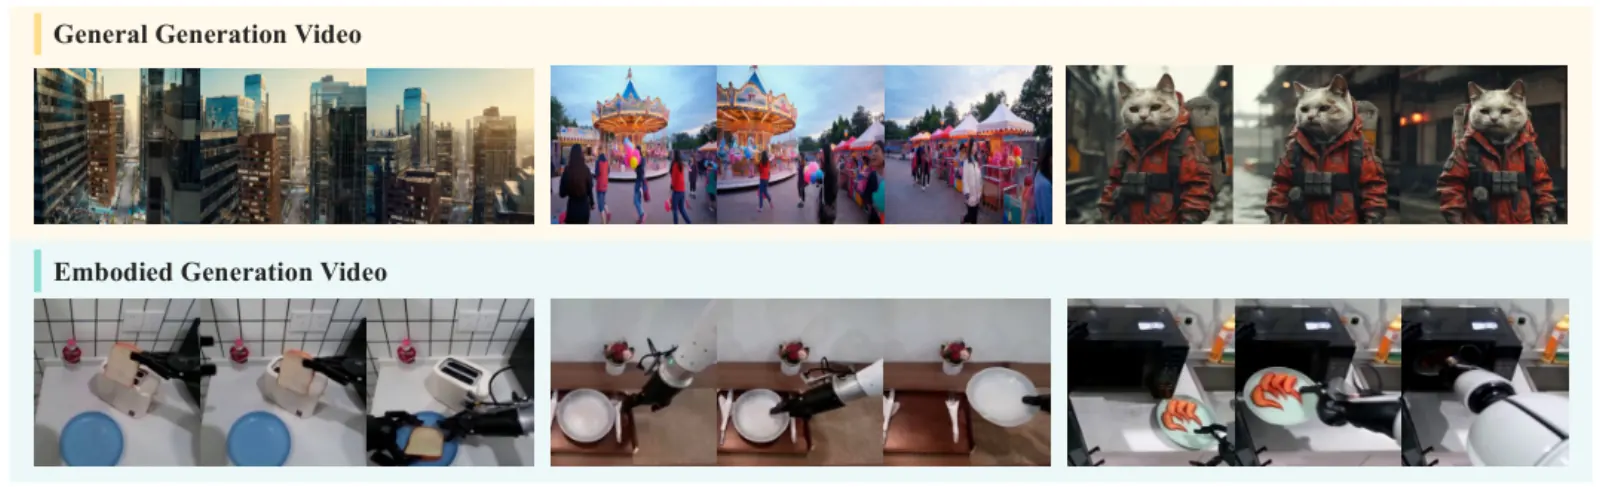
EWMBench (AgiBot / AgibotTech) evaluates action-conditioned robot-manipulation videos from the AgiBot-World ecosystem. It is a world-model quality bench, not a tabletop success-rate suite. Four families roll into ewmbench_average:
- Scene consistency — does the workspace stay stable?
- Motion correctness — does the arm / object trajectory match the task?
- Semantic alignment — does the clip match the language instruction?
- Diversity — diversity of generated rollouts.
Paper: EWMBench. Data / project: agibot-world/EWMBench (CC-BY-NC-SA-4.0). Code: AgibotTech/EWMBench.
WorldFoundry vendors runtime assets and normalizes official result files through benchmark-run. --run-official can dispatch the upstream evaluate.py scorer when those dependencies are staged. Detector / VLM judge assets stay upstream.
Dimensions
- Scene consistencyKindAxis
Does the workspace stay stable across the generated manipulation video?
- Motion correctnessKindAxis
Does the arm / object trajectory match the requested embodied task?
- Semantic alignmentKindAxis
Does the video match the language instruction?
- DiversityKindAxis
Diversity of generated embodied-world-model rollouts.
Data composition
- Size
AgiBot EWMBench: action-conditioned robot-manipulation videos from the AgiBot-World ecosystem, scored for scene, motion, semantics, and diversity.
- Sources
agibot-world/EWMBench · github.com
- Modalities
text · action · video · frames
- License
cc-by-nc-sa-4.0
- Notes
WorldFoundry normalizes official result files. Full official scoring still needs upstream detector / VLM assets.
Metrics
Metric
- DirectionHigher is better
scene_consistencyWorkspace stability over the generated clip.
- DirectionHigher is better
motion_correctnessWhether the arm / object motion matches the task.
- DirectionHigher is better
semantic_alignmentLanguage-instruction agreement of the generated video.
- DirectionHigher is better
diversityDiversity of generated embodied rollouts.
- DirectionHigher is better
ewmbench_averageMean of scene, motion, semantic, and diversity scores when all four are present.
PrimaryEWMBench average
Leaderboard
Results from the paper (not a live board; not WorldFoundry-run scores). Paper overall score (scene + motion + semantics). EWMBench: Evaluating Scene, Motion, and Semantic Quality in Embodied World Models (2025).
| Model | Overall |
|---|---|
| EnerVerse_FTdomain-finetuned | 4.7010 |
| LTX_FTdomain-finetuned | 4.5493 |
| Kling | 3.8698 |
| Hailuo | 3.4125 |
| COSMOS | 3.2872 |
| OpenSora | 3.1392 |
| LTX | 2.9676 |
How to run
worldfoundry-eval zoo benchmark-run \
  --benchmark-id ewmbench \
  --mode official-validation \
  --official-results-path <official_results.json> \
  --generated-artifact-dir <generated_videos> \
  --output-dir tmp/ewmbench/official-validation \
  --json
--task-manifest and --config-path bind the task set and scorer config; --limit bounds wiring runs. Default import path: WORLDFOUNDRY_EWMBENCH_RESULTS_PATH. Optional root: WORLDFOUNDRY_EWMBENCH_ROOT. Shared asset: ewmbench_dataset_assets.
In-tree pointers:
worldfoundry/data/benchmarks/tasks/external/ewmbench.yaml
worldfoundry/evaluation/tasks/execution/runners/ewmbench/runtime/ewmbench
Outputs include scorecard.json (primary ewmbench_average), benchmark_contract.json, and raw_metric_table.jsonl.