RLBench
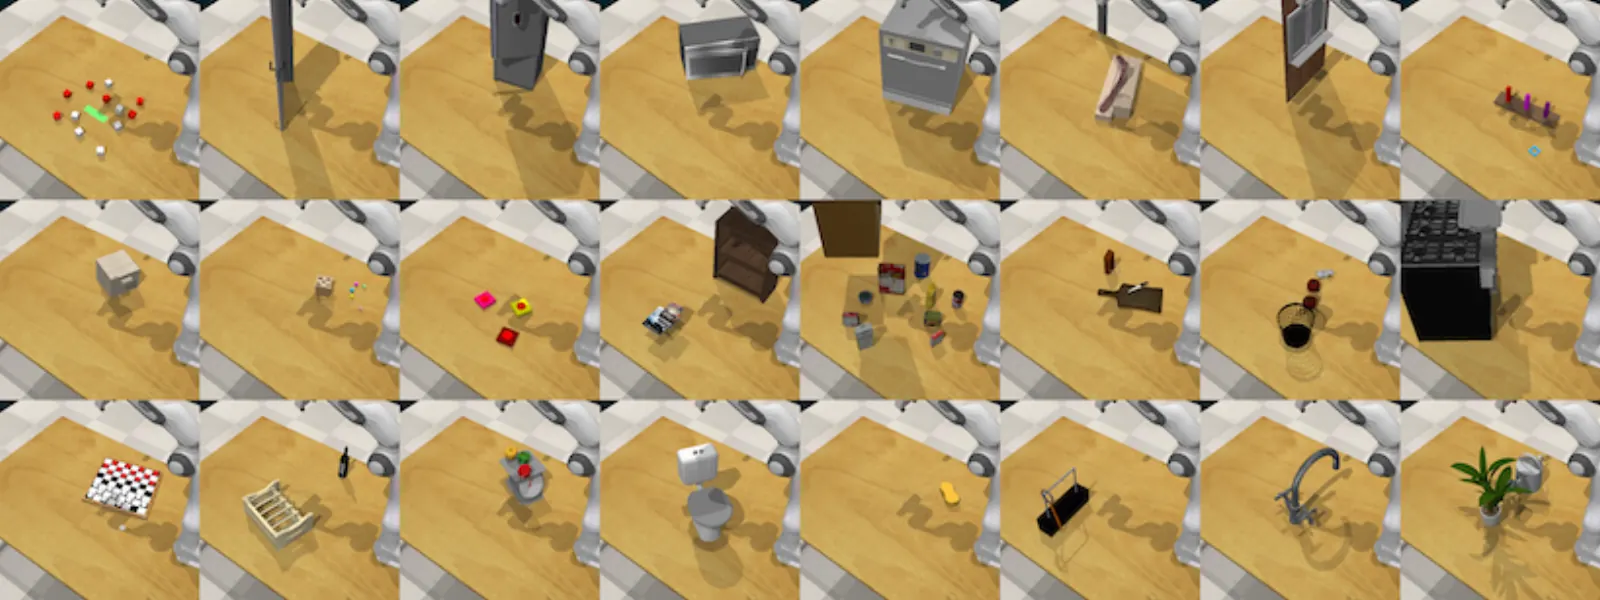
RLBench (IEEE RA-L / ICRA 2020) is Imperial College London's Dyson Robotics Lab benchmark: 100 unique, hand-designed manipulation tasks for a Franka Panda in CoppeliaSim (via PyRep). Each task has procedural variations (object poses, goals). A motion planner can emit unlimited demonstrations, so the same suite supports imitation learning, RL, and a few-shot protocol. Observations are multi-camera vision plus state / language.
Paper: RLBench: The Robot Learning Benchmark & Learning Environment. Project: sites.google.com/view/rlbench. Code: stepjam/RLBench. GitHub license metadata in this catalog is other:noassertion_github_api — read the upstream terms before reuse.
WorldFoundry is official-results only. You run CoppeliaSim / PyRep / the official task assets upstream, then official-validation normalizes JSON/CSV. No in-tree simulator. Declare the task list and the protocol (few-shot vs IL vs RL) with the export.
Dimensions
- 100 hand-designed tasksKindSuite
Franka Panda tabletop / near-table skills in CoppeliaSim. Compare only the same task list.
- Procedural variationsKindSplit
Each task samples object poses and goal variants; motion-planner demos are infinite.
- Few-shot protocolKindTrack
Official few-shot setting: limited demonstrations, then evaluate on held-out variations.
- Imitation / RLKindTrack
Same tasks support imitation-learning and RL report cards. Do not mix them.
Data composition
- Size
100 unique, hand-designed vision-guided manipulation tasks on a Franka Panda in CoppeliaSim (via PyRep). Infinite motion-planner demonstrations. GitHub API license is NOASSERTION — read upstream terms.
- Sources
github.com
- Splits
few_shot
- Modalities
language · vision · action · state
- License
other:noassertion_github_api
- Notes
WorldFoundry normalizes policy rollout exports. CoppeliaSim, PyRep, and task assets stay upstream.
Metrics
Metric
- DirectionHigher is better
success_ratePrimary episode success on the declared task list and protocol (few-shot / IL / RL).
PrimarySuccess Rate
- DirectionHigher is better
task_successPer-task success among the 100 hand-designed tasks.
- DirectionHigher is better
episode_successPer-episode success indicator when the export lists individual rollouts.
- DirectionHigher is better
rewardMean episode return if the official dump includes dense reward.
- DirectionHigher is better
normalized_returnReturn scaled to a declared range when the export provides it.
Leaderboard
No live RLBench board. The 2019 paper introduces the 100-task environment and demonstration API; arXiv HTML/ar5iv contain no numeric policy ranking table. RLBench: The Robot Learning Benchmark & Learning Environment (2019).
How to run
worldfoundry-eval zoo benchmark-run \
  --benchmark-id rlbench \
  --mode official-validation \
  --official-results-path <official_results.json> \
  --output-dir tmp/rlbench/official-validation \
  --json
Default import path when you omit --official-results-path is WORLDFOUNDRY_RLBENCH_RESULTS_PATH. Manifest: worldfoundry/data/benchmarks/tasks/external/rlbench.yaml. Outputs: scorecard.json (primary success_rate) and raw_results.jsonl.