T2V-CompBench
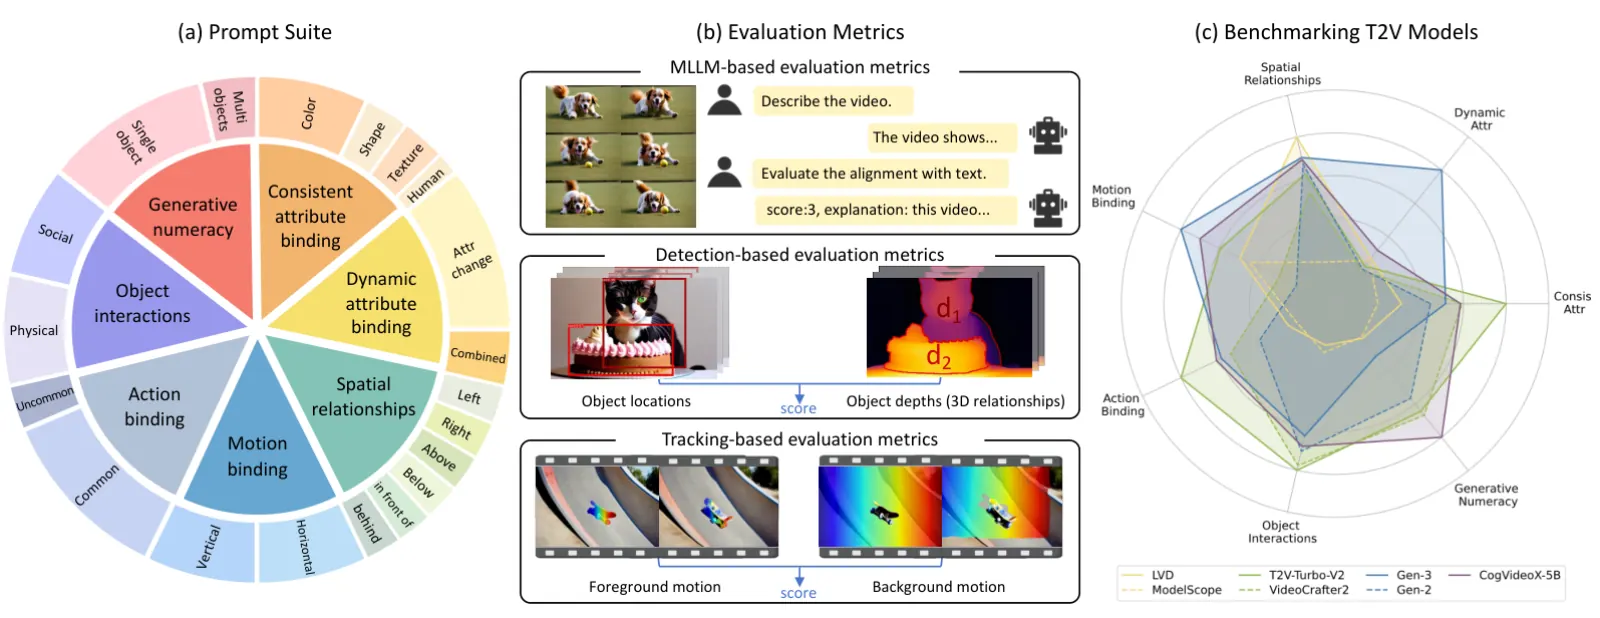
T2V-CompBench (HKU, with CUHK and Huawei Noah's Ark Lab) asks whether a text-to-video model binds the right attributes, actions, and motions to the right objects. It is a composition test, not a single aesthetic score. The official suite has 1,400 prompts (200 × 7):
- Consistent / dynamic attribute binding — static properties, then temporal changes, on the correct object.
- Spatial relationships — 2D / 3D layout (detection + depth / SAM).
- Motion binding — foreground vs background motion (DOT tracking).
- Action binding and object interactions — MLLM (LLaVA-style) judges.
- Generative numeracy — object counts via GroundingDINO. This is the bounded official component WorldFoundry has executed on a real MP4.
Paper: T2V-CompBench. Project: t2v-compbench-2025.github.io. Code: KaiyueSun98/T2V-CompBench. Reference videos: Kaiyue/T2V-CompBench-Videos (25,200 rows).
WorldFoundry vendors the official runtime and a strict manifest bridge that stages generated videos into category/NNNN.mp4. Import official CSV / JSON, or run a category when its metric assets are staged. t2v_compbench_average is emitted only when all seven category scores exist.
Dimensions
- Consistent attribute bindingKindCategory
Bind static attributes (color, material) to the correct objects across the clip.
- Dynamic attribute bindingKindCategory
Realize temporal attribute changes (something becoming red, growing, melting) on the right object.
- Spatial relationshipsKindCategory
2D/3D spatial layout scored with detection plus depth/SAM.
- Motion bindingKindCategory
Foreground vs background motion binding scored with DOT tracking.
- Action bindingKindCategory
Bind the requested action to the correct actor, judged by an MLLM.
- Object interactionsKindCategory
Interaction consistency between objects, judged by an MLLM.
- Generative numeracyKindCategory
Object-count fidelity scored with GroundingDINO detection. Bounded official component verified in tree.
Data composition
- Size
1,400 compositional T2V prompts: 200 per category across seven composition axes. Hugging Face also hosts 25,200 official reference videos.
- Sources
Kaiyue/T2V-CompBench-Videos · github.com
- Modalities
text · video
- License
unknown_pending_review
- Notes
WorldFoundry vendors the official runtime. Full-suite average is emitted only when all seven category scores exist.
Metrics
Metric
- DirectionHigher is better
consistent_attribute_bindingT2V-CompBench MLLM score for binding static attributes to the correct objects.
- DirectionHigher is better
dynamic_attribute_bindingT2V-CompBench MLLM score for temporal attribute changes and bindings.
- DirectionHigher is better
spatial_relationshipsT2V-CompBench detection/depth score for 2D and 3D spatial relationships.
- DirectionHigher is better
motion_bindingT2V-CompBench tracking score for foreground/background motion binding.
- DirectionHigher is better
action_bindingT2V-CompBench MLLM score for action-object binding.
- DirectionHigher is better
object_interactionsT2V-CompBench MLLM score for interaction consistency between objects.
- DirectionHigher is better
generative_numeracyT2V-CompBench detection score for generated object counts.
- DirectionHigher is better
t2v_compbench_averageMean emitted only when all seven official T2V-CompBench category scores are available.
PrimaryT2V-CompBench Average
Leaderboard
Official live board, embedded on this page. Not WorldFoundry-run scores. Hugging Face Space (Kaiyue).
How to run
Import official category scores:
worldfoundry-eval zoo benchmark-run \
  --benchmark-id t2v-compbench \
  --mode official-validation \
  --official-results-path <official_results.json> \
  --generated-artifact-dir <generated_videos> \
  --output-dir tmp/t2v-compbench/official-validation \
  --json
Recompute a category from staged videos (numeracy needs GroundingDINO + a BERT-compatible encoder):
${WORLDFOUNDRY_UNIFIED_PYTHON} \
  worldfoundry/evaluation/tasks/execution/runners/t2v_compbench/run_t2v_compbench_official_runner.py \
  --generated-video-dir <generated_videos_with_t2v_compbench_generation_manifest.jsonl> \
  --category generative_numeracy \
  --output-dir tmp/t2v-compbench/numeracy \
  --json
--preflight checks assets before a run. MLLM categories need WORLDFOUNDRY_T2V_COMPBENCH_LLAVA_MODEL_PATH; motion binding needs DOT; spatial categories need Depth-Anything / SAM (WORLDFOUNDRY_T2V_COMPBENCH_SAM_CKPT). Shared stack: grounded_depth_segmentation_stack. Default import path: WORLDFOUNDRY_T2V_COMPBENCH_RESULTS_PATH. Optional runtime root: WORLDFOUNDRY_T2V_COMPBENCH_ROOT.
In-tree pointers:
worldfoundry/data/benchmarks/tasks/external/t2v-compbench.yaml
worldfoundry/evaluation/tasks/execution/runners/t2v_compbench/runtime/t2v_compbench
Outputs include scorecard.json (primary t2v_compbench_average when complete), raw_metric_table.jsonl, and per-sample rows when the source exposes them.