DUSt3R
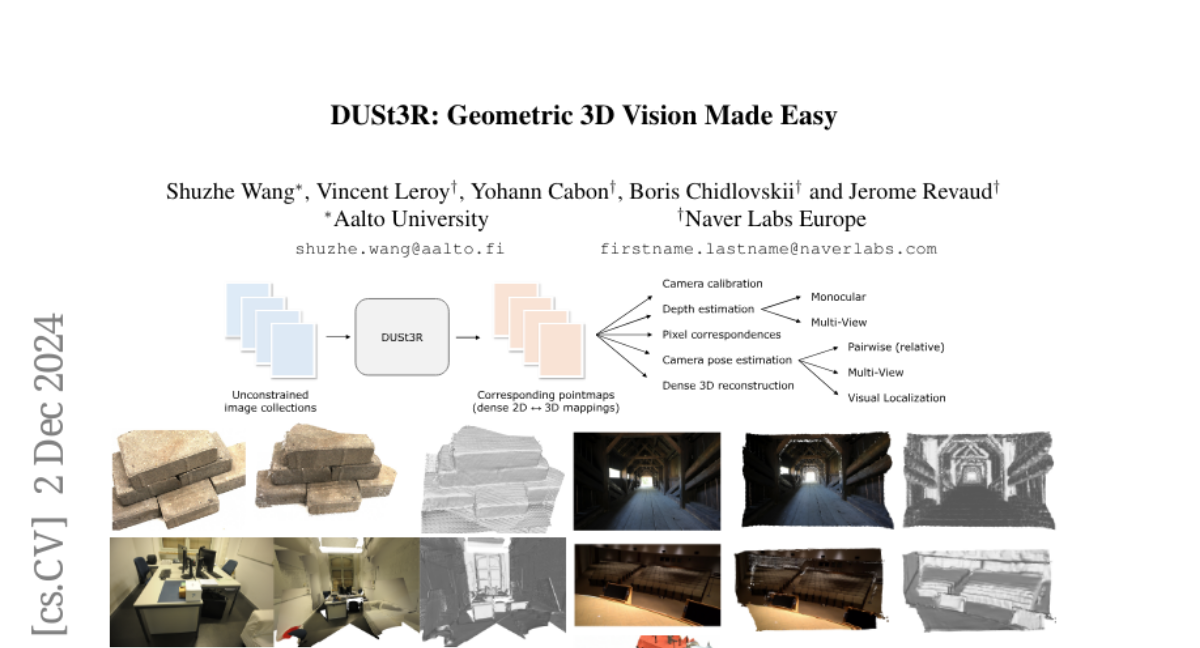
NAVER Labs two-view pointmaps, no calibration. Runner verified on the bundled multi-view case. CC-BY-NC-SA-4.0. Writes dust3r_point_cloud.ply.
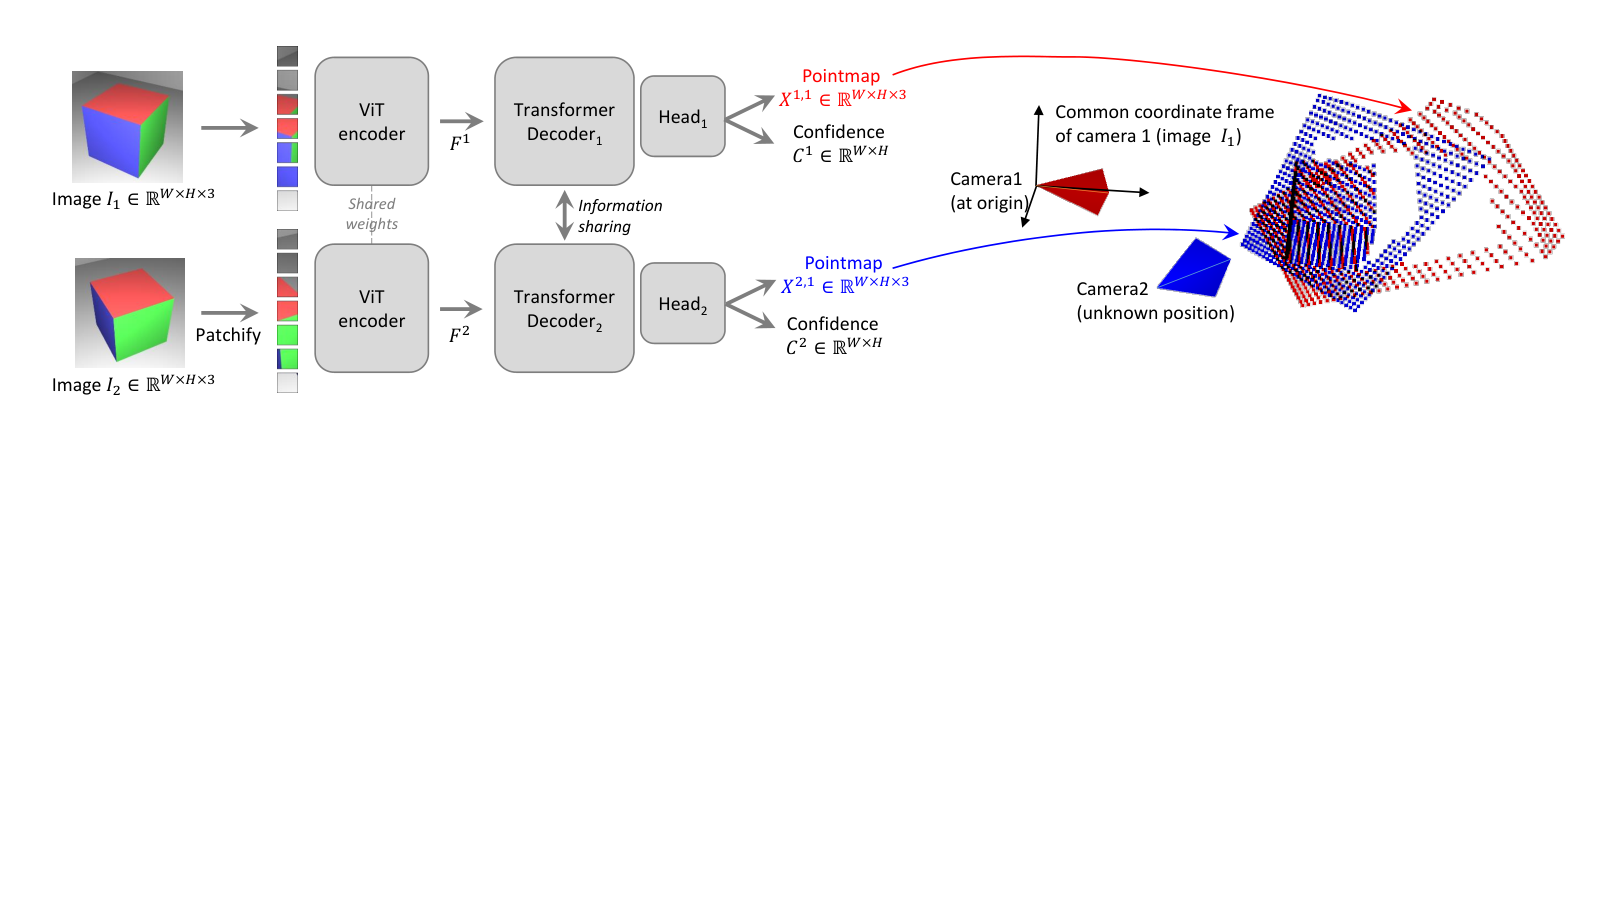
DUSt3R made unconstrained two-view 3D easy: two images, no calibration, no poses — it regresses aligned pointmaps. WorldFoundry vendors it under worldfoundry/base_models/three_dimensions/general_3d/dust3r and exposes DUSt3RPipeline on the shared geometry-prior contract. Aliases naver-dust3r and geometric-3d-vision-made-easy resolve here.
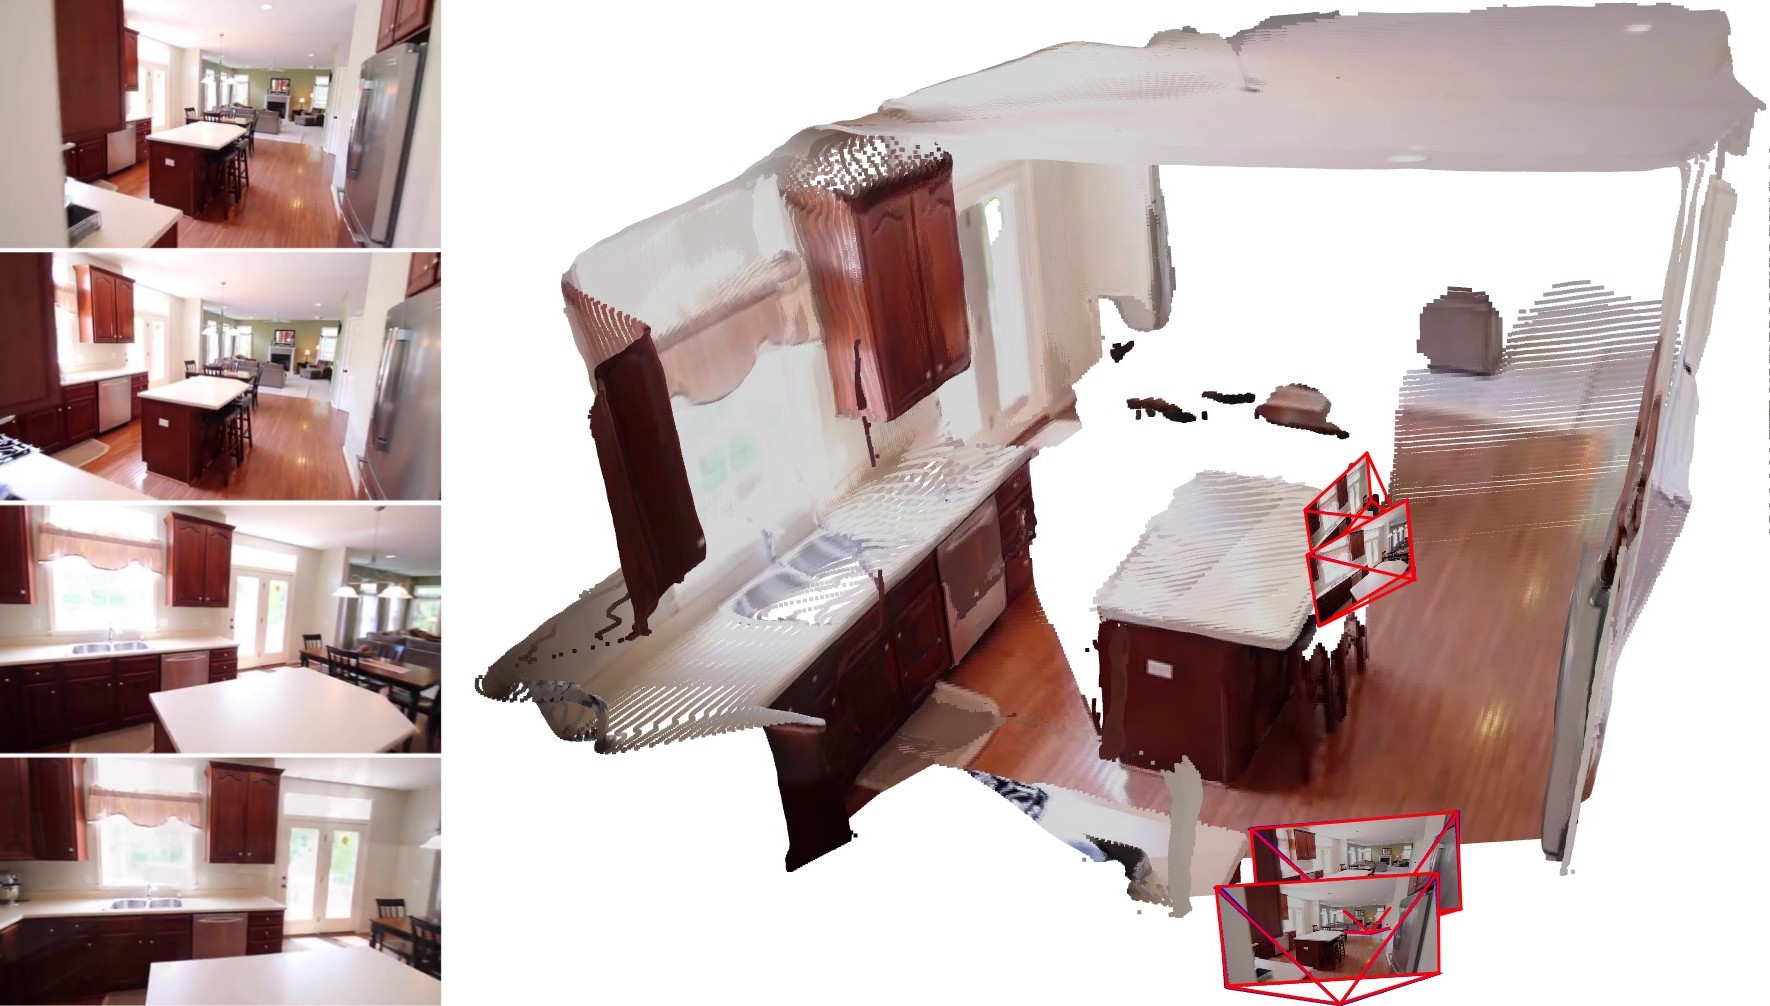
Paper: DUSt3R: Geometric 3D Vision Made Easy (arXiv 2312.14132). Project: dust3r.europe.naverlabs.com. Publisher: NAVER Labs Europe. License: CC-BY-NC-SA-4.0 (non-commercial downstream).
Runner is verified: checkpoint-backed Studio inference produced a finite point cloud from the bundled multi-view test case (inference_evidence.yaml).
Build your run
DUSt3RPipelineworldfoundry.pipelines.geometry_priors.pipeline_geometry_priorsdefaultworldfoundry.pipelineworldfoundry-eval run \
dust3r \
--pipeline.task-profile default \
--jsonWhat it is for
Launch worldfoundry-eval run dust3r with the feed-forward multi-view reconstruction profile. Required: image. Optional: prompt, video. actions: multi_view_reconstruction. Artifact: dust3r_point_cloud.ply. Large scenes still need global alignment, which gets expensive with many views. Streaming metric state is CUT3R, not this pairwise card.
Runtime contract
DUSt3RPipeline on the shared geometry-prior contract (dust3r-base-model). Required: image (an uncalibrated pair or multi-view set). Optional catalog fields: prompt, video. actions: multi_view_reconstruction. Artifact: dust3r_point_cloud.ply.
| Knob | Recorded |
|---|---|
| Checkpoint | naver/DUSt3R_ViTLarge_BaseDecoder_512_dpt → $WORLDFOUNDRY_CKPT_DIR/DUSt3R_ViTLarge_BaseDecoder_512_dpt.pth |
| Encoder | ViT-Large + Base decoder, 512 DPT |
| Pair output | Per-pixel pointmaps in a shared frame (camera-1 coordinates) |
| Many views | Global alignment after pairwise inference |
| Runner | verified — finite point cloud from the bundled multi-view Studio case (inference_evidence.yaml) |
Environment: worldfoundry-unified-cu128 (Python 3.11, CUDA 12.8). Catalog VRAM is unset. License: CC-BY-NC-SA-4.0.
Running in WorldFoundry
Stage the NAVER 512_dpt file first. Missing weights fail at load — the runtime does not download them. Respect NC-SA terms downstream.