Apple-PI
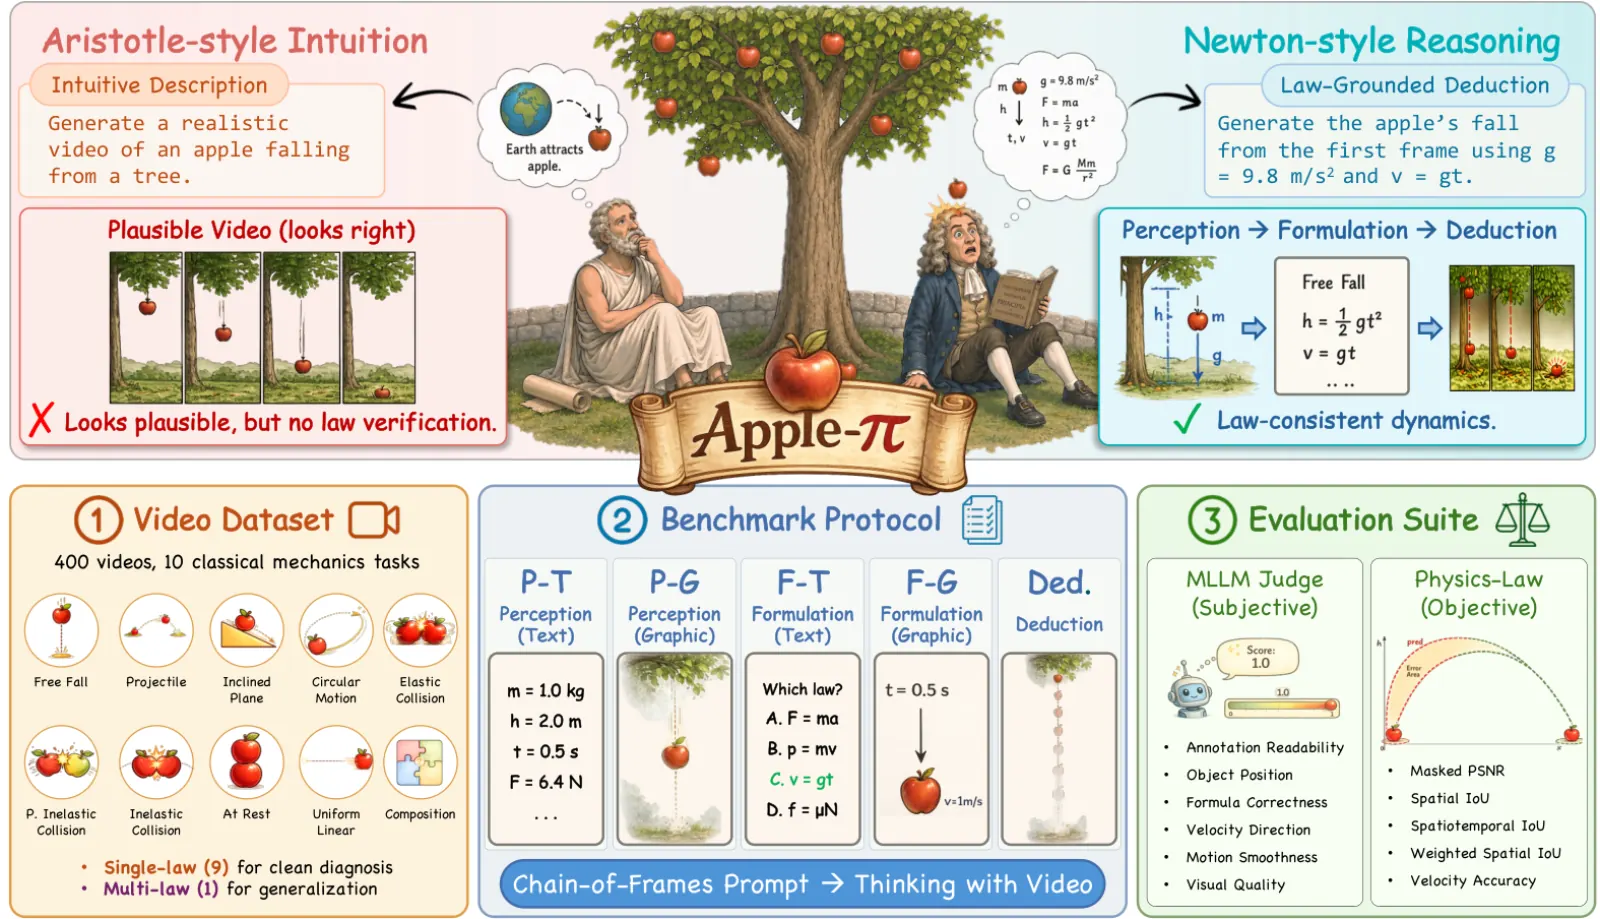
Apple-π (NTU S-Lab) asks whether a video model reasons with physical law, not whether the pixels look plausible. Orchard is 400 classical-mechanics videos over 10 canonical tasks (nine single-law tasks plus one multi-law composition), from simulation, lab recordings, and internet footage. The protocol is chain-of-frames on an infographic-annotated first frame: Perception (read quantities / ground objects), Formulation (pick the law / predict a target-time state), Deduction (full law-consistent trajectory). Perception and Formulation each split into text and graphic, so there are five subtracks. Official scoring is hybrid: Gemini judging plus SAM3 / MoGe / trajectory-overlap / velocity-error. Predictions are three independent rollouts per case and subtrack; frame 0 is the condition.
Paper: Apple-π. Project: 21yrm.github.io/Apple-PI-homepage. Code: 21yrm/Apple-PI (Apache-2.0). Formats: GT_FORMAT.md, PREDICTION_FORMAT.md.
WorldFoundry evaluates in tree (run_apple_pi_official_runner.py): it reads upstream-layout GT and prediction directories. It does not run video-model inference. You can also import a finished Apple-PI result JSON. apple_pi_average is a WorldFoundry mean of available subtracks, not an official composite.
Dimensions
- Perception (text)KindTrack
Read physical quantities from the infographic-annotated first frame as text.
- Perception (graphic)KindTrack
Ground objects on the final frame without text labels.
- Formulation (text)KindTrack
Select the governing law and write the formula.
- Formulation (graphic)KindTrack
Predict the state at a target time (velocity arrows and labels).
- DeductionKindTrack
Generate the full law-consistent trajectory. Official primary subtrack.
Data composition
- Size
Orchard: 400 classical-mechanics videos (10 canonical tasks; 9 single-law plus one multi-law composition). Sources are simulated, lab-recorded, and internet footage. Protocol asks for three independent rollouts per case and subtrack; frame 0 is the conditioning frame. The documented Hugging Face GT id is yaorunmao/Apple-PI-GT — not treated as public in this workspace.
- Sources
yaorunmao/Apple-PI-GT · github.com
- Modalities
image · video · text
- License
Apache-2.0
- Notes
Source repo is Apache-2.0. GT availability follows the upstream release; WorldFoundry does not vendor Orchard media or Gemini credentials.
Metrics
Metric
- DirectionHigher is better
perception_textFinal-frame text annotation artifact score.
- DirectionHigher is better
perception_graphicFinal-frame object-only grounding artifact score.
- DirectionHigher is better
formulation_textGoverning-law and formula answer score.
- DirectionHigher is better
formulation_graphicTarget-time state, velocity-arrow, and label score.
- DirectionHigher is better
deductionFull-dynamics trajectory score combining Gemini subjective judging and physics-grounded objective metrics (SAM3, MoGe, trajectory overlap, velocity error).
PrimaryDeduction
- DirectionHigher is better
apple_pi_averageWorldFoundry arithmetic mean of available subtrack means. Not an official composite published by Apple-π.
Leaderboard
Results from the paper (not a live board; not WorldFoundry-run scores). Main paper table, including unified image/video models. Apple-π: Benchmarking Thinking with Video Towards Law-Grounded Physical Intelligence (2026).
| Model | Average track-wise score |
|---|---|
| GPT Image 2unified | 0.704 |
| Nano Banana 2unified | 0.699 |
| Seedance 2.0 | 0.473 |
| VBVR-Wan2.2 | 0.373 |
| SenseNova-U1-8B-MoTunified | 0.362 |
| Veo 3.1 | 0.313 |
| Wan2.2 | 0.267 |
| HunyuanVideo-1.5 | 0.177 |
How to run
Score the deduction subtrack against staged GT (Gemini key for real judging; SAM3 / MoGe-2 ride existing WorldFoundry capability paths):
${WORLDFOUNDRY_UNIFIED_PYTHON} \
  worldfoundry/evaluation/tasks/execution/runners/apple_pi/run_apple_pi_official_runner.py \
  --run-official \
  --gt-dir "${WORLDFOUNDRY_APPLE_PI_GT_DIR}" \
  --pred-dir "${WORLDFOUNDRY_APPLE_PI_PREDICTION_DIR}" \
  --subtrack deduction \
  --output-dir tmp/apple_pi/deduction \
  --json
Import an existing result file:
worldfoundry-eval zoo benchmark-run \
  --benchmark-id apple-pi \
  --mode official-validation \
  --official-results-path <apple_pi_results.json> \
  --output-dir tmp/apple-pi/official-validation \
  --json
--no-foundation-models and --judge-backend mock are wiring only. Env: WORLDFOUNDRY_APPLE_PI_GT_DIR, WORLDFOUNDRY_APPLE_PI_PREDICTION_DIR, WORLDFOUNDRY_APPLE_PI_RESULTS_PATH, WORLDFOUNDRY_APPLE_PI_JUDGE_BACKEND, WORLDFOUNDRY_APPLE_PI_SAM3_CHECKPOINT, WORLDFOUNDRY_APPLE_PI_MOGE_CHECKPOINT. Manifest: worldfoundry/data/benchmarks/tasks/external/apple-pi.yaml. Outputs: scorecard.json (primary deduction), raw_metric_table.jsonl, per_sample_scores.jsonl, benchmark_contract.json.