LIBERO
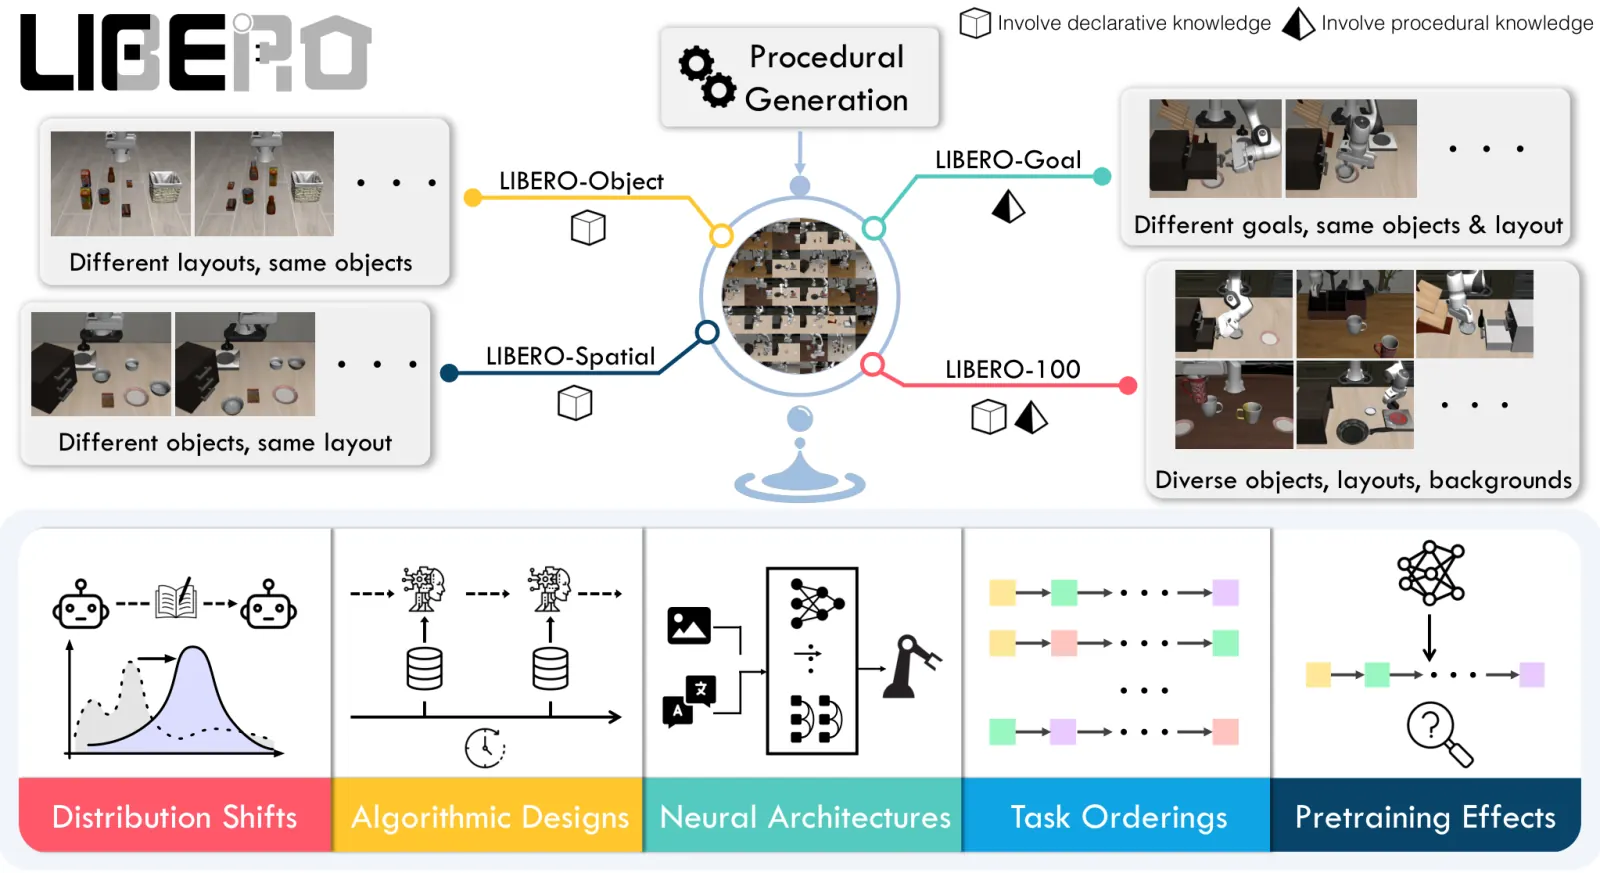
LIBERO (NeurIPS 2023 Datasets & Benchmarks) is the University of Texas at Austin's lifelong manipulation benchmark, with Tsinghua and Sony AI. A Franka on a robosuite / MuJoCo table must transfer declarative and procedural knowledge across tasks. The four official suites isolate what transfers:
- LIBERO-Spatial — same objects, different spatial relations / layouts.
- LIBERO-Object — same skills, different object identities.
- LIBERO-Goal — same scene, different goal language.
- LIBERO-100 — LIBERO-10 short plus LIBERO-90 longer-horizon mix.
It has become the default VLA report card. The paper is LIBERO: Benchmarking Knowledge Transfer for Lifelong Robot Learning. Project: libero-project.github.io. Code: Lifelong-Robot-Learning/LIBERO (MIT).
WorldFoundry supports two paths. Official eval_result trees (or structured exports) go through worldfoundry.evaluation.tasks.embodied.normalizer. Closed-loop execution is wired via worldfoundry-eval embodied run and needs the upstream simulator, suite assets, and the policy the official script expects. Dataset snapshots yifengzhu-hf/LIBERO-datasets and lerobot/libero are tracked as staged assets. Models such as Being-H0.5 expose a LIBERO specialist checkpoint; that is a model-card fact, not a hub leaderboard row.
Dimensions
- LIBERO-SpatialKindSuite
Spatial-relation transfer across tabletop layouts.
- LIBERO-ObjectKindSuite
Object-identity transfer across manipulation tasks.
- LIBERO-GoalKindSuite
Goal-specification transfer.
- LIBERO-100KindSuite
LIBERO-10 plus LIBERO-90 long-horizon mix.
Data composition
- Size
Four lifelong suites on a robosuite/MuJoCo Franka tabletop: Spatial, Object, Goal, and LIBERO-100 (LIBERO-10 + LIBERO-90). Official demos on yifengzhu-hf/LIBERO-datasets; LeRobot conversion on lerobot/libero.
- Sources
yifengzhu-hf/LIBERO-datasets · lerobot/libero · github.com
- Splits
libero_spatial · libero_object · libero_goal · libero_10 · libero_90
- Modalities
language · vision · action · state
- License
mit
- Notes
WorldFoundry can import official eval_result trees and also wire closed-loop execution; suite choice and seeds must match the upstream protocol to compare.
Metrics
Metric
- DirectionHigher is better
success_ratePrimary episode success rate over evaluated rollouts.
PrimarySuccess Rate
- DirectionHigher is better
task_successPer-task success aggregate.
- DirectionHigher is better
episode_successPer-episode success indicator aggregate.
- DirectionHigher is better
action_accuracyOffline action-prediction accuracy against reference actions.
Leaderboard
Results from the paper (not a live board; not WorldFoundry-run scores). Lifelong-learning baselines from the original paper, not a later VLA board. LIBERO: Benchmarking Knowledge Transfer for Lifelong Robot Learning (2023).
| Model | LIBERO-Spatial AUC (ResNet-T) |
|---|---|
| PackNet | 0.63 |
| Experience Replay | 0.56 |
| Sequential fine-tuning | 0.20 |
| EWC | 0.06 |
How to run
Import an official result tree (no simulator):
worldfoundry-eval zoo benchmark-run \
  --benchmark-id libero \
  --mode official-validation \
  --official-results-path <official_results.json> \
  --output-dir tmp/libero/official-validation \
  --json
Closed-loop execution needs WORLDFOUNDRY_LIBERO_ROOT (optional override of the runtime/repo root), suite assets, and a matching policy. Default import path when you omit --official-results-path is WORLDFOUNDRY_LIBERO_RESULTS_PATH. Shared asset stacks: libero_source_assets, libero_dataset_assets.
In-tree pointers:
worldfoundry/data/benchmarks/tasks/external/libero.yaml
cache/worldfoundry/data/hfd_datasets/yifengzhu-hf__LIBERO-datasets
cache/worldfoundry/data/hfd_datasets/lerobot__libero
cache/vla_va_wam/repos/Lifelong-Robot-Learning--LIBERO
Outputs under --output-dir include scorecard.json (primary key success_rate), run_manifest.json, results.jsonl, and metrics/summary.json.