
LikePhys
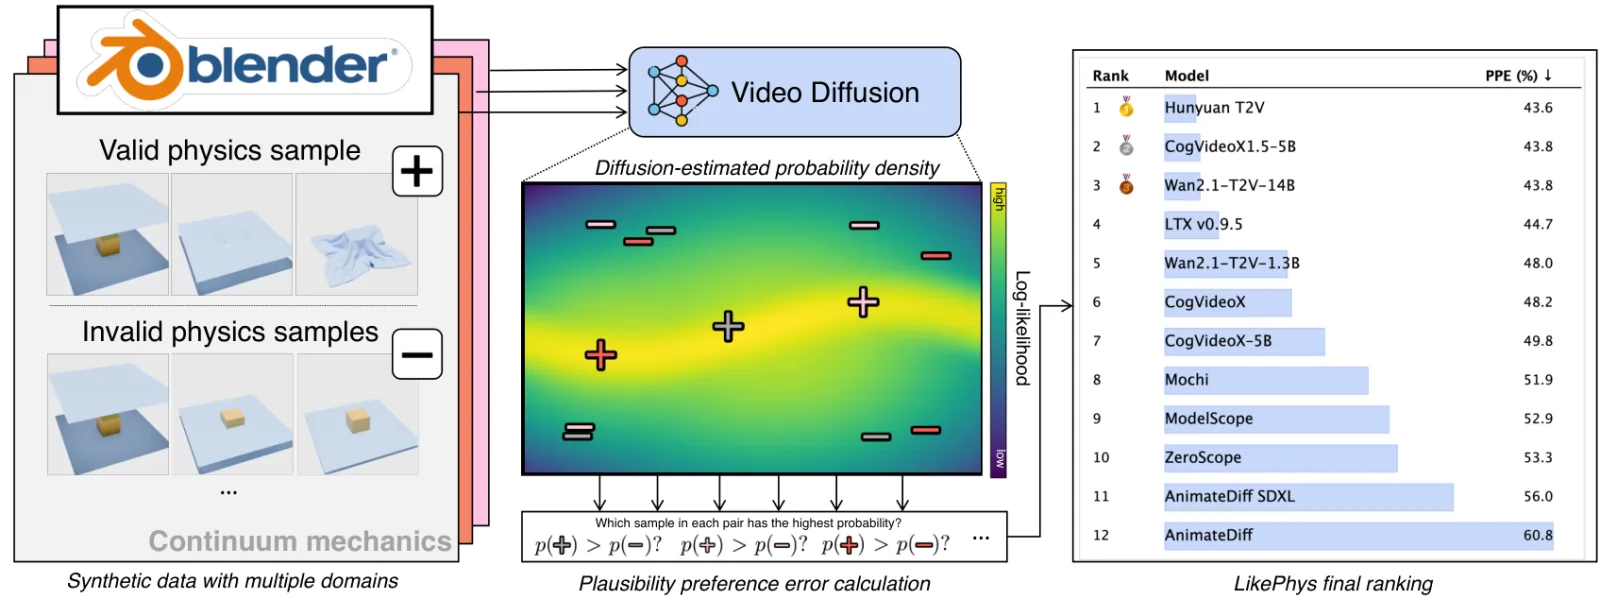
LikePhys (University of Oxford, ICLR 2026) is a training-free likelihood probe, not a generation bench. It does not score videos you generate. For each of 12 simulated scenarios (rigid bodies, fluids, deformables, optics), it pairs a physically valid clip with matched implausible variations and asks whether the diffusion model assigns higher likelihood (lower denoising ELBO) to the valid clip. The primary metric is mis-rank rate — how often the model prefers the implausible variation. Lower is better everywhere.
That is the opposite job from Physics-IQ (continue a filmed scene) and from PhyGenBench (judge a generated T2V clip).
Paper: LikePhys. Project: yuanjianhao508.github.io/LikePhys. Code: YuanJianhao508/LikePhys. Clips: JianhaoDYDY/LikePhys-Benchmark (920 clips).
WorldFoundry recomputes the official mis-rank formulas in tree (compute_misrank_normalized + read_exp_final.py filters). Driving the upstream ELBO probe needs a caller-supplied LikePhys checkout (WORLDFOUNDRY_LIKEPHYS_EVALUATOR_ROOT), CUDA, and the probed checkpoints — WorldFoundry does not vendor the forked diffusers pipelines.
Dimensions
- Model likelihood probeKindTask
Scores the diffusion model itself (denoising ELBO on paired clips). There is no candidate-video input and no generation leaderboard.
- Rigid bodyKindCategory
Ball drop, ball collision, pendulum, block slide, and pyramid.
- FluidsKindCategory
Droplet, faucet, and river scenarios.
- DeformableKindCategory
Cloth drape and waving flag.
- OpticsKindCategory
Moving-light and moving-camera shadow scenarios.
Data composition
- Size
12 simulated scenarios × 10 subgroups; catalog records 920 clips (physically valid clip + matched implausible variations). Clips come from JianhaoDYDY/LikePhys-Benchmark. WorldFoundry recomputes official mis-rank; the ELBO probe needs a caller-supplied LikePhys checkout.
- Sources
JianhaoDYDY/LikePhys-Benchmark · github.com
- Modalities
text · video
- License
apache-2.0
- Notes
Mis-rank is an error rate (lower is better). Paper filter_config exclusions apply unless --no-report-filter is set.
Metrics
Metric
- DirectionLower is better
likephys_misrank_rateVariation-weighted mean mis-rank rate over every scored scenario/variation pair (published ranking).
PrimaryLikePhys Mis-Rank Rate
- DirectionLower is better
likephys_dataset_weighted_misrank_rateMean over per-scenario mis-rank rates, weighting each of the 12 scenarios equally.
- DirectionLower is better
rigid_body_misrank_rateMis-rank over ball drop, ball collision, pendulum, block slide, and pyramid.
- DirectionLower is better
fluid_misrank_rateMis-rank over droplet, faucet, and river.
- DirectionLower is better
deformable_misrank_rateMis-rank over cloth drape and waving flag.
- DirectionLower is better
optics_misrank_rateMis-rank over moving-light and moving-camera shadow scenarios.
- DirectionLower is better
temporal_disorder_misrank_rateMis-rank restricted to the temporal_disorder variation shared by all 12 scenarios.
Leaderboard
Results from the paper (not a live board; not WorldFoundry-run scores). Paper overall PPE. Lower means stronger intuitive physics. LikePhys: Evaluating Intuitive Physics Understanding in Video Diffusion Models via Likelihood Preference (2025).
| Model | PPE average (lower is better) |
|---|---|
| Hunyuan T2V | 43.6 |
| Wan2.1-T2V-14B | 43.8 |
| CogVideoX1.5–5B | 43.8 |
| LTX v0.9.5 | 44.7 |
| Wan2.1-T2V-1.3B | 48.0 |
| CogVideoX-2B | 48.2 |
| CogVideoX-5B | 49.8 |
| Mochi | 51.9 |
How to run
Import results_<model>.json files (or a directory of <scenario>/results_<probe_model>.json) and recompute mis-rank:
worldfoundry-eval zoo benchmark-run \
  --benchmark-id likephys \
  --mode official-validation \
  --official-results-path <likephys_results_root> \
  --output-dir tmp/likephys/official-validation \
  --json
Use --probe-model when a results root holds several backends. --no-report-filter keeps variations the paper's filter_config excludes.
Run the upstream ELBO probe for one model on one scenario (CUDA + LikePhys checkout):
hf download JianhaoDYDY/LikePhys-Benchmark --repo-type dataset --local-dir "${WORLDFOUNDRY_LIKEPHYS_DATA_ROOT}"

WORLDFOUNDRY_LIKEPHYS_EVALUATOR_ROOT=/path/to/LikePhys \
${WORLDFOUNDRY_UNIFIED_PYTHON} \
  worldfoundry/evaluation/tasks/execution/runners/likephys/run_likephys_official_runner.py \
  --run-official \
  --probe-model wan2.1-T2V-1.3b \
  --scenario ball_drop \
  --benchmark-data-root "${WORLDFOUNDRY_LIKEPHYS_DATA_ROOT}" \
  --output-dir tmp/likephys/probe \
  --json
--dry-run prepares the workspace and prints commands. Outputs include scorecard.json (primary likephys_misrank_rate) and misrank_breakdown.json.