
PhyGenBench
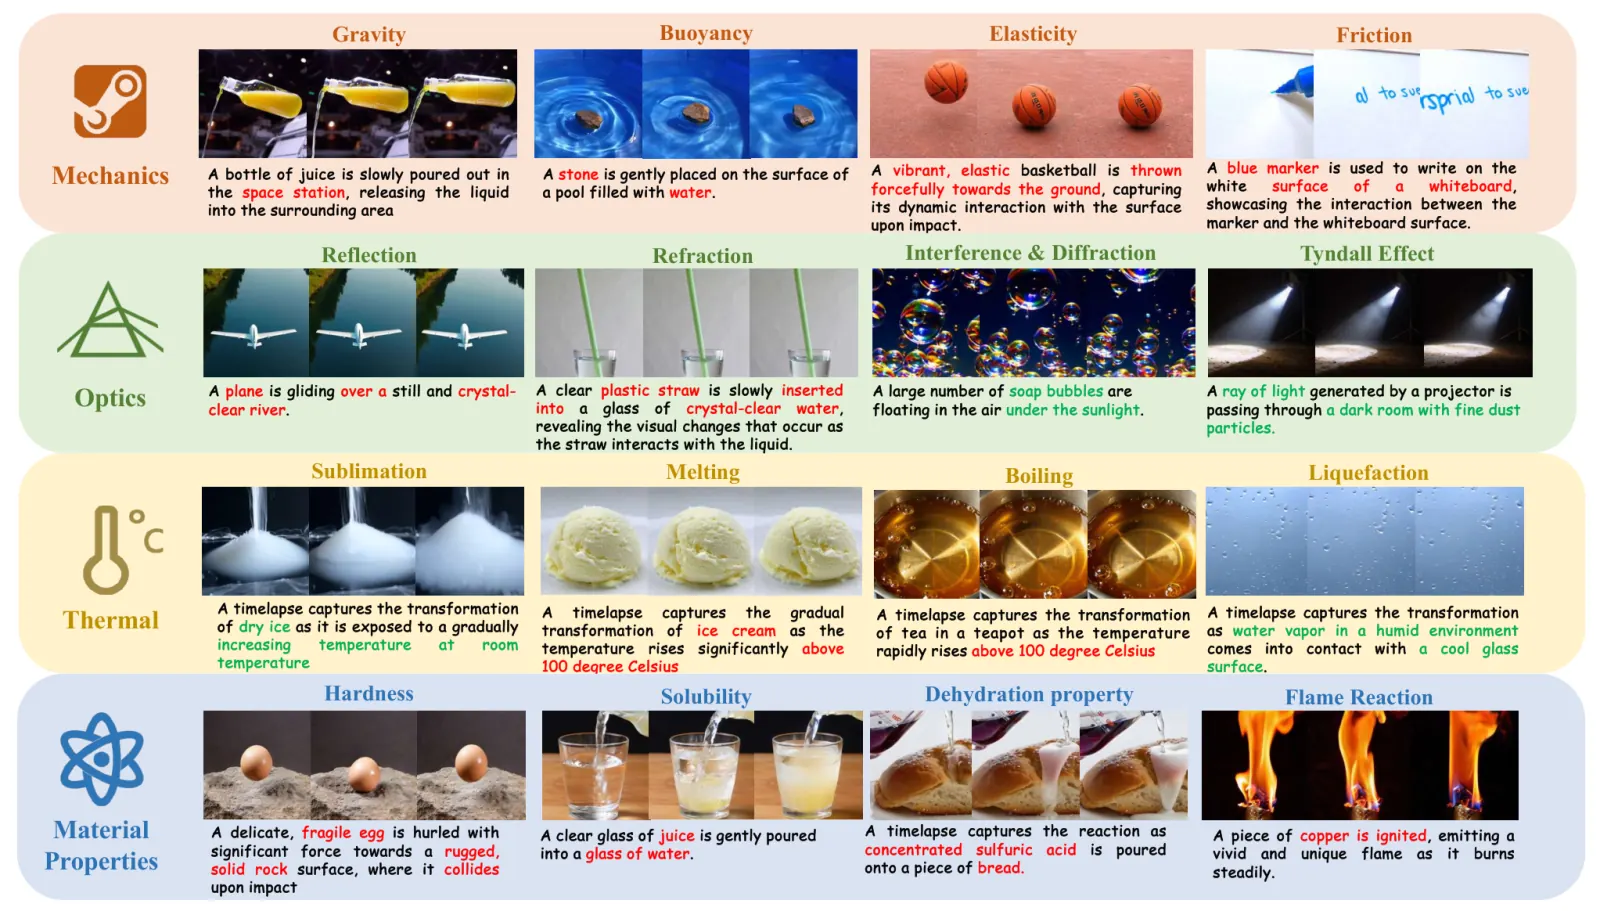
PhyGenBench (Shanghai AI Lab / OpenGVLab) asks whether a text-to-video generator respects physical commonsense. It ships 160 prompts spanning 27 claimed laws in four domains (mechanics, optics, thermal, materials). Upstream scoring is PhyGenEval: VQAScore, GPT-4o/LLaVA-style order checks, and InternVideo2 naturalness, then overall.py.
This is generation + hierarchical judges, not PhyGround (TI2V law-criteria 1–5), not PhysVidBench (caption QA), and not Physics-IQ (filmed continuation).
Paper: PhyGenBench. Project: phygenbench123.github.io. Code: OpenGVLab/PhyGenBench.
WorldFoundry bundles prompts.json and PhyGenEval overall.py. It imports an official result file, or runs bounded overall.py over already-prepared stage outputs. It does not run VQAScore, GPT-4o/LLaVA, or InternVideo2.
Dimensions
- T2V physical commonsenseKindTask
Text-to-video generation scored by PhyGenEval (VQAScore, order verification, naturalness). Not a filmed-continuation bench and not PhyGround's law-criteria judge.
- Physical commonsenseKindAxis
Whether generated motion respects the prompted physical phenomenon.
- Physical law adherenceKindAxis
Catalog axis over the claimed 27-law suite (mechanics, optics, thermal, materials).
Data composition
- Size
160 bundled T2V prompts spanning 27 claimed physical laws across four domains. WorldFoundry ships prompts.json and PhyGenEval overall.py; stage judges (VQAScore, GPT-4o/LLaVA, InternVideo2) are not run in tree.
- Sources
github.com
- Modalities
text · video
- Notes
Result import or prepared-stage overall.py aggregation only. Aggregation alone is not official PhyGenEval evidence.
Metrics
Metric
- DirectionHigher is better
physical_commonsensePhyGenEval physical-commonsense alignment imported or aggregated from stage outputs.
- DirectionHigher is better
physical_law_adherenceLaw-adherence family when the imported result file exposes it.
- DirectionHigher is better
semantic_adherenceSemantic alignment of the generated video with the prompt.
- DirectionHigher is better
phygenbench_averageMean over available PhyGenBench families on the imported or aggregated surface.
PrimaryPhyGenBench Average
Leaderboard
Results from the paper (not a live board; not WorldFoundry-run scores). Towards World Simulator: Crafting Physical Commonsense-Based Benchmark for Video Generation (2024).
| Model | PhyGenEval average |
|---|---|
| Gen-3 | 0.51 |
| Kling | 0.49 |
| Vchitect 2.0 | 0.45 |
| CogVideoX 5B | 0.45 |
| Open-Sora V1.2 | 0.44 |
| Pika | 0.44 |
| CogVideoX 2B | 0.39 |
| Lavie | 0.36 |
How to run
Import an official result export:
worldfoundry-eval zoo benchmark-run \
  --benchmark-id phygenbench \
  --mode official-validation \
  --official-results-path <official_results.json> \
  --generated-artifact-dir <generated_videos> \
  --output-dir tmp/phygenbench/official-validation \
  --json
Aggregate prepared stage outputs with in-tree overall.py (not a substitute for the full judge stack):
${WORLDFOUNDRY_UNIFIED_PYTHON} \
  worldfoundry/evaluation/tasks/execution/runners/phygenbench/run_phygenbench_official_runner.py \
  --run-official \
  --generated-artifact-dir "${WORLDFOUNDRY_GENERATED_ARTIFACT_DIR}" \
  --output-dir tmp/phygenbench/official \
  --json
Outputs include scorecard.json (primary phygenbench_average).