PhyGround
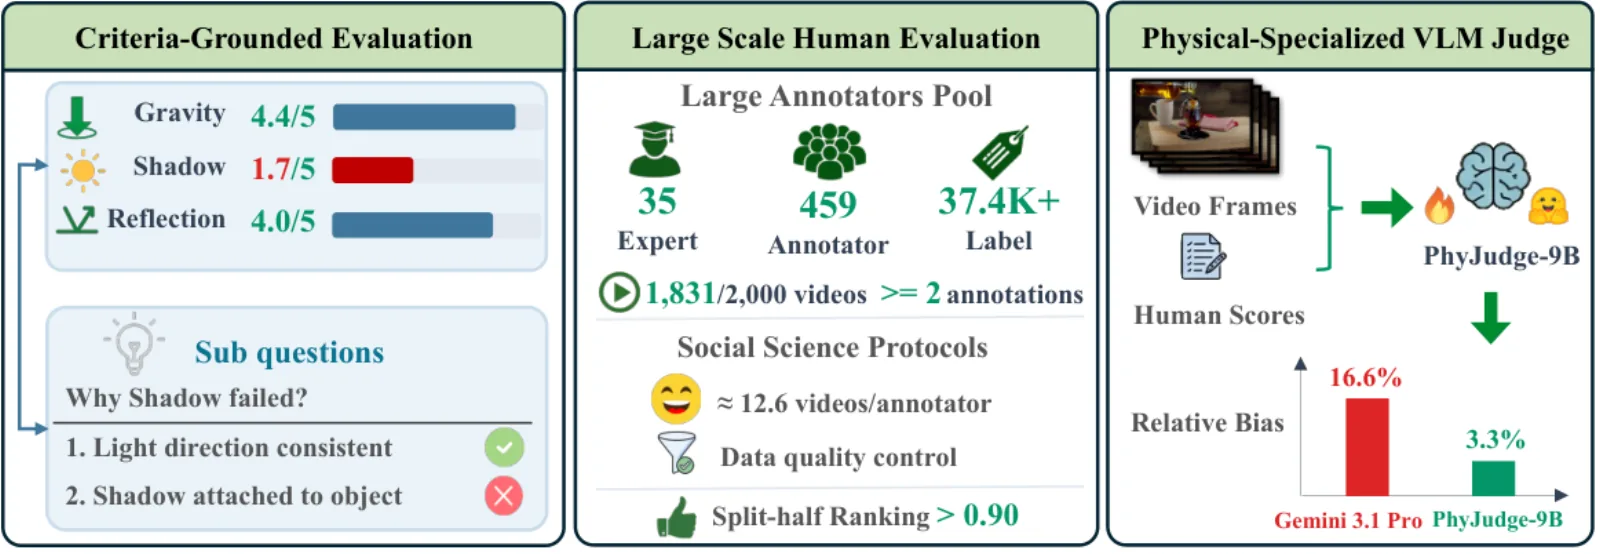
PhyGround (Northeastern University) is criteria grounding, not filmed continuation and not PhyGenEval. Each of 250 text+image-to-video prompts names an expected physical outcome and 2–4 applicable laws from a 13-law taxonomy (solid-body, fluids, optics). A judge (PhyJudge-9B or humans) rates the generated video 1–5 on semantic adherence, physical temporal validity, persistence, and each applicable law. That is closer to a rubric than to Physics-IQ mask IoU.
PhyGenBench is the T2V generation commonsense suite (160 prompts / 27 laws / PhyGenEval). PhyGround is TI2V law-criteria scoring on 250 prompts / 13 laws.
Paper: PhyGround. Project: phyground.github.io. Code: NU-World-Model-Embodied-AI/PhyGround. Data: NU-World-Model-Embodied-AI/phyground.
WorldFoundry imports scores.json from PhyJudge/vLLM or a cloud judge. It does not execute PhyJudge-9B over candidate videos.
Dimensions
- Criteria-grounded TI2VKindTask
Text+image-to-video prompts with an expected physical outcome and 2–4 applicable laws. Videos are judged 1–5 on criteria — not pixel-matched to a filmed future.
- Solid-body mechanicsKindCategory
Domain score over applicable solid-body laws in the 13-law taxonomy.
- Fluid dynamicsKindCategory
Domain score over applicable fluid-dynamics laws.
- OpticsKindCategory
Domain score over applicable optics laws.
Data composition
- Size
250 text+image-to-video prompts over a 13-law taxonomy (solid-body, fluids, optics). WorldFoundry imports PhyJudge/human scores.json; it does not run PhyJudge-9B.
- Sources
NU-World-Model-Embodied-AI/phyground · github.com
- Modalities
image · text · video
- Notes
Judge outputs live under annotations/ or --official-results-path. Use --result-model-id when a file holds several model ids.
Metrics
Metric
- DirectionHigher is better
semantic_adherence1–5 semantic alignment with the prompt, then normalized.
- DirectionHigher is better
physical_temporal_validity1–5 physical temporal validity of the generated event.
- DirectionHigher is better
persistence1–5 object/state persistence through the clip.
- DirectionHigher is better
solid_body_scoreAggregate over applicable solid-body laws for that video.
- DirectionHigher is better
fluid_dynamics_scoreAggregate over applicable fluid-dynamics laws.
- DirectionHigher is better
optics_scoreAggregate over applicable optics laws.
- DirectionHigher is better
phyground_overallImported overall after general dimensions and domain scores.
PrimaryPhyGround Overall
Leaderboard
Results from the paper (not a live board; not WorldFoundry-run scores). PhyGround: Benchmarking Physical Reasoning in Generative World Models (2026).
| Model | Overall (1–5 human) |
|---|---|
| Wan2.2-27B-A14B | 3.28 |
| Veo-3.1closed | 3.28 |
| OmniWeaving | 3.10 |
| Cosmos-14B | 2.91 |
| LTX-2.3-22B | 2.69 |
| Wan2.2-TI2V-5B | 2.63 |
| Cosmos-2B | 2.58 |
| LTX-2-19B | 2.56 |
How to run
Stage the data root (prompts/, first_images/, annotations/, videos/<model_id>/) and import judge outputs:
hf download NU-World-Model-Embodied-AI/phyground --repo-type dataset --local-dir <phyground_data_root>

worldfoundry-eval zoo benchmark-run \
  --benchmark-id phyground \
  --mode official-validation \
  --benchmark-data-root <phyground_data_root> \
  --generated-artifact-dir <phyground_data_root>/videos/<model_id> \
  --result-model-id <model_id> \
  --output-dir tmp/phyground/official-validation \
  --json
Or pass --official-results-path at the scores.json / annotations/ file. --prompt-manifest optionally checks prompt coverage. Outputs include scorecard.json (primary phyground_overall).