PhysVidBench
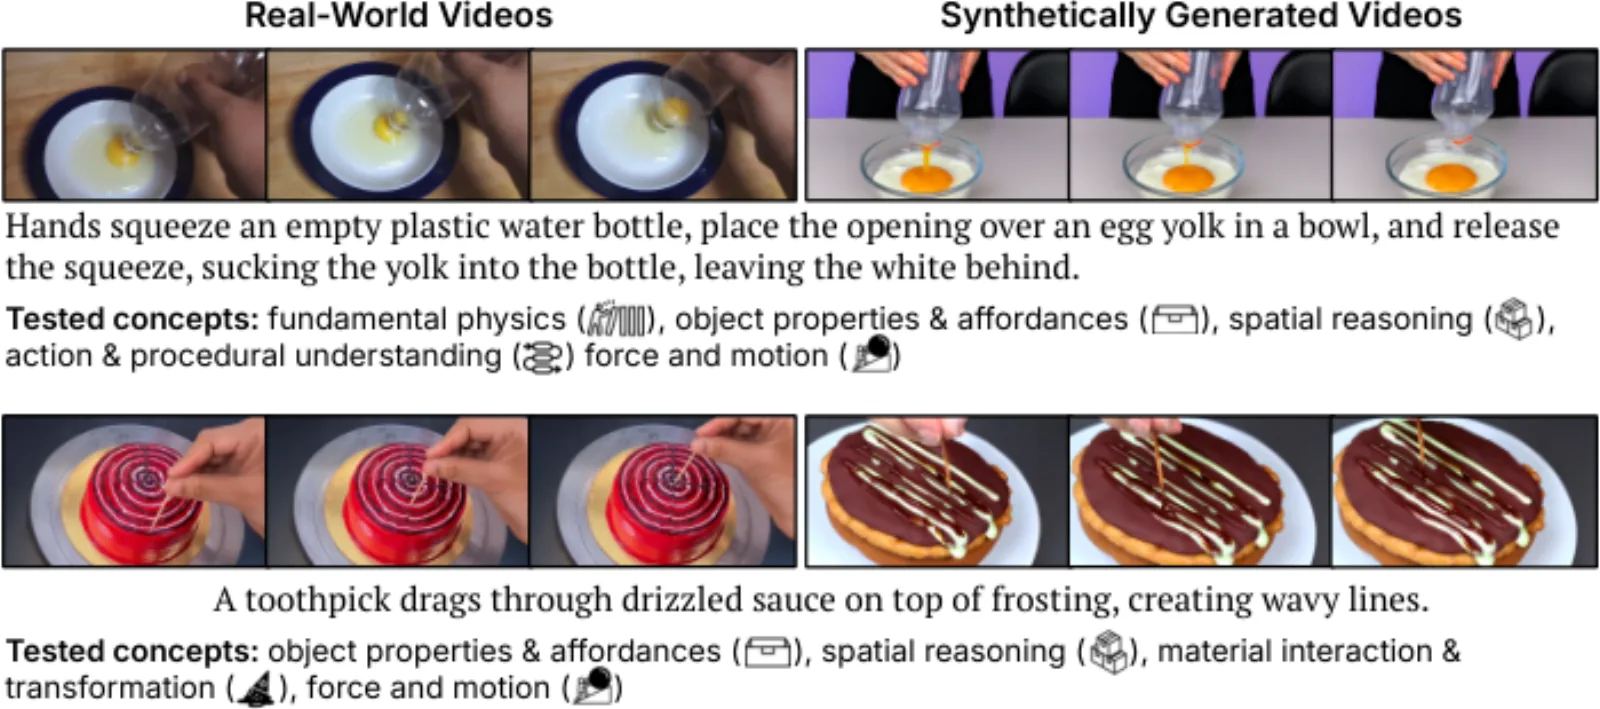
PhysVidBench (Koç University / Cyberiada) is caption-mediated QA, not pixel matching and not PhyGenEval. A T2V model generates a video; upstream AuroraCap captions it; an LLM answers physics yes/no questions about that caption (affordance, tool use, materials, temporal dynamics). Catalog records 383 prompts and 4123 questions (cc-by-4.0).
PhyGenBench judges the video with VQAScore/VLM stages. PhyGround applies 1–5 law criteria. PhysVidBench never looks at pixels in tree — only captions + questions.
Paper: PhysVidBench. Project: cyberiada.github.io/PhysVidBench. Code: ensanli/PhysVidBenchCode. Data: Anonymousny/PhysVidBench.
WorldFoundry bundles prompts_questions.csv and caption tracks. It imports upstream output.csv, or runs bounded Gemini QA on captions you supply. It does not run AuroraCap on your videos and cannot prove those captions came from them.
Dimensions
- Caption-mediated QAKindTask
Generated videos are captioned (upstream AuroraCap); an LLM answers physics yes/no questions about the caption — not pixel IoU against a real future.
- AffordanceKindCategory
Interaction and affordance questions.
- Tool useKindCategory
Tool-mediated physical interaction consistency.
- MaterialsKindCategory
Material-property consistency questions.
- Temporal dynamicsKindCategory
Physical temporal-dynamics questions.
Data composition
- Size
Catalog records 383 prompts and 4123 questions (cc-by-4.0). WorldFoundry bundles prompts_questions.csv and caption tracks; it imports output.csv or runs bounded Gemini QA on supplied captions. AuroraCap captioning from your videos is not in tree.
- Sources
Anonymousny/PhysVidBench · github.com
- Modalities
text · video
- License
cc-by-4.0
- Notes
Gemini QA over supplied captions is not official pipeline evidence. Only upstream full-pipeline output.csv import carries official weight.
Metrics
Metric
- DirectionHigher is better
physical_commonsense_accuracyOverall yes/no QA accuracy on physics questions about the caption.
- DirectionHigher is better
affordance_understandingAffordance and interaction question family.
- DirectionHigher is better
tool_use_consistencyTool-mediated interaction question family.
- DirectionHigher is better
material_property_consistencyMaterial-property question family.
- DirectionHigher is better
temporal_dynamics_consistencyPhysical temporal-dynamics question family.
- DirectionHigher is better
physvidbench_averageMean over available QA score families.
PrimaryPhysVidBench Average
Leaderboard
Results from the paper (not a live board; not WorldFoundry-run scores). Paper Average column (main score, not the parenthetical delta). PhysVidBench: Language-Grounded Evaluation of Physical Commonsense in Text-to-Video Models (2025).
| Model | Average |
|---|---|
| Wan2.1 (14B) | 34.1 |
| MAGI-1 | 32.6 |
| Wan2.1 (1.3B) | 30.6 |
| HunyuanVideo | 30.0 |
| CogVideoX (2B) | 25.6 |
| VideoCrafter2 | 22.1 |
| LTX-Video | 21.0 |
| CogVideoX (5B) | 21.0 |
How to run
Import an upstream QA export:
worldfoundry-eval zoo benchmark-run \
  --benchmark-id physvidbench \
  --mode official-validation \
  --official-results-path <output.csv> \
  --generated-artifact-dir <generated_videos> \
  --output-dir tmp/physvidbench/official-validation \
  --json
Bounded Gemini QA over supplied (or bundled) captions — not official pipeline evidence:
${WORLDFOUNDRY_UNIFIED_PYTHON} \
  worldfoundry/evaluation/tasks/execution/runners/physvidbench/run_physvidbench_official_runner.py \
  --run-official \
  --generated-artifact-dir "${WORLDFOUNDRY_GENERATED_ARTIFACT_DIR}" \
  --captions-dir worldfoundry/data/benchmarks/assets/physvidbench/captions \
  --output-dir tmp/physvidbench/official \
  --json
Select the judge with WORLDFOUNDRY_PHYSVIDBENCH_JUDGE_BACKEND. Outputs include scorecard.json (primary physvidbench_average) and output.csv.