SimplerEnv
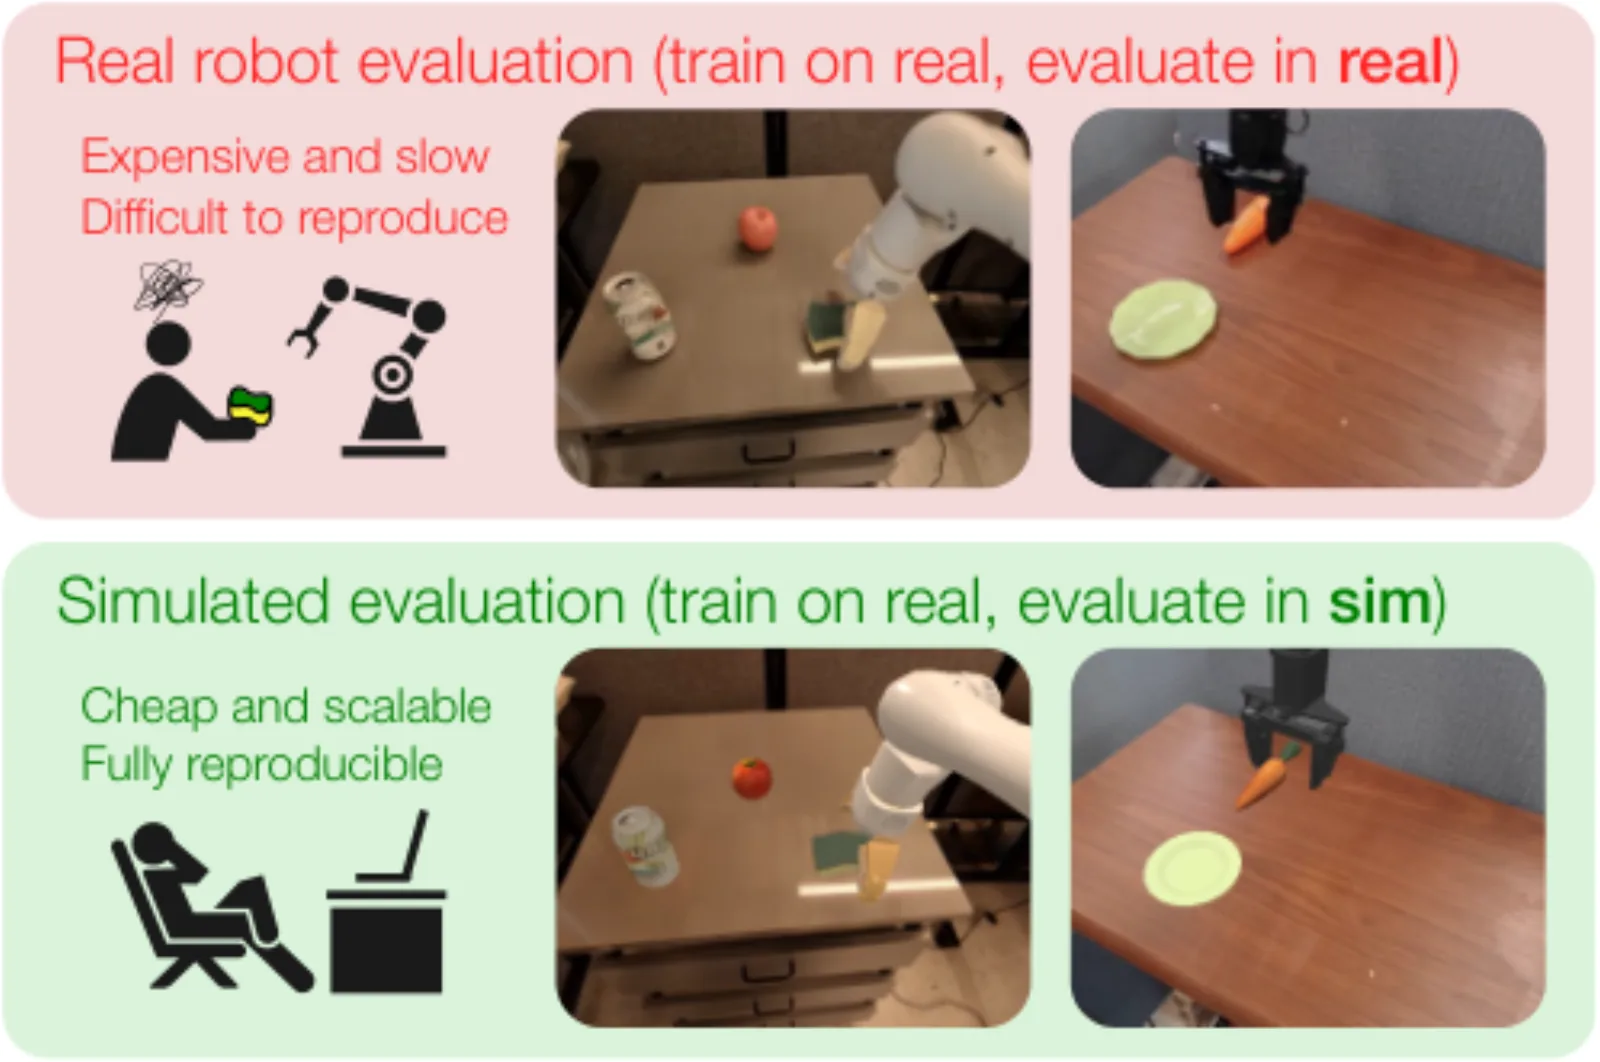
SimplerEnv (SIMPLER — Simulated Manipulation Policy Evaluation for Real Robot Setups) is a real-to-sim bench from UC San Diego and Google DeepMind (with Stanford and UC Berkeley). ManiSkill2 / SAPIEN scenes are calibrated so that policies such as RT-1, RT-1-X, and Octo rank in simulation the way they rank on the corresponding Google Robot and WidowX / Bridge real setups. The point of the suite is that correlation, not a new kitchen asset pack.
Paper: OpenReview. Project: simpler-env.github.io. Code: simpler-env/SimplerEnv (MIT).
WorldFoundry does not run those scenes. It normalizes official rollout exports into the scorecard. Upstream rollouts still need the ManiSkill2/SAPIEN stack and the embodiment assets. Repo mirror: cache/vla_va_wam/repos/simpler-env--SimplerEnv.
Dimensions
- Google RobotKindSplit
ManiSkill2/SAPIEN scenes calibrated to the Google Robot real-world setup.
- WidowX / BridgeKindSplit
WidowX scenes aligned with BridgeData real-robot evaluations.
Data composition
- Size
SIMPLER (Simulated Manipulation Policy Evaluation for Real Robot Setups): real-to-sim evaluation so RT-1, RT-1-X, Octo and similar policies can be ranked in simulation with demonstrated real-world correlation.
- Sources
github.com
- Splits
google_robot · widowx_bridge
- Modalities
language · vision · action · state
- License
mit
- Notes
SimplerEnv evaluates policy rollouts in simulator; generated result files and rollout logs are normalized by WorldFoundry.
Metrics
Metric
- DirectionHigher is better
success_ratePrimary episode success rate over evaluated rollouts.
PrimarySuccess Rate
- DirectionHigher is better
task_successPer-task success aggregate.
- DirectionHigher is better
episode_successPer-episode success indicator aggregate.
- DirectionHigher is better
rewardMean episode reward / return.
Leaderboard
Results from the paper (not a live board; not WorldFoundry-run scores). SIMPLER visual-matching column from the paper. Real-robot rates are reported separately. Evaluating Real-World Robot Manipulation Policies in Simulation (2024).
| Model | Avg. sim success (visual matching) |
|---|---|
| RT-1 (converged) | 0.857 |
| RT-2-X | 0.787 |
| RT-1 (15%) | 0.710 |
| RT-1-X | 0.567 |
| RT-1 (single-task) | 0.403 |
| Octo-Base | 0.170 |
| RT-1 (begin) | 0.027 |
How to run
worldfoundry-eval zoo benchmark-run \
  --benchmark-id simpler-env \
  --mode official-validation \
  --official-results-path <official_results.json> \
  --output-dir tmp/simpler-env/official-validation \
  --json
Default import path: WORLDFOUNDRY_SIMPLERENV_RESULTS_PATH. Manifest: worldfoundry/data/benchmarks/tasks/external/simpler-env.yaml. Outputs: scorecard.json (primary success_rate) and raw_results.jsonl.