Action Chunking Transformer
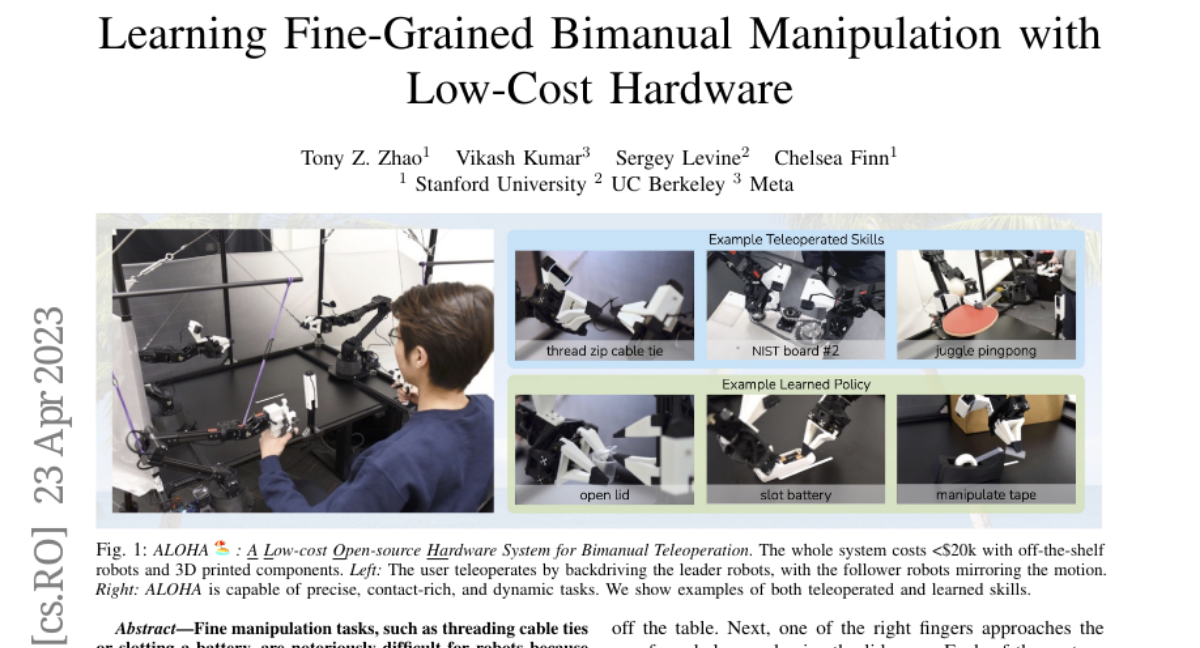
ALOHA ACT: DETR-VAE emits a 50-step bimanual chunk; WorldFoundry runs inference in-tree and does not ship a checkpoint.
ACT (Action Chunking Transformer) is the ALOHA imitation policy: instead of one joint target per step, it emits a short horizon of future actions so control stays smooth. At test time the CVAE encoder is dropped and the style latent is the prior mean (zero). The official paper is Learning Fine-Grained Bimanual Manipulation with Low-Cost Hardware (arXiv 2304.13705). The project page is tonyzhaozh.github.io/aloha. The GitHub tree is tonyzhaozh/act.
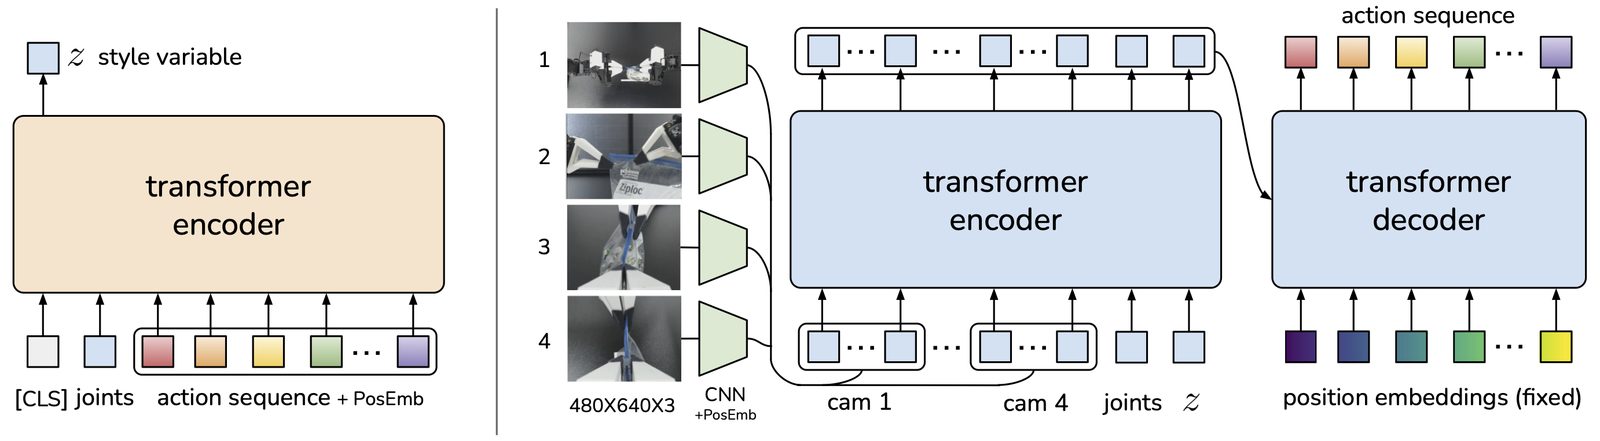
WorldFoundry keeps the full inference stack — DETR-VAE, transformer encoder-decoder, ResNet-18 backbone, preprocessing, and temporal aggregation — under worldfoundry/synthesis/action_generation/act. There is no catalog variant and no official weight file. Checkpoint-backed predict_action is implemented; it stays gated on a caller-staged policy_best.ckpt plus matching dataset_stats.pkl. Static and CPU contract checks pass. Alias action-chunking-transformer resolves here.
Build your run
ACTPipelineworldfoundry.pipelines.component_pipelinesinteractive-videoworldfoundry.pipelineworldfoundry-eval run \
act \
--pipeline.task-profile interactive-video \
--jsonWhat it is for
Use ACT as a fixed-embodiment action-chunking baseline — not an open-vocabulary VLA. Recorded inputs are RGB (image) and instruction; prompt is unused. The pipeline is ACTPipeline; the artifact is act_action_trace.json. The natural local target in this catalog is a scripted sim transfer-cube policy you train or stage yourself, then replay against held-out demonstrations.
This is the page for runner parity, checkpoint staging, and the chunk contract before you move to larger language-conditioned stacks.
Runtime contract
In-tree defaults (not a downloaded checkpoint):
- Cameras:
cam_head,cam_right_wrist,cam_left_wrist - Proprioception:
state_dim14 (two 7-DoF arms) chunk_size50,temporal_agg=true, backbone ResNet-18- Transformer: 4 encoder / 7 decoder layers, hidden 512, 8 heads
The paper’s ALOHA hardware write-up uses four 480×640 cameras at 50 Hz and discusses a 90-step real-robot chunk. That is upstream hardware, not the WorldFoundry config above. Actions are an action_chunk plus proprio / action-space metadata.
Stage weights here:
${WORLDFOUNDRY_CKPT_DIR}/embodied_action/act/sim_transfer_cube_scripted/policy_best.ckpt
plus the matching dataset_stats.pkl beside it. PyTorch loads with weights_only=true and strict keys. Stats use a NumPy-only reader — no upstream pickle execution.
Running in WorldFoundry
Dedicated environment worldfoundry-act (Python 3.10, CUDA 11.8 or newer). No package or checkpoint is downloaded at runtime. After staging:
worldfoundry-eval run actNo license is recorded in this repository. Confirm the upstream ACT / ALOHA terms before production use.