AHA-WAM
World-action model for RoboTwin 2.0: video + action experts, six-frame history, 16×14 chunks. MIT license. A100 Workspace validated; not a closed-loop score.
AHA-WAM is a world-action model for manipulation: a video expert and an action expert share a mixture cache so the policy can use predictive world modeling at infer time. WorldFoundry runs the exact video/action experts, mixture-cache editor, six-frame history, two-phase chunk inference, Wan VAE, and UMT5 encoder in process. Trainers, simulators, and deployment servers are excluded. Pipeline: AHAWAMPipeline. Aliases aha-wam and aha-wam-robotwin resolve here.
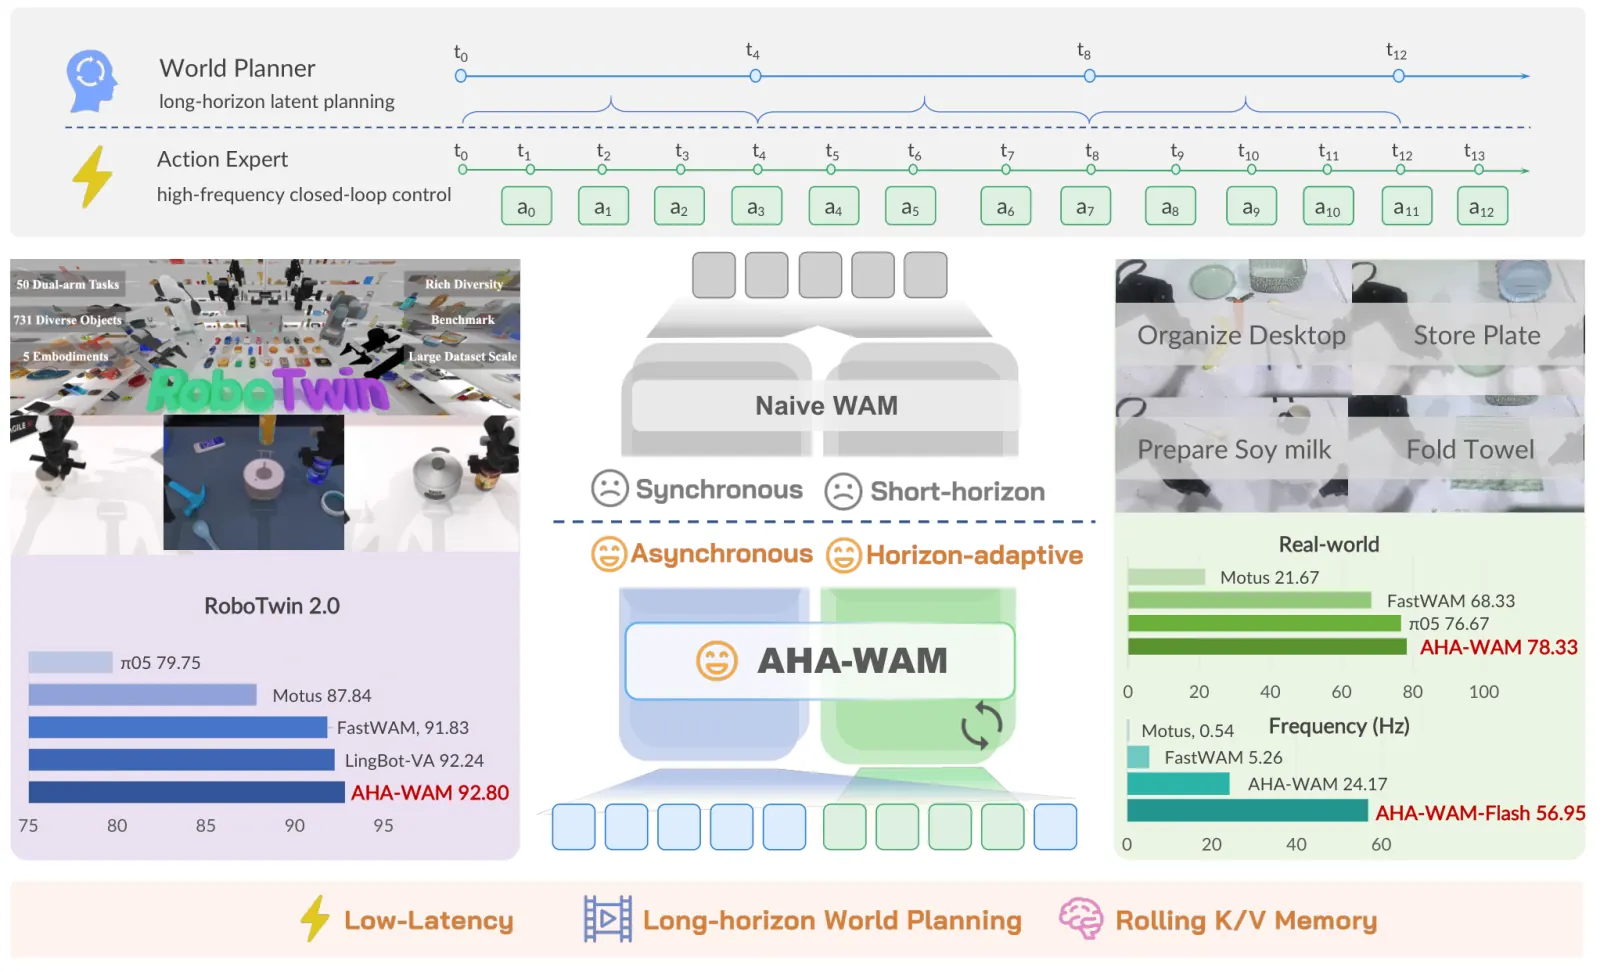
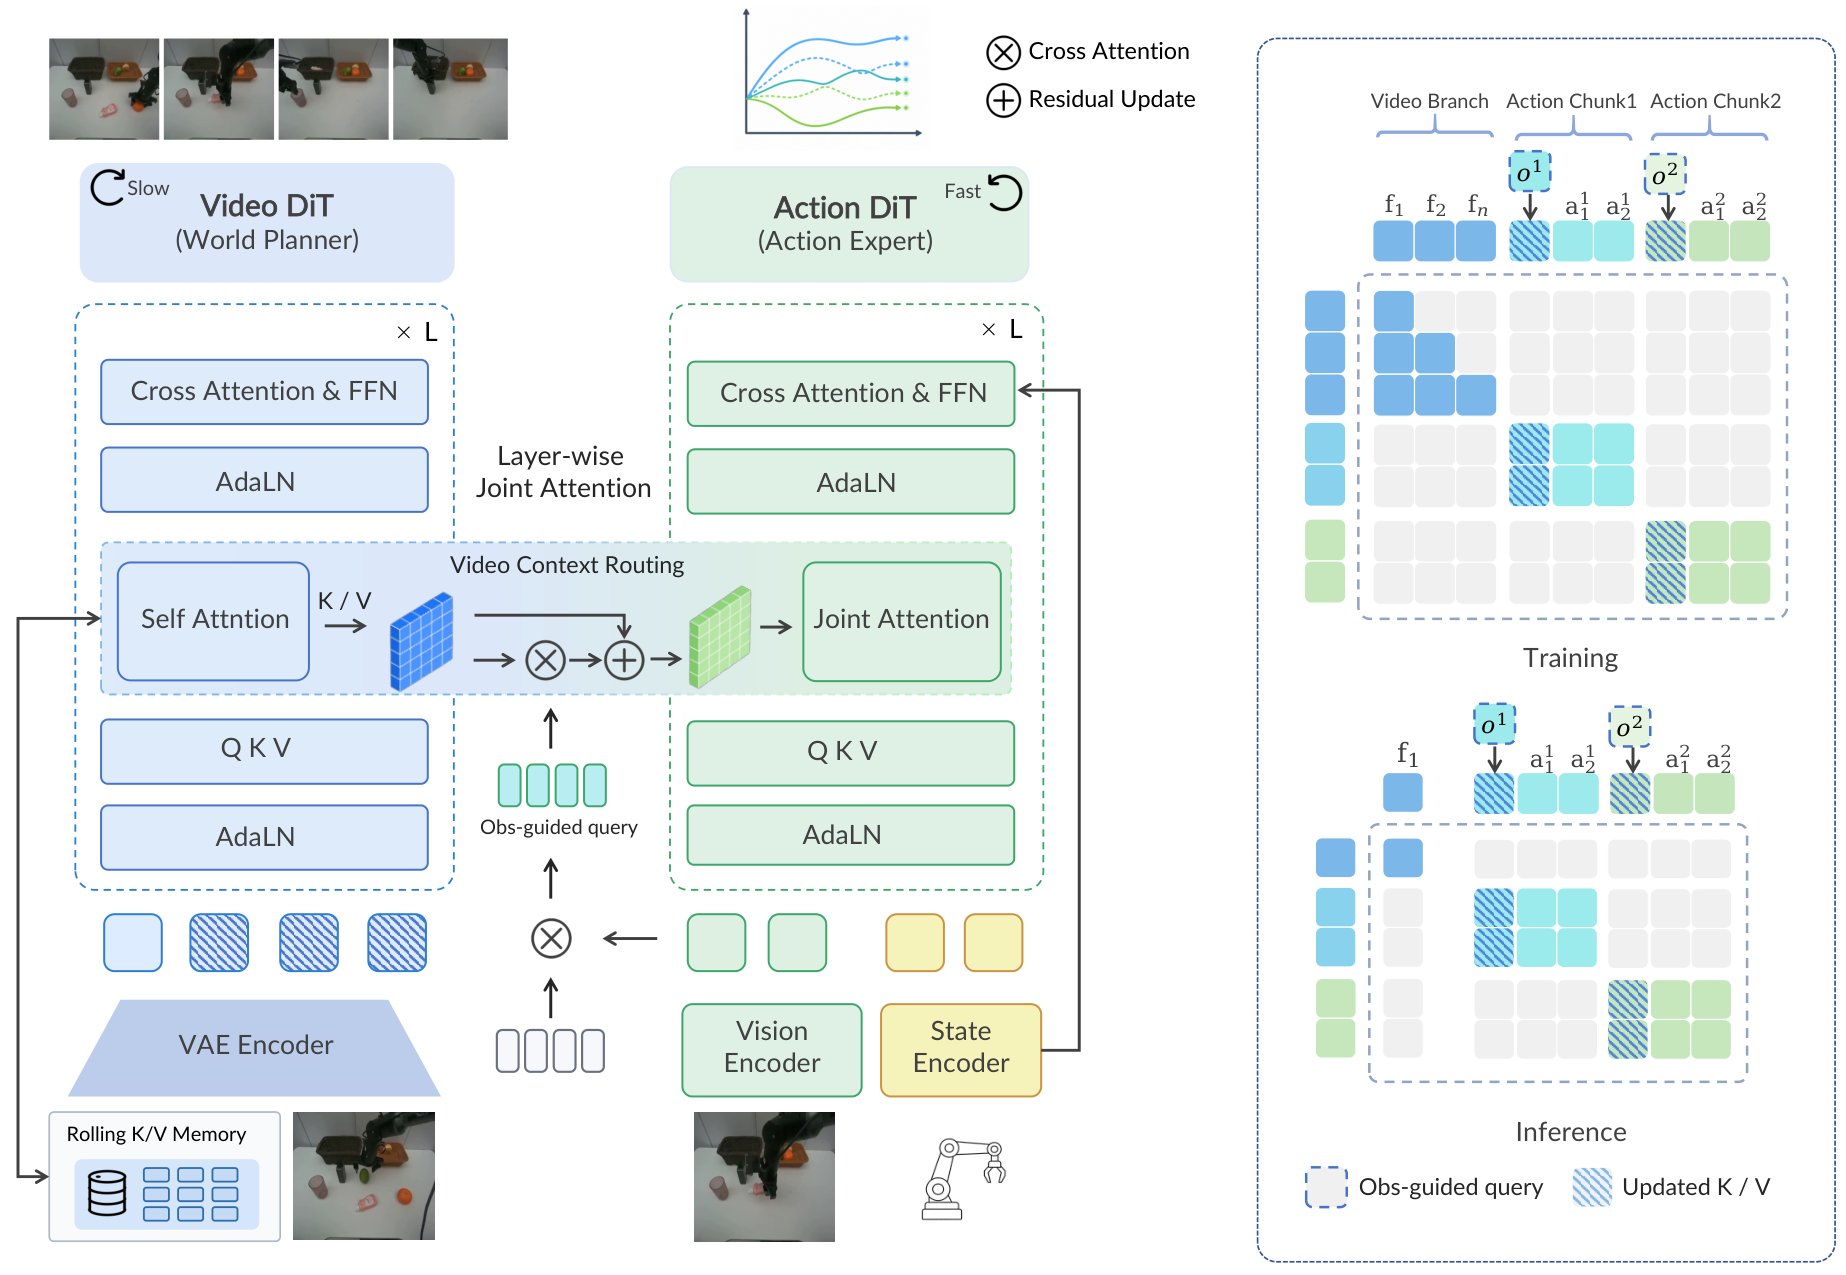
The official paper is on arXiv 2606.09811. Project: serene-sivy.github.io/aha-wam. Code: Serene-SIVY/AHA-WAM. License: MIT. Recorded policy: SereneC/AHA-WAM-RoboTwin2.0 (robotwin_ahawam.pt). VAE and UMT5 come from DiffSynth-Studio/Wan-Series-Converted-Safetensors.
The released RoboTwin 2.0 checkpoint completed real A100 Workspace inference from three ALOHA views plus a 14-D state and returned a finite 16×14 open-loop chunk. Catalog runner is still unset — that is numerical checkpoint validation, not a closed-loop simulator score.
Build your run
AHAWAMPipelineworldfoundry.synthesis.action_generation.ahawam.pipelinedefaultworldfoundry.pipelineworldfoundry-eval run \
ahawam \
--pipeline.task-profile default \
--jsonWhat it is for
AHA-WAM RoboTwin chunk from three ALOHA views plus state.
Launch worldfoundry-eval run ahawam.
Score on RoboTwin 2.0 — the released checkpoint is trained for RoboTwin 2.0.
Runtime contract
Required: image and prompt; optional: model_id, state, preferred_cameras, image_size, configured_action_horizon, action_chunk_size, and default_chunks_per_video_prefill; artifacts: action_trace and ahawam_action_trace.json.
| Knob | Recorded value |
|---|---|
| Image size | 384×320 |
| Action horizon | 64 |
| Chunk size | 16 |
| Video prefill chunks | 2 (then KV refresh; up to six earlier prefill entries kept) |
Run in WorldFoundry
Status: Verified. Unified environment worldfoundry-unified-cu128 (Python 3.11, CUDA 12.8). Stage SereneC/AHA-WAM-RoboTwin2.0, DiffSynth-Studio/Wan-Series-Converted-Safetensors, and Wan-AI/Wan2.1-T2V-1.3B locally — missing files fail at load, nothing is downloaded. Run worldfoundry-eval run ahawam. Catalog VRAM is unset.