AnimateDiff
Shanghai AI Lab / CUHK MMLab motion-module T2V on SD 1.5. Runner-verified against the official RealisticVision demo; no local I2V or V2V.
AnimateDiff is the classic motion-module approach to text-to-video: a temporal module plugs into an existing Stable Diffusion 1.5 U-Net instead of training a video backbone from scratch. WorldFoundry's in-tree route is runner-verified — file SHA256 and decoded-pixel SHA256 matched the official RealisticVision scripts.animate demo. Aliases animate-diff and animate_diff resolve here.
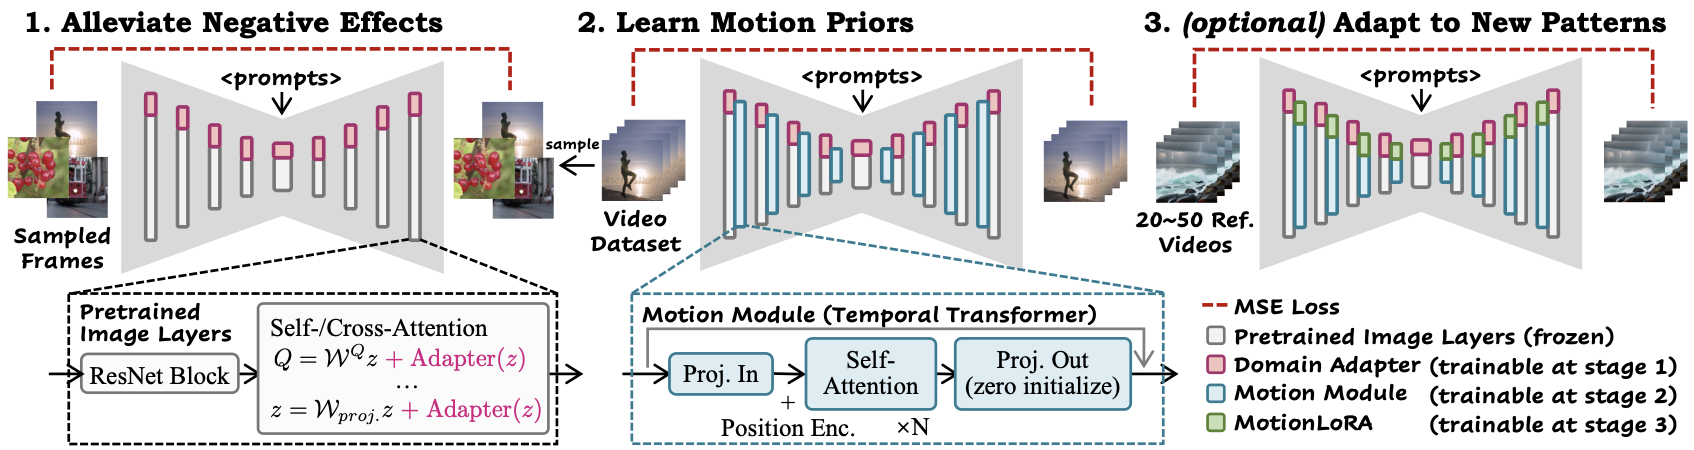
The paper is AnimateDiff: Animate Your Personalized Text-to-Image Diffusion Models without Specific Tuning. Project page: animatediff.github.io. Code: guoyww/AnimateDiff. The method overview above is the official architecture figure; paper.png is the title thumb only.
Build your run
AnimateDiffPipelineworldfoundry.pipelines.component_pipelinesinteractive-videoworldfoundry.pipelineworldfoundry-eval run \
animatediff \
--pipeline.task-profile interactive-video \
--jsonWhat it is for
Prompt-only T2V through AnimateDiffPipeline: required prompt, artifact recorded as animatediff.gif in the catalog (the runtime normalizes the written file to MP4). Passing image or video raises — this integration is not I2V or V2V. SparseCtrl configs exist upstream in the same GitHub tree; they are not this card.
Swap the T2I backbone (Realistic Vision is the verified demo) while keeping the motion module. Compare clip quality and temporal consistency on VBench — a listed suite, not an ingested rank.
Inference
Sampler is DDIM (DDIMScheduler from inference-v2.yaml). WorldFoundry generate_video defaults:
| Knob | Default | Notes |
|---|---|---|
| Size | 256×256 | height/width must be divisible by 8 |
| Frames | 16 | video_length / num_frames |
| Steps | 25 | infer_steps |
| Guidance | 7.5 | cfg_scale |
| FPS | 8 | written MP4 |
| Seed | 1234 |
The official RealisticVision prompt YAML that the parity run matched uses the same 25 steps but guidance 8, and either mm_sd_v15_v2.ckpt + inference-v2.yaml or v3_sd15_mm.ckpt + inference-v3.yaml. Default motion module path is $WORLDFOUNDRY_HFD_ROOT/guoyww--animatediff/mm_sd_v15_v2.ckpt; Realistic Vision weights come from guoyww/animatediff_t2i_backups. Catalog VRAM is unset.
Running in WorldFoundry
worldfoundry-eval run animatediff in worldfoundry-unified-cu128 (Python 3.11, CUDA 12.8). Official modules call .cuda() — CPU is rejected. Stage guoyww/animatediff, guoyww/animatediff_t2i_backups, stable-diffusion-v1-5/stable-diffusion-v1-5, and openai/clip-vit-large-patch14. Motion-module license on the recorded card is apache-2.0. Studio/API uses the same unified env after the recorded diffusers/transformers key-name shims.