Show-o
Show-o from National University of Singapore (Show Lab): multimodal-generation and text-to-image; Verified.
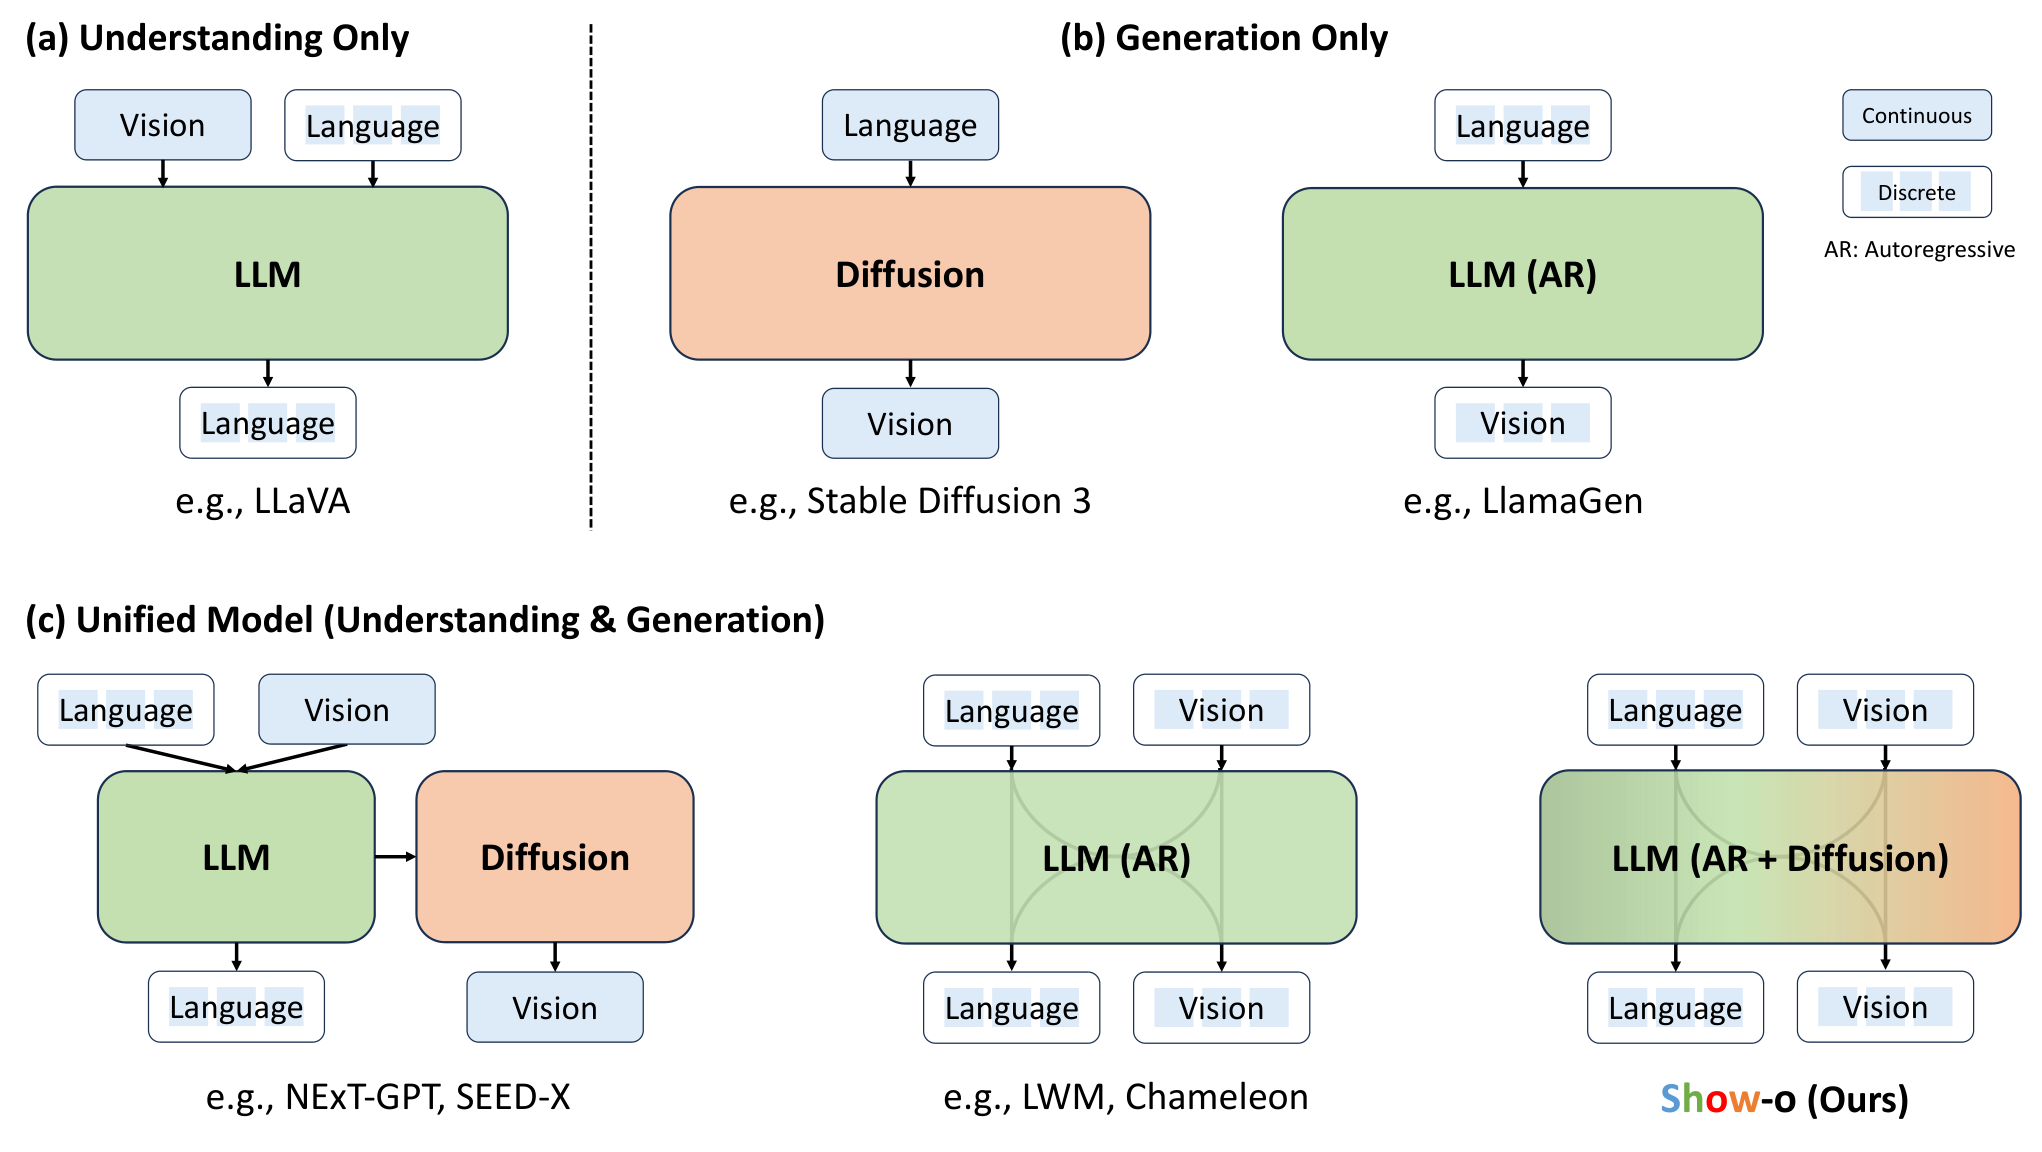
Show-o (Xie et al., Show Lab at NUS with ByteDance, arXiv 2408.12528) is a single 1.3B transformer that unifies multimodal understanding and generation. It is initialized from Phi-1.5 and, unlike systems that attach a separate diffusion expert to an MLLM, uses one set of weights for both.
The recorded paper is Show-o: One Single Transformer to Unify Multimodal Understanding and Generation (ICLR 2025, 2024).
Project page: showlab.github.io/Show-o. Code: showlab/Show-o.
Build your run
ShowOPipelineworldfoundry.pipelines.component_pipelinesdefaultworldfoundry.pipelineworldfoundry-eval run \
show-o \
--pipeline.task-profile default \
--jsonWhat it is for
Use show-o when the job is a catalog still image rather than video.
Image I/O uses the MAGVIT-v2 VQ tokenizer (showlab/magvitv2). The paper also studies continuous MAGVIT or CLIP-ViT features for understanding (Show-o† / Show-o‡); the released default and these catalog weights use discrete tokens for both understanding and generation. WorldFoundry's runtime lives under synthesis/visual_generation/show_o with a mode/prompt/image contract and microsoft/phi-1_5 plus showlab/show-o. It is published by National University of Singapore (Show Lab).
Catalog tasks include multimodal-generation and text-to-image. Catalog aliases include show_o and showo. Documented modalities: text and image in, image and text out.
Runtime contract
Optional prompt, input_path, interactions, fps, and guidance_scale; artifacts show_o.png.
CLI task profiles: default. WorldFoundry binds ShowOPipeline.
Family status: Verified.
The verified WorldFoundry route is T2I only — set mode accordingly and expect a generated_image artifact. Paper-default resolution is 256; the wrapper uses classifier-free guidance (default 3.0) and 18 discrete-diffusion steps. Weights are MIT at showlab/show-o, with MAGVIT-v2 and Phi-1.5 as recorded companions. Image understanding and editing modes exist in the paper but are not wired here.
Runtime source is vendored in-tree; current WorldFoundry wrapper supports t2i image generation.
Running in WorldFoundry
The catalog launch is worldfoundry-eval run show-o --pipeline.task-profile default. The command builder above switches --pipeline.task-profile among recorded tasks and still emits worldfoundry-eval run.
It runs in the unified environment worldfoundry-unified-cu128 (Python 3.11, CUDA 11.3).
Recorded weight repositories include showlab/show-o, showlab/magvitv2, and microsoft/phi-1_5. Prepare the environment and check local assets with bash scripts/inference/prepare_model_infer.sh show-o. Add --download to fetch missing public checkpoints.
Recorded licenses include mit; status: Verified.