CogVideoX
Zhipu THUDM open T2V/I2V family. 2B T2V, 5B T2V, and 5B I2V routes are runner-verified in-tree.
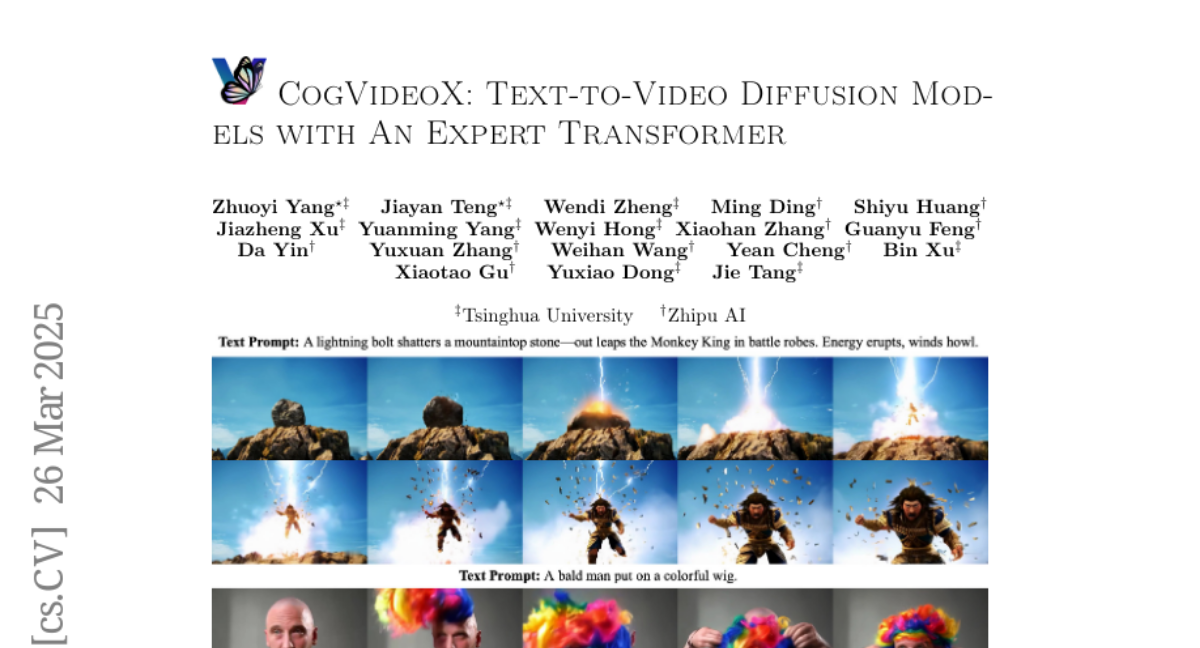
CogVideoX is Zhipu AI / THUDM's open video family and still one of the most cited open T2V/I2V baselines. The paper is CogVideoX: Text-to-Video Diffusion Models with An Expert Transformer. This catalog card serves three runnable variants through in-tree runtimes: 2B text-to-video, 5B text-to-video, and 5B image-to-video. Runner and demo parity are verified.
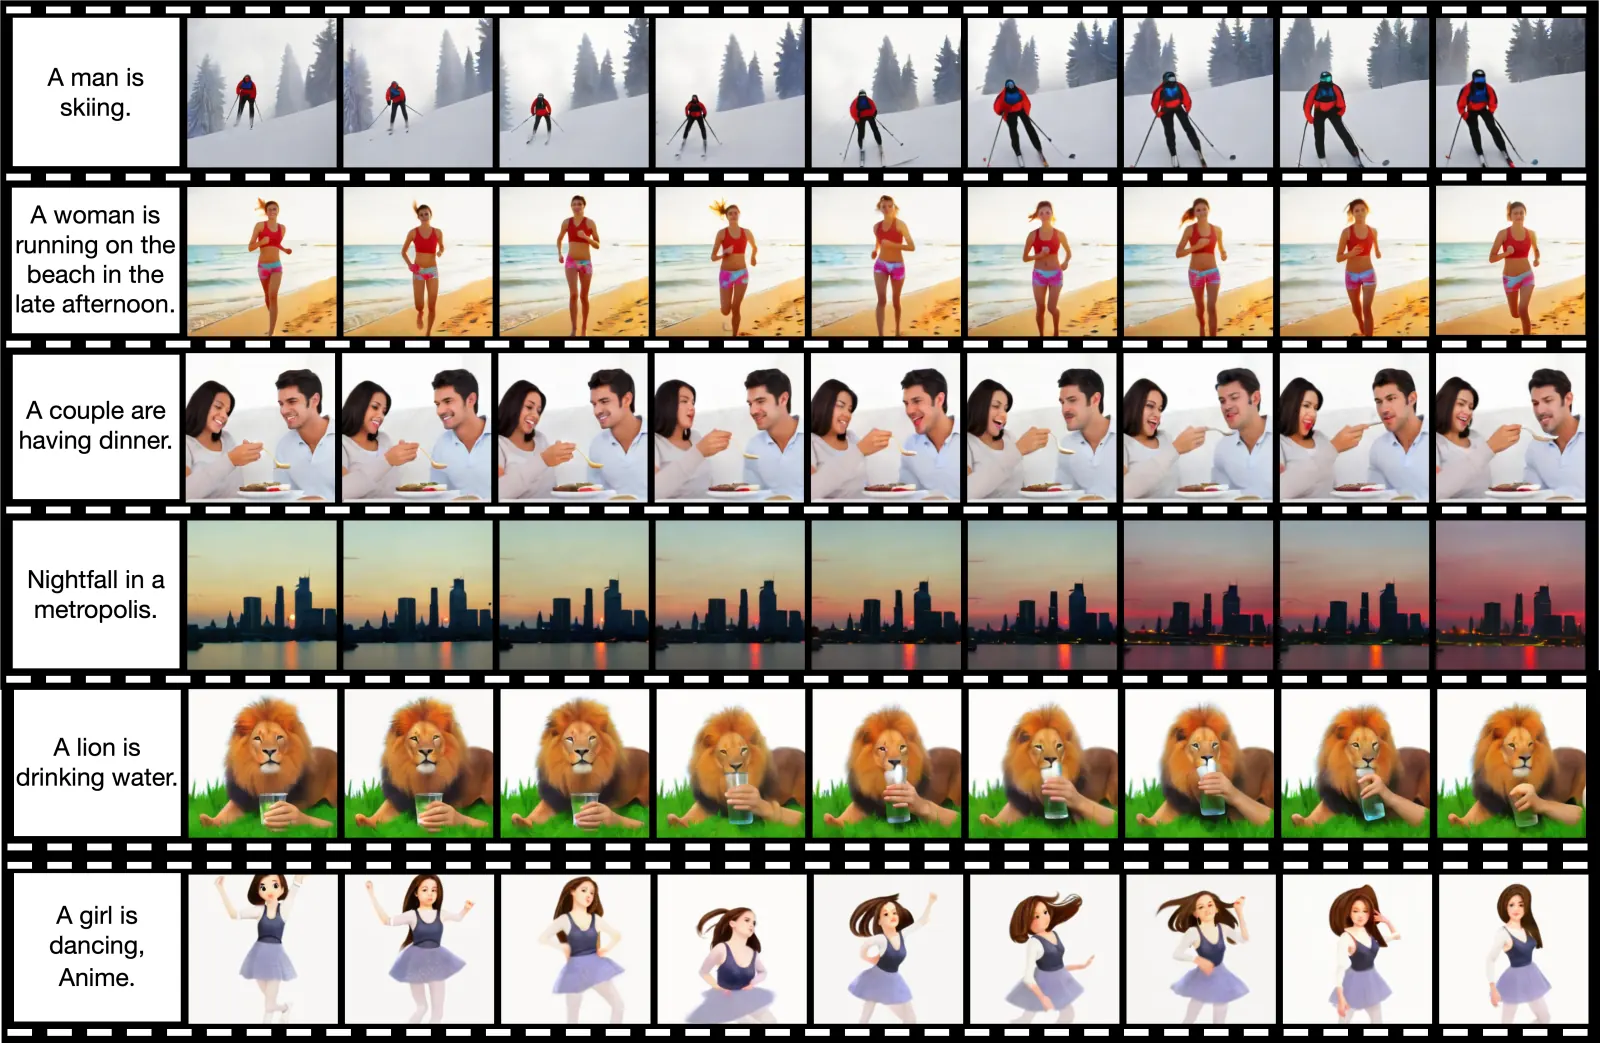
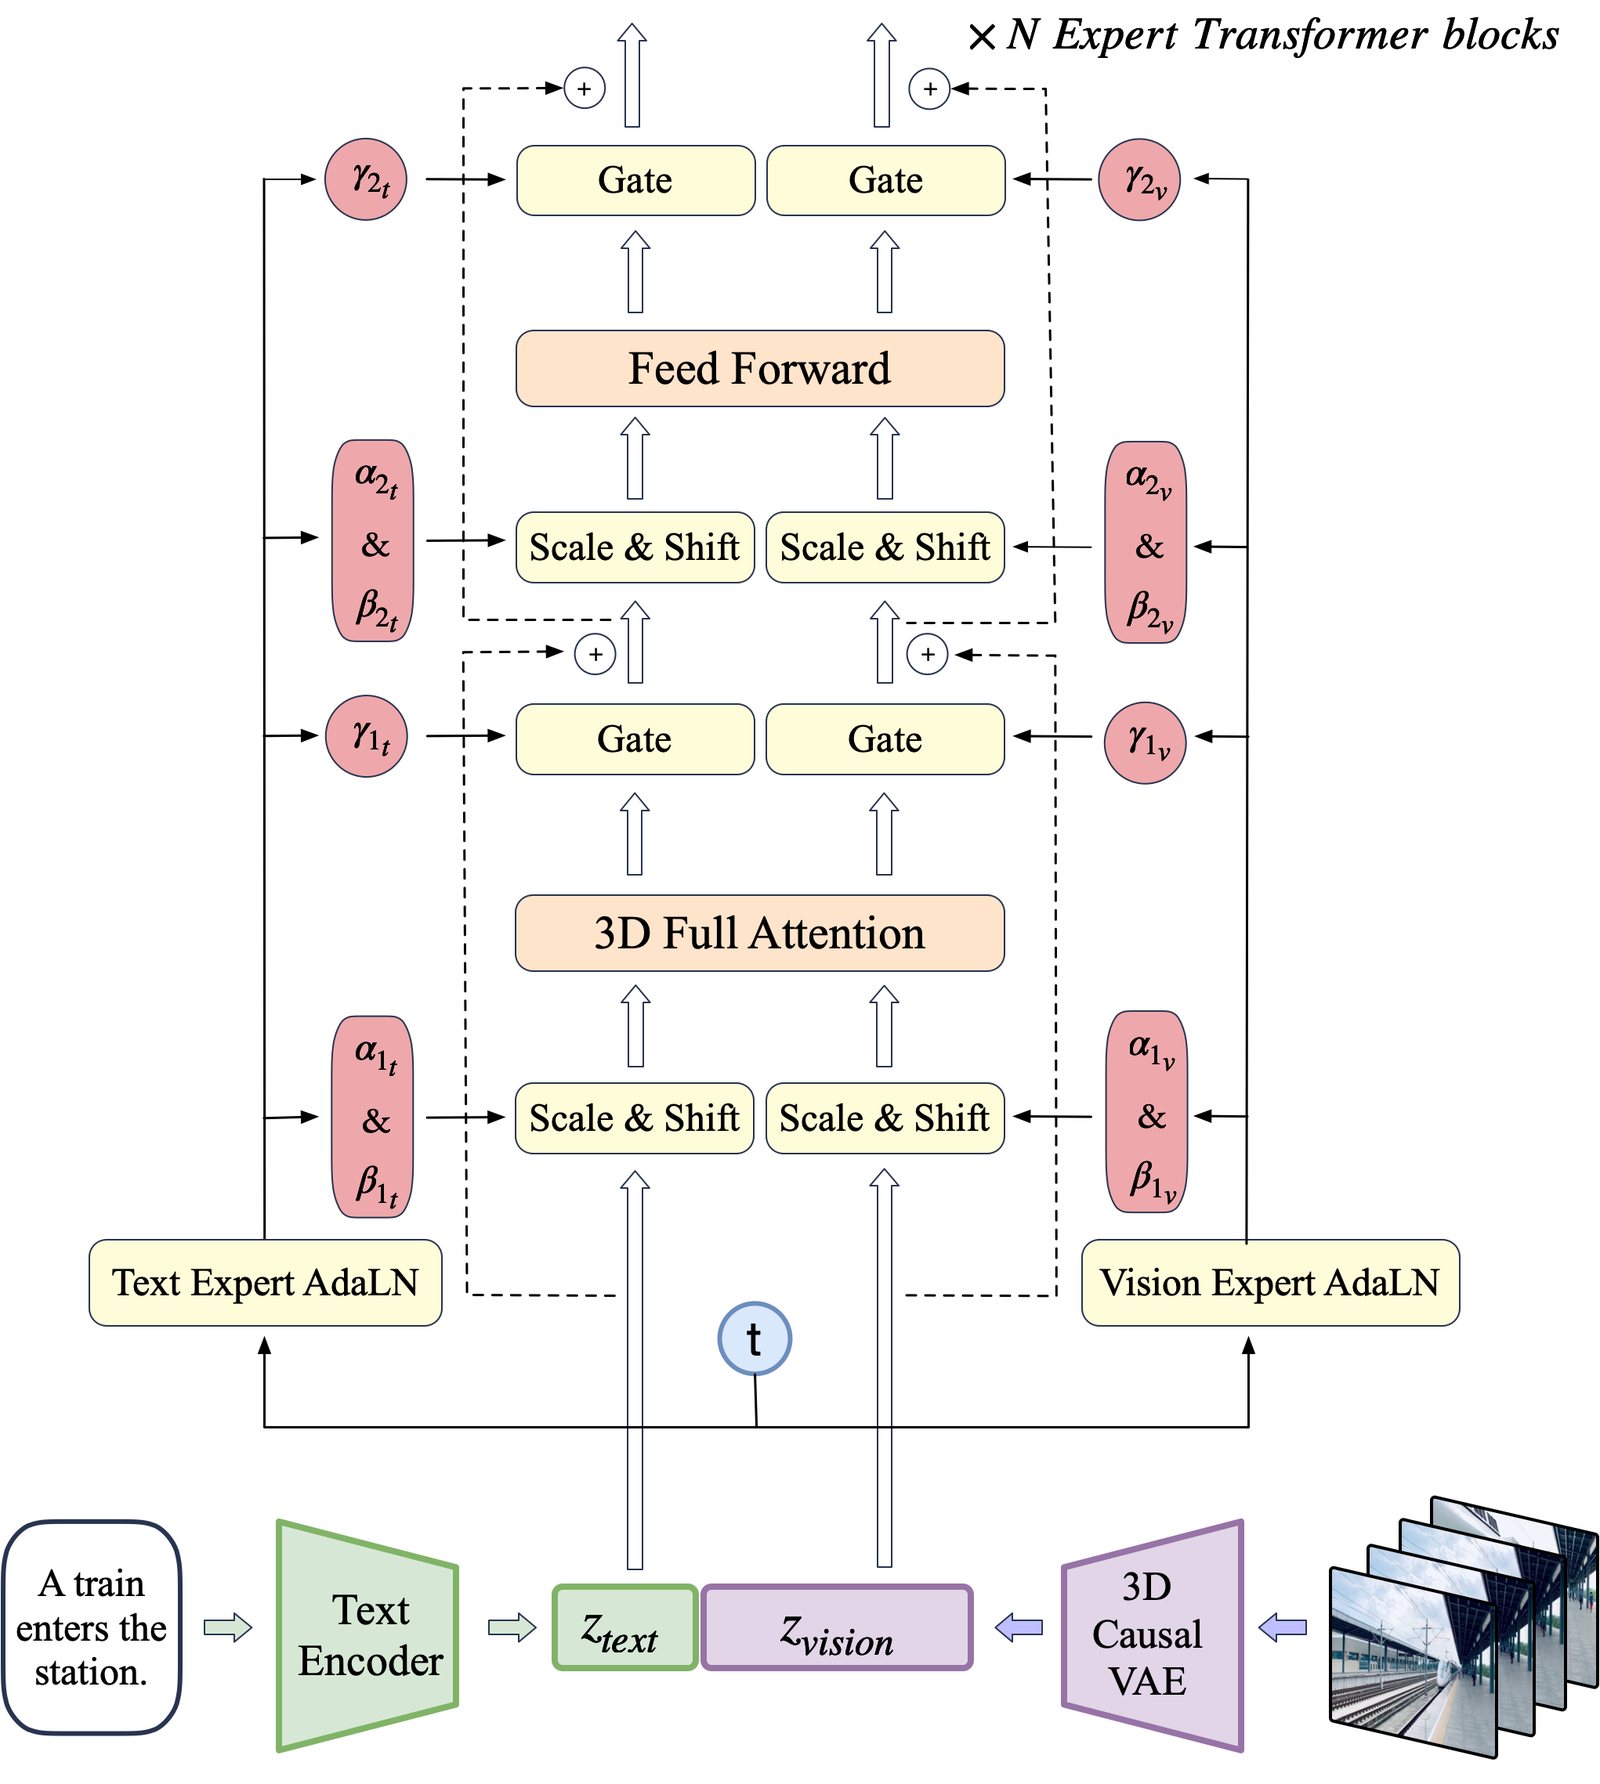
The generator is a diffusion Transformer over a 3D causal VAE latent, with an expert Transformer for text (and image) conditioning. T2V exposes num_inference_steps, num_frames, height, width, and fps; I2V adds guidance_scale. The I2V configuration follows the official-style 49-frame, 50-step Diffusers recipe. Weights load from THUDM Hugging Face repos (THUDM/CogVideoX-2b, CogVideoX-5b, CogVideoX-5b-I2V) or a local model_path. License metadata is Apache-2.0 on 2B and other on several 5B cards — review before commercial use. Routes are offline batch only: no streaming or interactive control.
Build your run
CogVideoX2bT2VPipelineworldfoundry.pipelines.cogvideox.pipeline_cogvideox_2b_t2vinteractive-videoworldfoundry.pipelineworldfoundry-eval run \
cogvideox-2b-t2v \
--pipeline.task-profile interactive-video \
--jsonVariants
- StatusVerified
cogvideox-2b-t2vtext-to-video
Runtime profile
cogvideox-2b-t2vPipeline binding
cogvideox-2b-t2v - StatusVerified
cogvideox-5b-t2vtext-to-video
Runtime profile
cogvideox-5b-t2vPipeline binding
cogvideox-5b-t2v - StatusVerified
cogvideox-5b-i2vimage-to-video
Runtime profile
cogvideox-5b-i2vPipeline binding
cogvideox-5b-i2v
What it is for
Use cogvideox-2b-t2v to iterate prompts, cogvideox-5b-t2v when you want the larger T2V card, and cogvideox-5b-i2v to animate a still. Required: prompt (T2V) or prompt + image (I2V). Optional: video. actions is seed. Default artifact on the 5B T2V card: cogvideox-5b-t2v.mp4. Compare clip quality on VBench and compositional prompts on T2V-CompBench. Those are the suites CogVideoX results are usually reported on — not ingested WorldFoundry ranks.
Runtime contract
CogVideoX5bT2VPipeline is the default 5B T2V class; 2B T2V and 5B I2V have sibling pipelines. The expert-conditioning design is the paper's main architectural claim versus a plain T5-conditioned U-Net — at run time that means text (and image) tokens steer the DiT in the 3D VAE latent. THUDM/CogVideoX1.5-5B and CogVideoX1.5-5B-I2V are listed as extra checkpoints, not as the verified Studio routes.
Running in WorldFoundry
Default launch is worldfoundry-eval run cogvideox-2b-t2v in worldfoundry-unified-cu128 (Python 3.11, CUDA 12.8). Swap the run id for cogvideox-5b-t2v or cogvideox-5b-i2v. Runner parity is verified; per-run visual QA stays outside the catalog.