
Bernini-R 1.3B
Bernini-R 1.3B from ByteDance: text-to-image and image-to-image; Runner parity pending; dedicated `worldfoundry-bernini-cu124`.
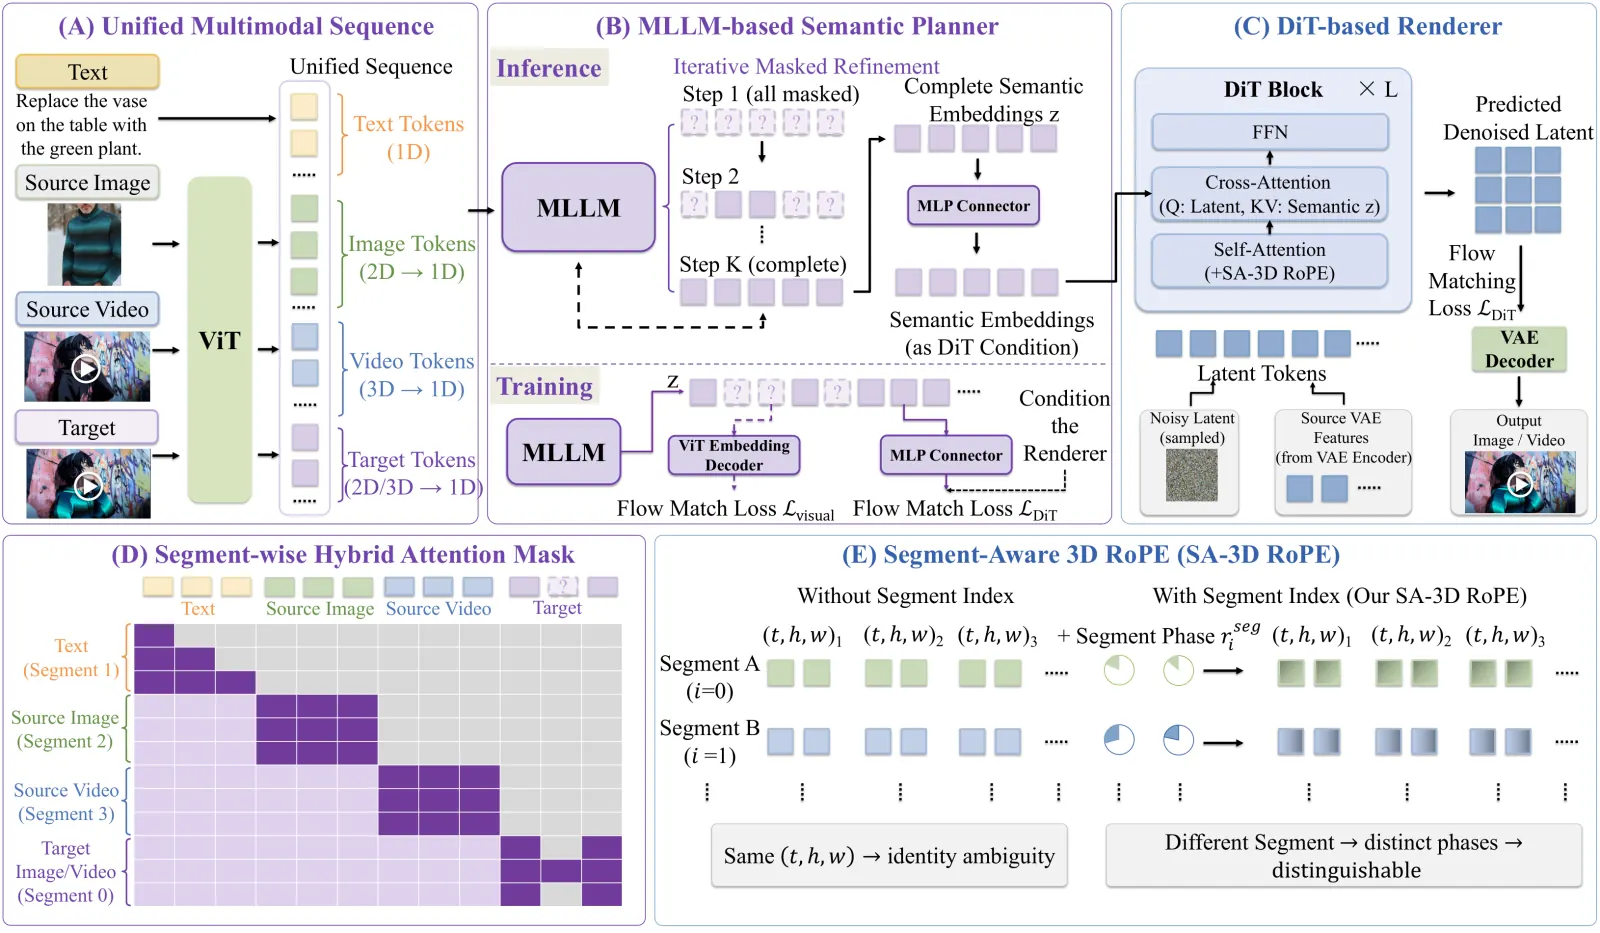
Bernini-R 1.3B is the small renderer-only member of ByteDance's Bernini family — a 1.3B rendering checkpoint fine-tuned from Wan2.1 1.3B, covering the same six task types as its larger siblings. It is the practical single-GPU way to try the Bernini task surface. WorldFoundry vendors the renderer inference in-tree and loads ByteDance/Bernini-R-1.3B-Diffusers.
The recorded paper is Bernini: Latent Semantic Planning for Video Diffusion (2026).
Project page: bernini-ai.github.io. Code: bytedance/Bernini.
This is not the planner+renderer Bernini card and not Bernini-R 14B.
Same paper: Bernini: Latent Semantic Planning for Video Diffusion. Project: bernini-ai.github.io. Weights: ByteDance/Bernini-R-1.3B-Diffusers (apache-2.0). GPU artifact parity is pending. Status: Runner parity pending.
Build your run
BerniniWorldFoundryPipelineworldfoundry.pipelines.bernini.pipeline_berniniworldfoundry.pipelineworldfoundry-eval run \
bernini-r-1.3b \
--pipeline.task-profile t2v \
--jsonWhat it is for
Pick bernini-r-1.3b when you want this family's text-to-video line in WorldFoundry: a prompt in, a generated clip out. Use it as the catalog T2V start rather than an editor or a world-model stepper.
The manifest explicitly records this as a renderer-only 1.3B checkpoint fine-tuned from the Wan2.1 1.3B diffusion-transformer backbone; the 7B planner stage of the full Bernini design is absent.
Catalog tasks include text-to-image, image-to-image, text-to-video, and video-to-video. Catalog aliases include bernini-r-1p3b and bernini-r-1.3b-diffusers. Documented modalities: text, image, and video in, image and video out.
Recorded evaluation entry points include VBench (Quick quality yardstick for the small renderer).
Runtime contract
Optional prompt, task_type, neg_prompt, num_frames, and height; artifacts generated_image, generated_video, and bernini-r-1.3b.mp4.
CLI task profiles: t2v, t2i, i2i, v2v, r2v, and rv2v. WorldFoundry binds BerniniWorldFoundryPipeline.
Family status: Runner parity pending.
Runner parity is pending_gpu_validation, but the small footprint makes this the recommended first stop in the Bernini family. Select tasks via task_type; the checkpoint is apache-2.0 and must be staged locally.
Official renderer inference is vendored in-tree; no external Bernini checkout is used.
Running in WorldFoundry
The catalog launch is worldfoundry-eval run bernini-r-1.3b --pipeline.task-profile t2v. The command builder above switches --pipeline.task-profile among recorded tasks and still emits worldfoundry-eval run.
It runs in the dedicated environment worldfoundry-bernini-cu124 (Python 3.11, CUDA 12.4, torch==2.5.1+cu124).
Recorded weight repositories include ByteDance/Bernini-R-1.3B-Diffusers and ByteDance/Bernini-R-1.3B-Diffusers. Prepare the environment and check local assets with bash scripts/inference/prepare_model_infer.sh bernini-r-1.3b. Add --download to fetch missing public checkpoints.
Recorded licenses include apache-2.0; status: Runner parity pending.



