Cosmos Predict 2.5
NVIDIA world foundation model: text/image/video in, world video out. Native 2B/14B recipes; gated checkpoints. 2B text-to-world is the verified route.
Cosmos Predict 2.5 is NVIDIA's world foundation model for physical AI: text, image, or video in, world video out. The paper is Cosmos Predict 2.5 (see also research.nvidia.com/labs/dir/cosmos-predict2.5). This catalog entry assembles the model from WorldFoundry's canonical denoiser, conditioner, scheduler, decoder, and loader roles without Diffusers.
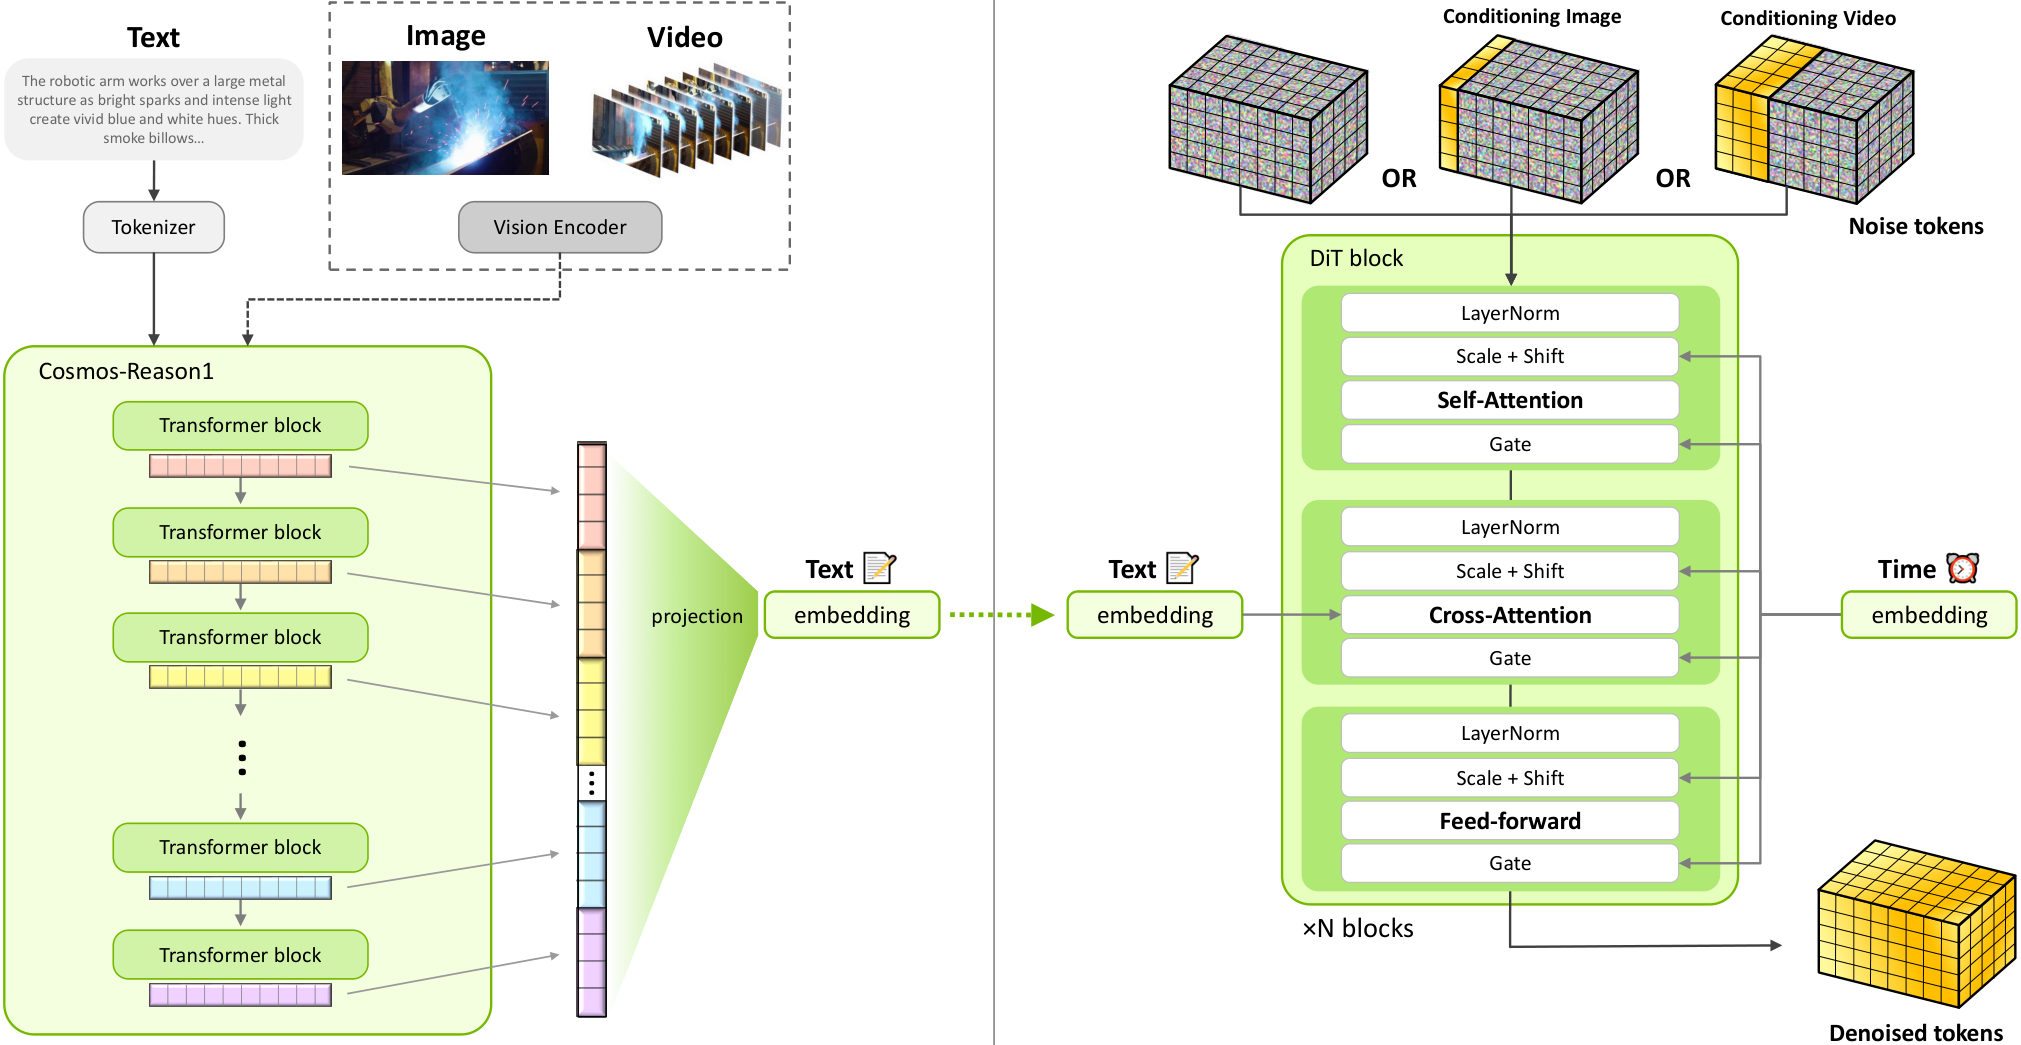
Two sizes are recorded: 2B and 14B. Structural checks in this repository match the official EMA transformer 569/569 (2B) and 729/729 (14B) tensors, Reason1 language weights 338/338, and the shared Wan VAE 194/194. Image/video conditioning and positive classifier-free guidance go through those shared runner contracts, not a model-private backend. NVIDIA access is gated; the recorded license is other:nvidia-open-model-license.
The verified WorldFoundry recipe is the 2B text-to-world route at 1280×704, 93 frames, 35 steps, 16 fps, flow-UniPC scheduling. The 14B route still needs end-to-end GPU output validation. Aliases cosmos-predict2p5 and cosmos-predict-2p5 resolve here.
Build your run
CosmosPredict2p5Pipelineworldfoundry.pipelines.cosmos.pipeline_cosmos_predict2p5text-to-world-validationworldfoundry.pipelineworldfoundry-eval run \
cosmos-predict-2.5-2b \
--pipeline.task-profile text-to-world-validation \
--jsonVariants
- StatusRunner parity pending
cosmos-predict-2.5-2bworld-generation
Runtime profile
cosmos-predict2.5-2bPipeline binding
cosmos-predict2.5-2b - StatusRunner parity pending
cosmos-predict-2.5-14bworld-generation
Runtime profile
cosmos-predict2.5-14bPipeline binding
cosmos-predict2.5-14b
What it is for
Predict future world video from text, a first frame, or a video prefix. Variants are cosmos-predict-2.5-2b and cosmos-predict-2.5-14b. Default artifact: cosmos-predict2.5-2b.mp4 (14B writes cosmos-predict2.5-14b.mp4). Score world-generation quality on WorldModelBench and physical plausibility on Physics-IQ. NVIDIA has since pointed new work at Cosmos 3; this page stays on the 2.5 card that is actually wired.
Runtime contract
CosmosPredict2p5Pipeline unifies text/image/video-to-world in one rectified-flow model with a Reason1 language conditioner and a shared Wan VAE. Prompt conditioning, positive guidance, image/video latent conditioning, and decoding all run through the shared native diffusion roles. Upstream NVIDIA cookbooks also mention robot / action-conditioned and policy variants (RoboCasa, LIBERO); those are not extra WorldFoundry variants on this card.
Running in WorldFoundry
The pipeline invokes the native recipes directly in worldfoundry-unified-cu128. Launch worldfoundry-eval run cosmos-predict-2.5-2b with --pipeline.task-profile text-to-world-validation. Stage nvidia/Cosmos-Predict2.5-2B (and 14B if you are testing that line) under NVIDIA's access rules. Structural tensor match is not the same as GPU output parity — 14B still pending.
The in-tree network is an inference-only PyTorch MinimalV1LVGDiT. It uses WorldFoundry attention and timestep primitives. NVIDIA EMA conversion and the Denoiser adapter live in worldfoundry/base_models/diffusion_model/models/denoisers/cosmos2p5.py, not in the network package. Architecture reference: nvidia-cosmos/cosmos-predict2.5 at a2c298b0a3df3778b973fe65e9e58877b292d8a7.
Minimal eval
The 2B text-to-world route is verified. Import WorldModelBench official-shaped results and read world_model_average. official-run needs WORLDFOUNDRY_WORLDMODELBENCH_JUDGE; full judge execution is not verified.