LingBot-Video
LingBot-Video from Robbyant (Ant Group): text-to-image and text-to-video; Runner parity pending.
LingBot-Video is Robbyant's video generation family, recorded for text-to-image, text-to-video, text+image-to-video, and video refinement. Two checkpoint lines are recorded: a dense 1.3B model and a MoE 30B-A3B model that ships with a refiner. WorldFoundry flattens the inference package in-tree under synthesis/visual_generation/lingbot_video and deliberately excludes the prompt rewriter, training, and benchmark sources.
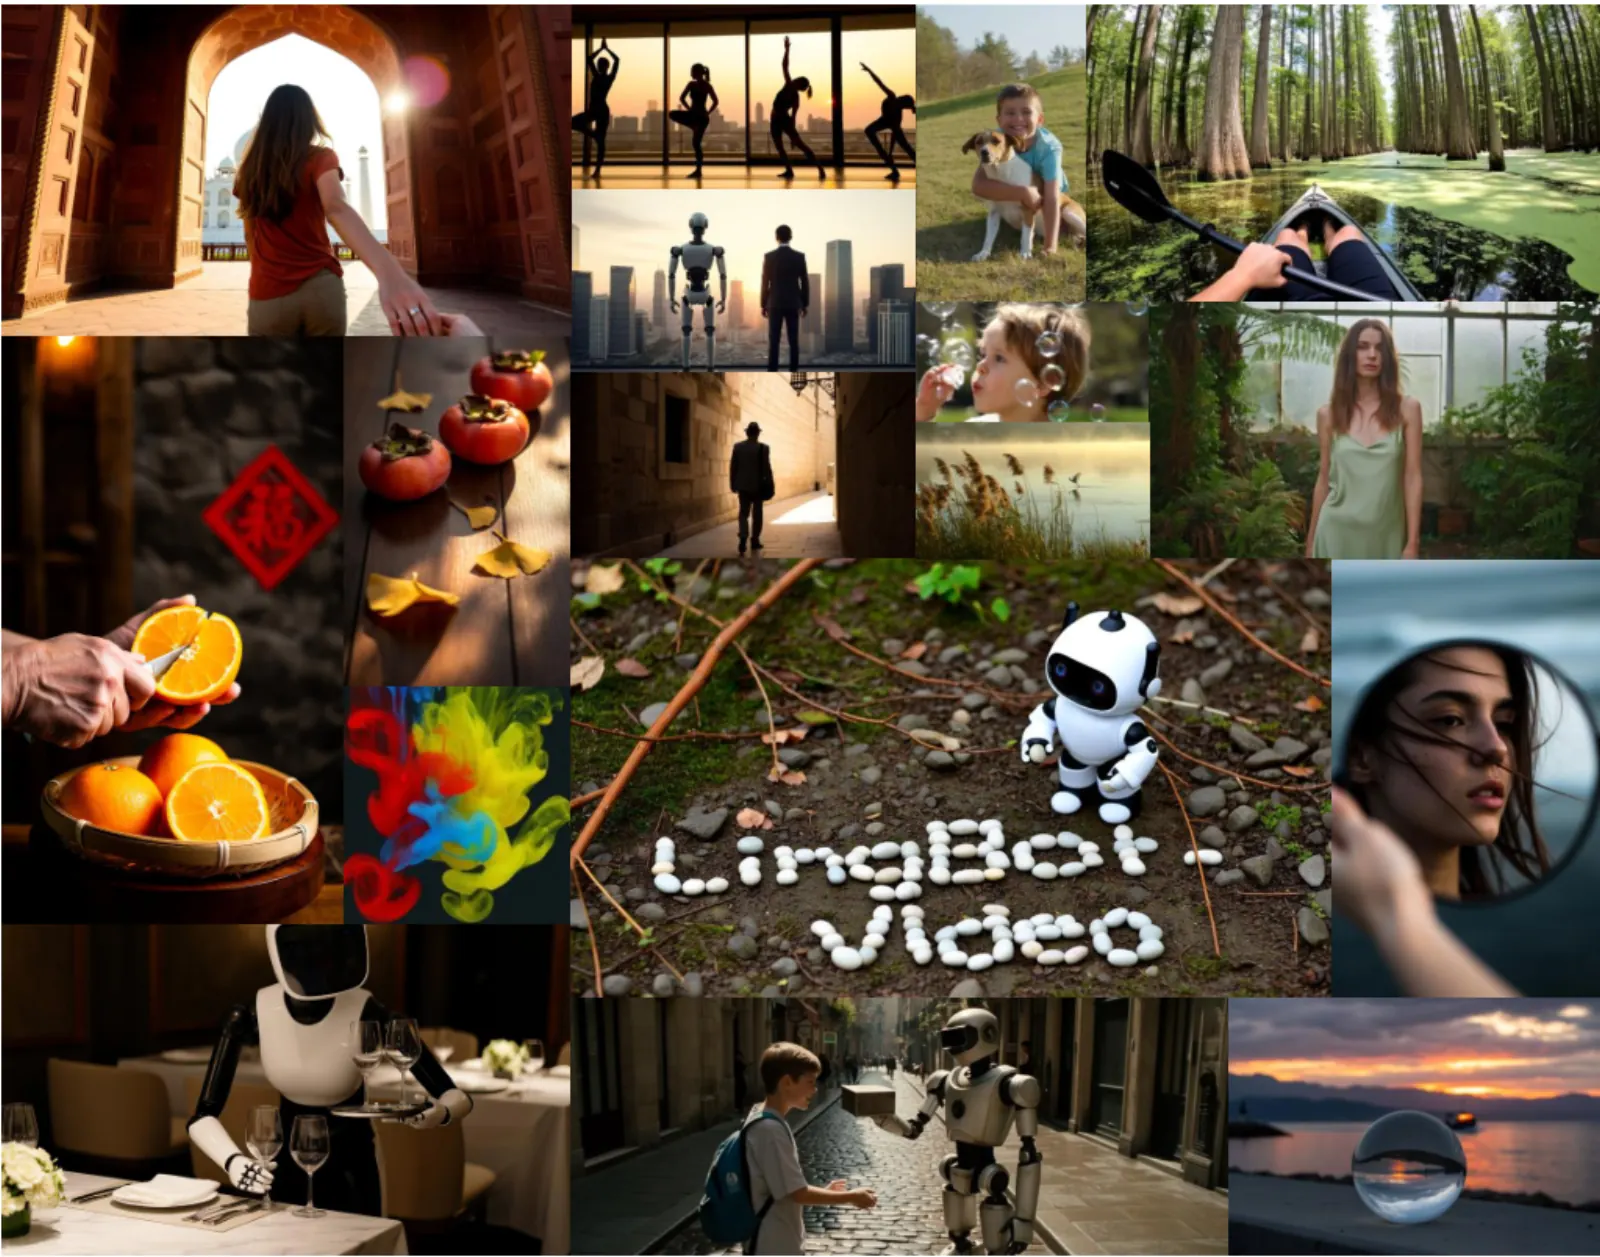
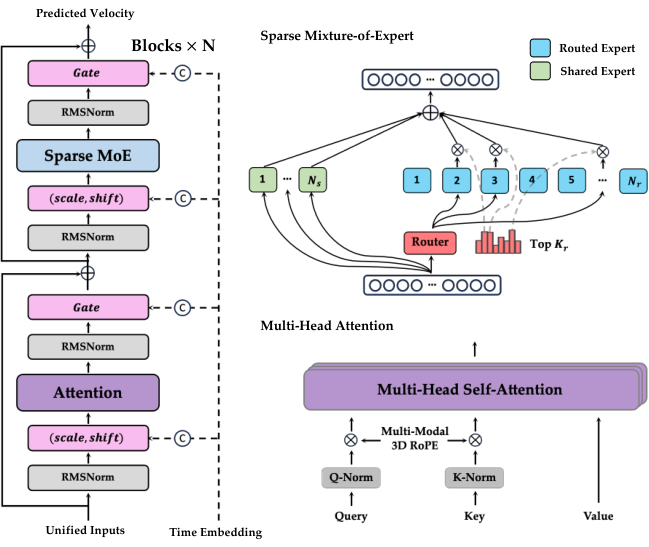
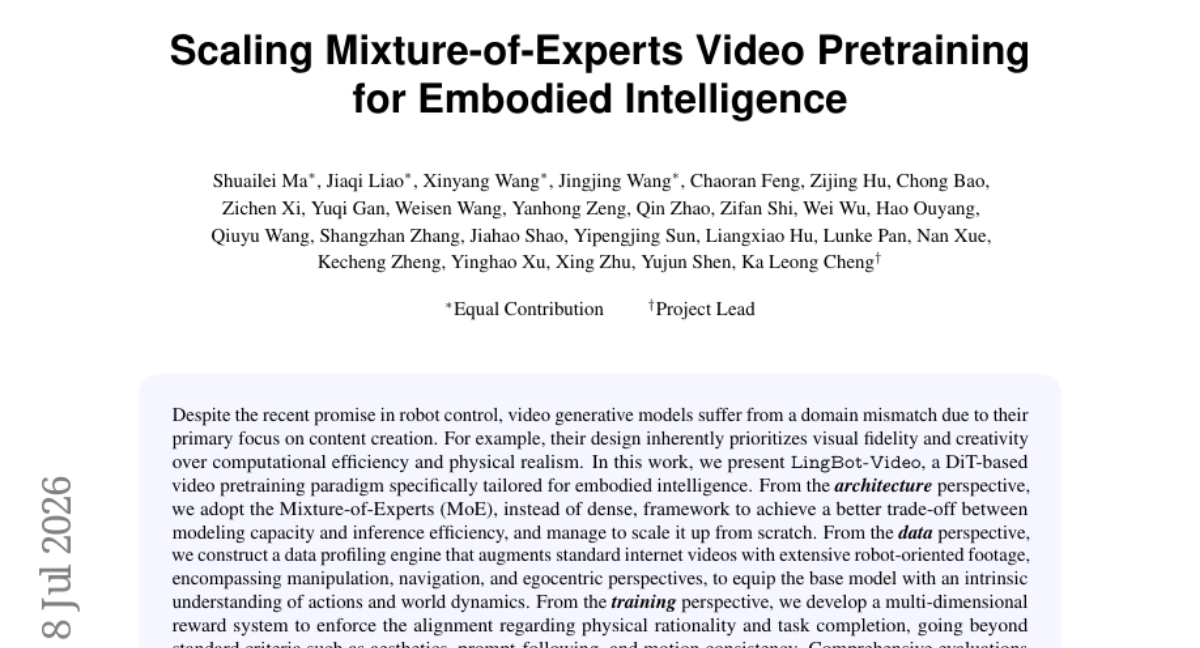
The recorded paper is arXiv 2607.07675.
Project page: technology.robbyant.com/lingbot-video. Code: Robbyant/lingbot-video.
Build your run
LingBotVideoGenerationPipelineworldfoundry.pipelines.lingbot_video.pipeline_lingbot_videoworldfoundry.pipelineworldfoundry-eval run \
lingbot-video \
--pipeline.task-profile t2v \
--jsonWhat it is for
Use lingbot-video for the family's joint T2V/I2V inference path. The catalog records both task profiles on this page.
The dense 1.3B and MoE 30B-A3B (3B active) checkpoints share the inference surface; the MoE line adds a refiner stage. The preserved code paths include direct Diffusers, optional SGLang, FSDP, context-parallel, and CFG-parallel execution. The upstream-recommended stack pins a dedicated Transformers 5 / Diffusers 0.39 environment. It is published by Robbyant (Ant Group).
Catalog tasks include text-to-image, text-to-video, text-image-to-video, and video-refinement. Catalog aliases include lingbot-video-dense and lingbot-video-moe. Documented modalities: text and image in, image and video out.
Recorded evaluation entry points include VBench (General T2V quality suite for both checkpoint lines).
Runtime contract
Optional prompt, prompt_json, negative_prompt, backend, and mode; artifacts generated_image, generated_video, and lingbot_video.mp4.
CLI task profiles: t2v, ti2v, and t2i. WorldFoundry binds LingBotVideoGenerationPipeline.
Family status: Runner parity pending.
Recorded t2v defaults: height=480, width=832, seed=42, fps=24 Recorded ti2v defaults: height=480, width=832, seed=42, fps=24.
Full checkpoint-backed artifact and visual parity are pending. The released Dense 1.3B checkpoint already has a recorded 121-frame, 832x480 quality-oriented Workspace artifact. Note one quirk from the profile: T2I produces an image even though the default artifact type is the T2V video route. Dense and MoE weights are external (apache-2.0) and never tracked in git.
Running in WorldFoundry
The catalog launch is worldfoundry-eval run lingbot-video --pipeline.task-profile t2v. The command builder above switches --pipeline.task-profile among recorded tasks and still emits worldfoundry-eval run.
It runs in the unified environment worldfoundry-unified-cu128 (Python 3.11, CUDA 12.8, torch==2.11.0+cu128).
Recorded weight repositories include robbyant/lingbot-video-dense-1.3b and robbyant/lingbot-video-moe-30b-a3b. Prepare the environment and check local assets with bash scripts/inference/prepare_model_infer.sh lingbot-video. Add --download to fetch missing public checkpoints.
Recorded licenses include apache-2.0; status: Runner parity pending.



