
LongCat-Video
LongCat-Video from Meituan (LongCat): text-to-video and image-to-video; Runner parity pending.
LongCat-Video is Meituan's open video generation model focused on long-video generation: text-to-video, image-to-video, and native video continuation in one model. WorldFoundry registers a model-specific pipeline that runs the vendored in-tree demo scripts — with the deliberate safety that nothing executes unless you pass execute=True. Weights are MIT-licensed at meituan-longcat/LongCat-Video.
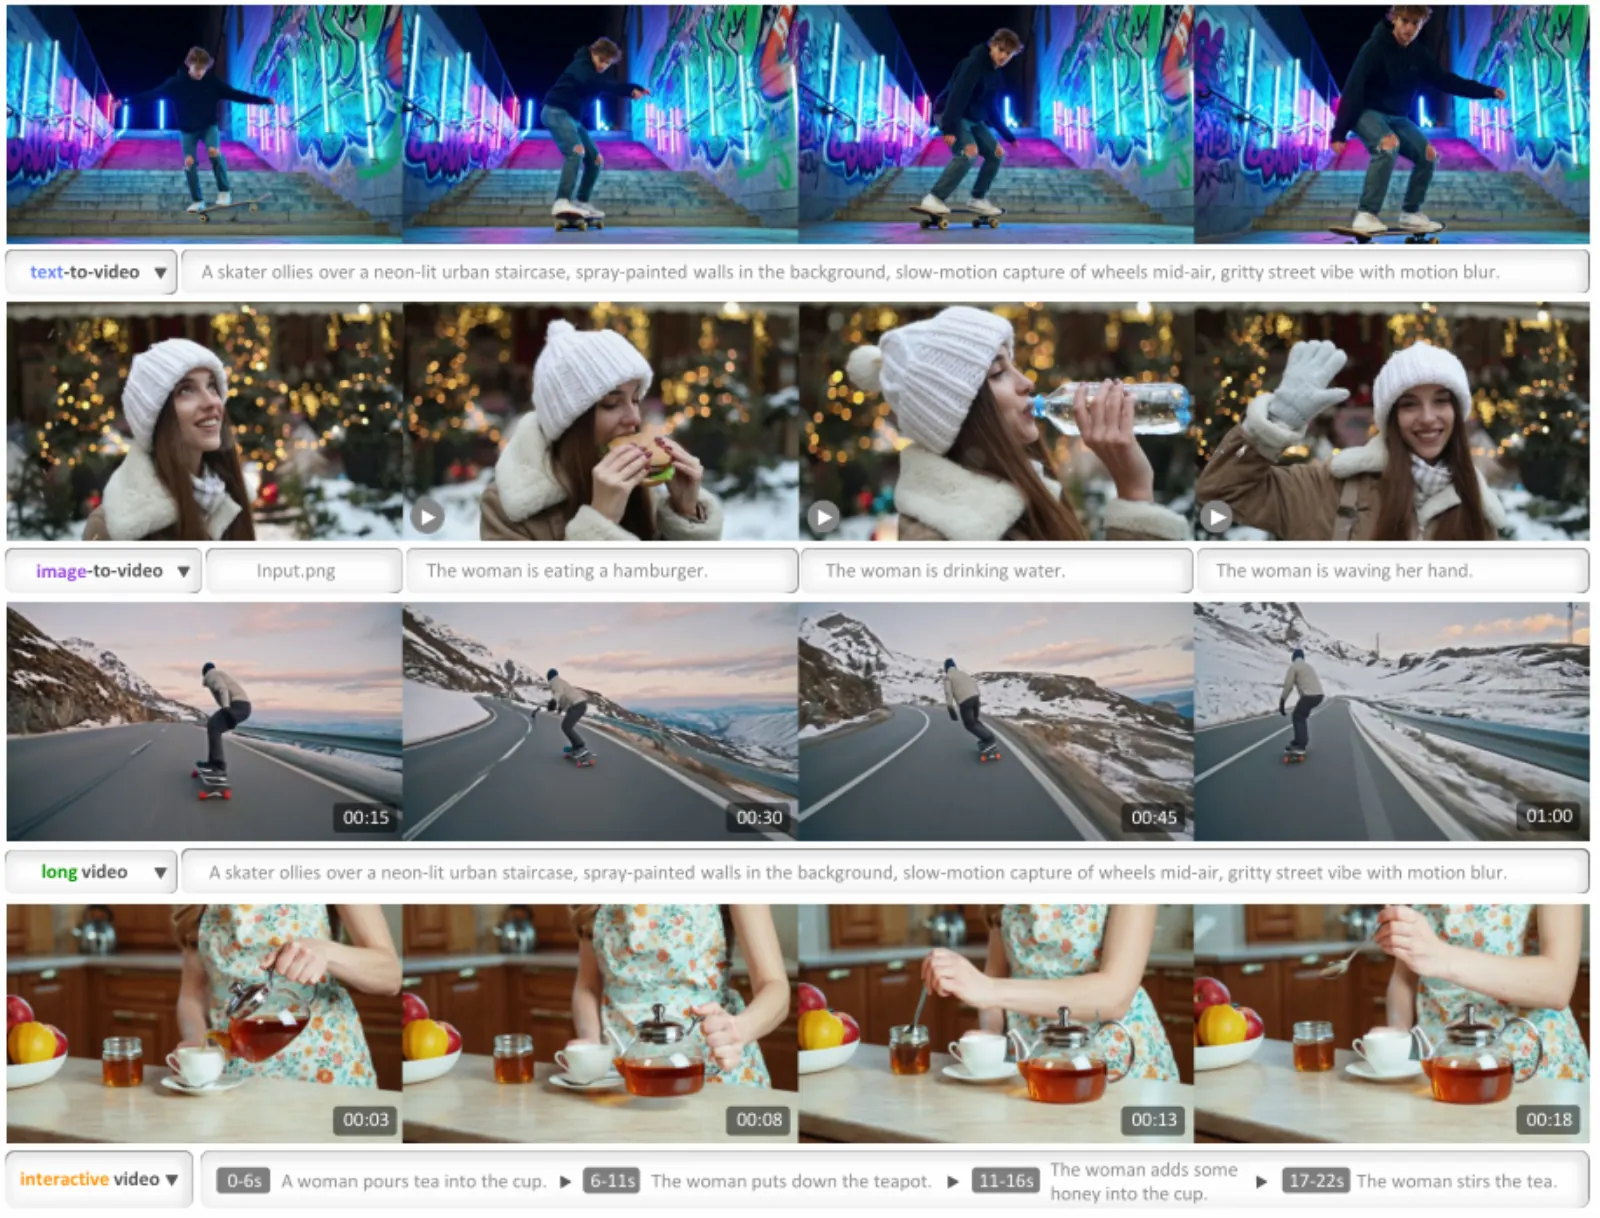
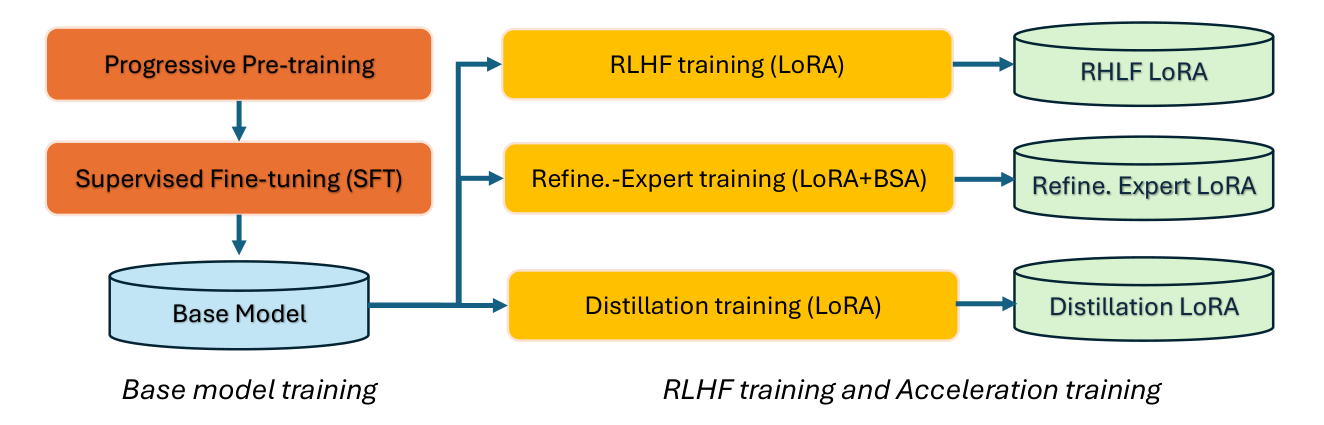
The recorded paper is arXiv 2510.22200.
Project page: meituan-longcat.github.io/LongCat-Video. Code: meituan-longcat/LongCat-Video.
Build your run
LongCatVideoPipelineworldfoundry.pipelines.longcat_video.pipeline_longcat_videoofficial-t2vworldfoundry.pipelineworldfoundry-eval run \
longcat-video \
--pipeline.task-profile official-t2v \
--jsonWhat it is for
longcat-video is the recorded text/image-to-video line. Use it when you want both prompt and still conditioning on the same catalog card.
Upstream positions LongCat-Video as a unified DiT-based generator where continuation is a first-class task, enabling minutes-long videos. This repository records the unified-environment route with local checkpoints and the image/prompt/video input contract; layer-level details are not recorded here. It is published by Meituan (LongCat).
Catalog tasks include text-to-video, image-to-video, video-continuation, and long-video-generation. Documented modalities: text and image in, video out.
Recorded evaluation entry points include VBench (Baseline T2V quality suite), ChronoMagic-Bench (Long-horizon generation matches LongCat's continuation focus).
Runtime contract
Optional prompt, negative_prompt, task_type, num_frames, and fps; artifacts generated_video and longcat_video.mp4.
CLI task profiles: official-t2v. WorldFoundry binds LongCatVideoPipeline.
Family status: Runner parity pending.
Recorded official-t2v defaults: negative_prompt=Bright tones, overexposed, static, blurred details, subtitles, style, works, paintings, images, static, overall gray, worst quality, low quality, JPEG compression residue, ugly, incomplete, extra fingers, poorly drawn hands, poorly drawn faces, deformed, disfigured, misshapen limbs, fused fingers, still picture, messy background, three legs, many people in the background, walking backwards, num_frames=93, fps=15, height=480, width=832, num_inference_steps=50.
Runner parity is pending — full official 93-frame / 50-step quality parity has not been recorded. Remember the execute=True gate: default calls fail fast by design. Stage the LongCat checkpoints locally before running.
WorldFoundry provides a vendored LongCat-Video runtime wrapper and fails fast when execution is not explicitly requested.
Running in WorldFoundry
Launch worldfoundry-eval run longcat-video --pipeline.task-profile official-t2v to sample the clip. The command builder above switches --pipeline.task-profile among recorded tasks and still emits worldfoundry-eval run.
It runs in the unified environment worldfoundry-unified-cu128 (Python 3.11, CUDA 12.8).
Recorded weight repositories include meituan-longcat/LongCat-Video. Prepare the environment and check local assets with bash scripts/inference/prepare_model_infer.sh longcat-video. Add --download to fetch missing public checkpoints.
Recorded licenses include mit; status: Runner parity pending.



