
MMAudio
MMAudio from Sony AI / University of Illinois Urbana-Champaign: text-to-audio and video-to-audio; Runner parity pending.
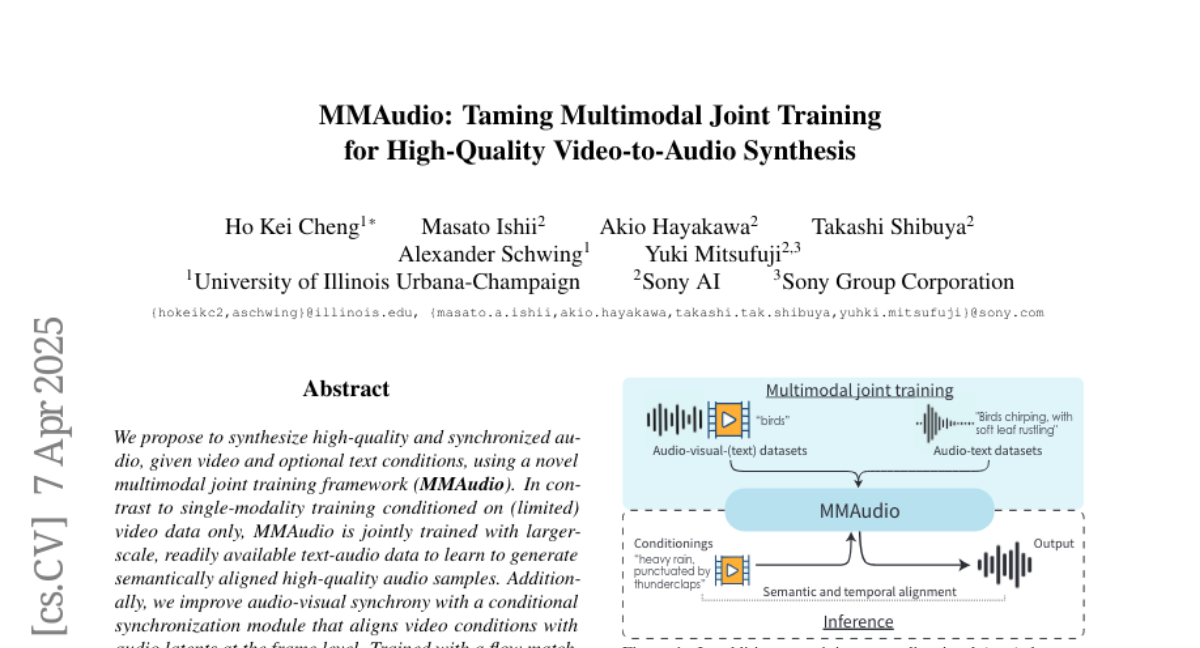
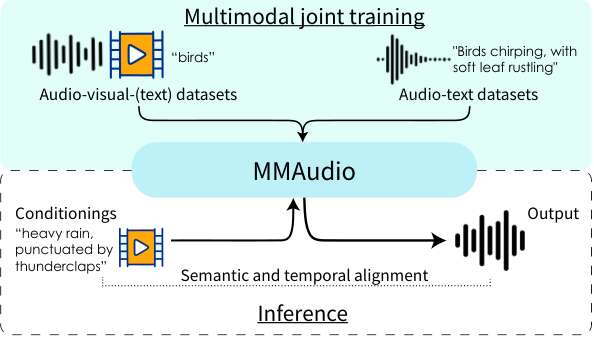
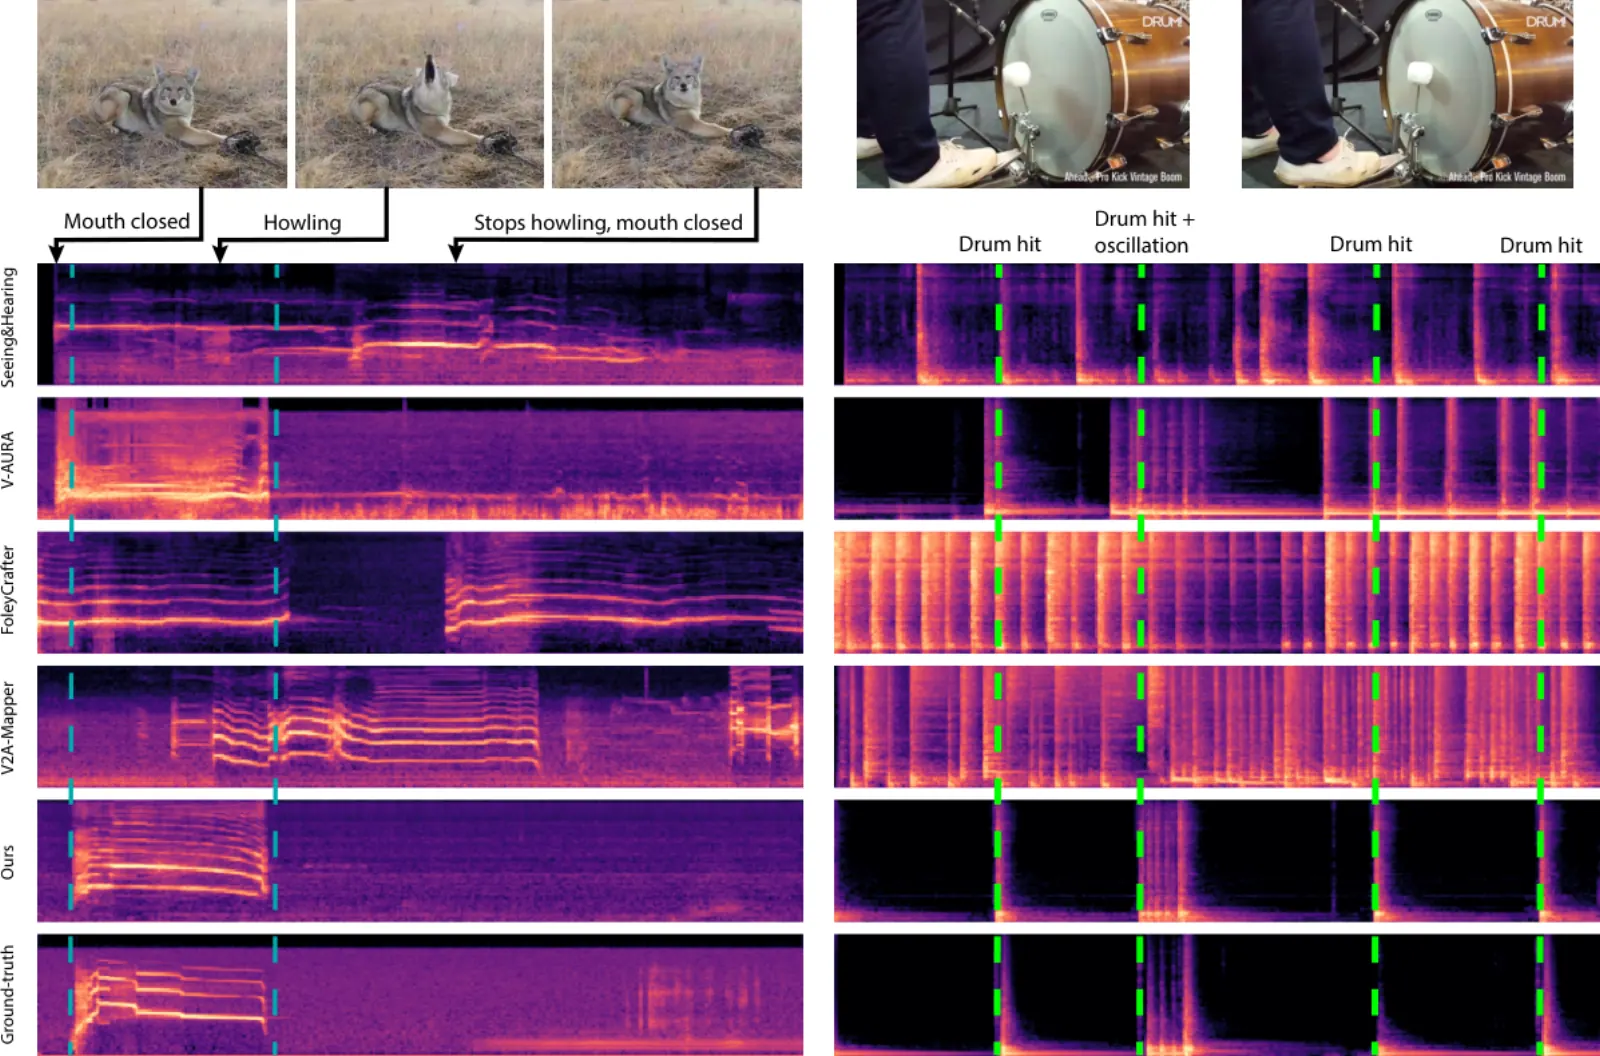
MMAudio generates soundtracks for silent video: given a video (and optionally a text prompt), it synthesizes audio that is semantically and temporally aligned with the visuals. In this catalog it is the companion tool for adding audio to clips produced by the video models — its artifact type is generated_audio, not video.
The recorded paper is arXiv 2412.15322.
Project page: hkchengrex.github.io/MMAudio. Code: hkchengrex/MMAudio.
Build your run
MMAudioPipelineworldfoundry.pipelines.video_official.pipeline_official_videointeractive-videoworldfoundry.pipelineworldfoundry-eval run \
mmaudio \
--pipeline.task-profile interactive-video \
--jsonWhat it is for
mmaudio is the recorded audio line. Start here to write audio from the documented inputs.
MMAudio is a multimodal joint-training flow-matching model that conditions audio generation on video frames and text (per its publication). This repository records the prompt/video input contract and the generated_audio artifact; model size options and internals are not recorded here. It is published by Sony AI / University of Illinois Urbana-Champaign.
Catalog tasks include text-to-audio, video-to-audio, and audio-generation. Catalog aliases include hkchengrex/MMAudio.
Runtime contract
Optional prompt, negative_prompt, input_path, frames, and fps; artifacts mmaudio.wav.
CLI task profiles: interactive-video. WorldFoundry binds MMAudioPipeline.
Family status: Runner parity pending.
Typical workflow: generate video with any T2V/I2V entry, then feed the clip to MMAudio for a soundtrack.
WorldFoundry route is complete; missing checkpoint/assets are reported at runtime.
Running in WorldFoundry
Launch worldfoundry-eval run mmaudio --pipeline.task-profile interactive-video to write audio. The command builder above switches --pipeline.task-profile among recorded tasks and still emits worldfoundry-eval run.
It runs in the unified environment worldfoundry-unified-cu128 (Python 3.11, CUDA 12.8).
Recorded weight repositories include hkchengrex/MMAudio. Prepare the environment and check local assets with bash scripts/inference/prepare_model_infer.sh mmaudio. Add --download to fetch missing public checkpoints.
Status: Runner parity pending.



