ModelScopeT2V
ModelScopeT2V from Alibaba (DAMO Academy / ModelScope): text-to-video; Runner parity pending.
ModelScopeT2V is Alibaba DAMO Academy's original open text-to-video diffusion model — the 1.7B model that kicked off much of the open T2V ecosystem (ZeroScope in this catalog is a fine-tune of it). The WorldFoundry route is complete and reports missing checkpoints at runtime. It is kept mainly as a historical baseline.
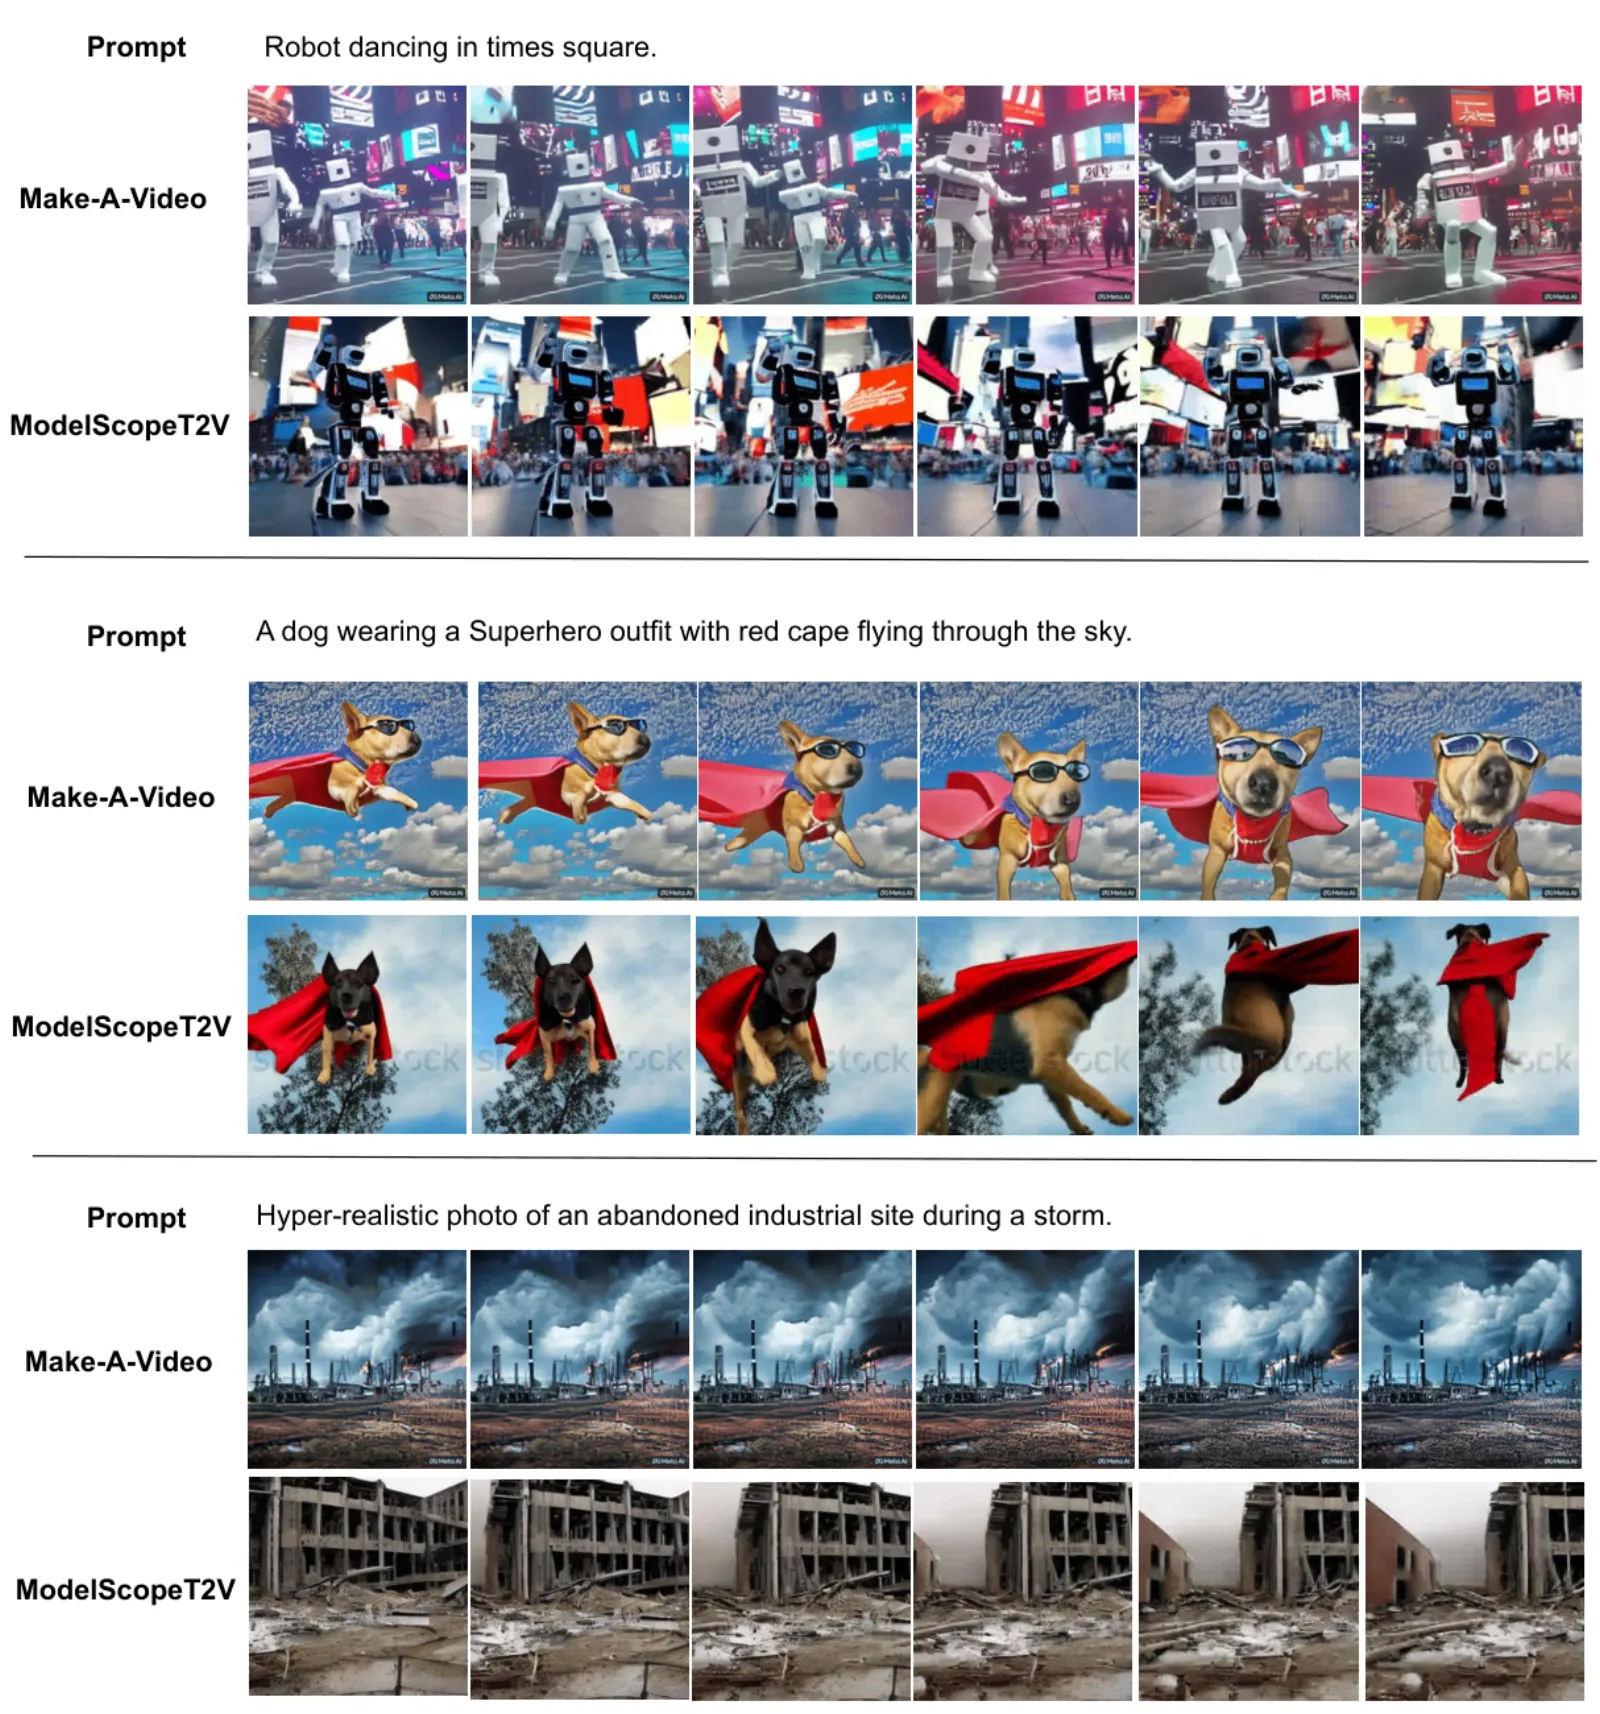
The recorded paper is arXiv 2308.06571.
Project page: modelscope.cn. Code: modelscope/modelscope.
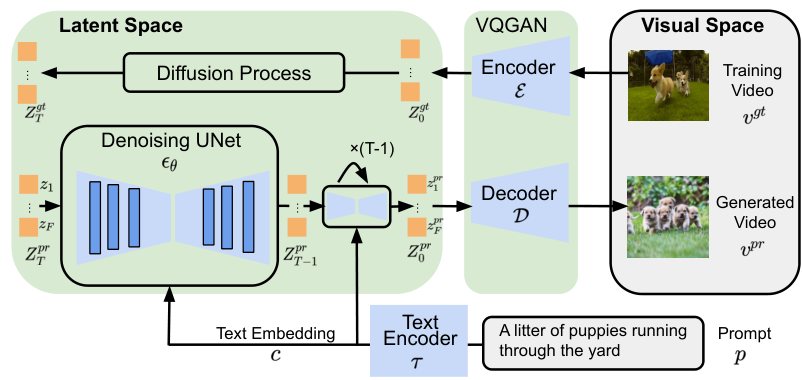
Architecturally it is a latent video U-Net: temporal attention is inserted into a text-to-image diffusion backbone so a prompt becomes a short, low-resolution clip. That is why later DiT families (Wan, CogVideoX, HunyuanVideo) superseded it on quality and temporal consistency. The Hugging Face card is ali-vilab/modelscope-damo-text-to-video-synthesis. Recorded license is CC-BY-NC-4.0 — the manifest says not to treat it as unrestricted open source.
Build your run
ModelScopeT2VPipelineworldfoundry.pipelines.video_official.pipeline_official_videointeractive-videoworldfoundry.pipelineworldfoundry-eval run \
modelscope-t2v \
--pipeline.task-profile interactive-video \
--jsonWhat it is for
modelscope-t2v is the recorded prompt-to-video route — not image editing and not a policy. Start here when the job is a clip from text.
A U-Net latent video diffusion model with temporal attention layers inserted into a text-to-image backbone (per the upstream publication). This repository records the prompt-only input contract and generated_video artifact. It is published by Alibaba (DAMO Academy / ModelScope).
Catalog tasks include text-to-video. Documented modalities: text in, video out.
Recorded evaluation entry points include FETV (Fine-grained T2V evaluation suited to legacy baselines).
Reproduce a 2023-era open T2V baseline: required prompt in, modelscope-t2v.mp4 out through ModelScopeT2VPipeline. The wired controls are text prompt, fps, and seed. Use it to compare against later entries or to explain ZeroScope's parent. For research-quality or production T2V, use the DiT cards. FETV is the fine-grained suite this generation of models is usually discussed on.
Runtime contract
Optional prompt, negative_prompt, frames, fps, and height; artifacts modelscope-t2v.mp4.
CLI task profiles: interactive-video. WorldFoundry binds ModelScopeT2VPipeline.
Family status: Runner parity pending.
The recorded license is non-commercial per HF cardData — the manifest says explicitly not to treat it as unrestricted open source. Use it for research comparisons only; for production-quality T2V use the DiT-based entries.
Checkpoint license is non-commercial per HF cardData; do not treat as unrestricted open source.
Running in WorldFoundry
Launch worldfoundry-eval run modelscope-t2v --pipeline.task-profile interactive-video to sample the clip. The command builder above switches --pipeline.task-profile among recorded tasks and still emits worldfoundry-eval run.
It runs in the unified environment worldfoundry-unified-cu128 (Python 3.11, CUDA 12.8).
Recorded weight repositories include ali-vilab/modelscope-damo-text-to-video-synthesis and ali-vilab/modelscope-damo-text-to-video-synthesis. Prepare the environment and check local assets with bash scripts/inference/prepare_model_infer.sh modelscope-t2v. Add --download to fetch missing public checkpoints.
Recorded licenses include cc-by-nc-4.0; status: Runner parity pending.



