Open-Sora-Plan
PKU Yuan Group Open-Sora-Plan v1.3 T2V. Studio demo passed at 640×352 / 93 frames / 18 fps / 100 Euler-ancestral steps; runner parity is still unrecorded.
Open-Sora-Plan is Peking University Yuan Group's open text-to-video project — independent of HPC-AI Tech's Open-Sora despite the similar name. Hugging Face weights ship under LanguageBind; GitHub is PKU-YuanGroup. This card is the v1.3.0 GPU route. WorldFoundry bridges the in-tree official sampler (OpenSoraPlanPipeline) and reports missing checkpoints at runtime.
The paper is Open-Sora Plan: Open-Source Large Video Generation Model. Code: PKU-YuanGroup/Open-Sora-Plan. Weights: LanguageBind/Open-Sora-Plan-v1.3.0. paper.png is the title thumb only.
Build your run
OpenSoraPlanPipelineworldfoundry.pipelines.video_official.pipeline_official_videointeractive-videoworldfoundry.pipelineworldfoundry-eval run \
open-sora-plan \
--pipeline.task-profile interactive-video \
--jsonWhat it is for
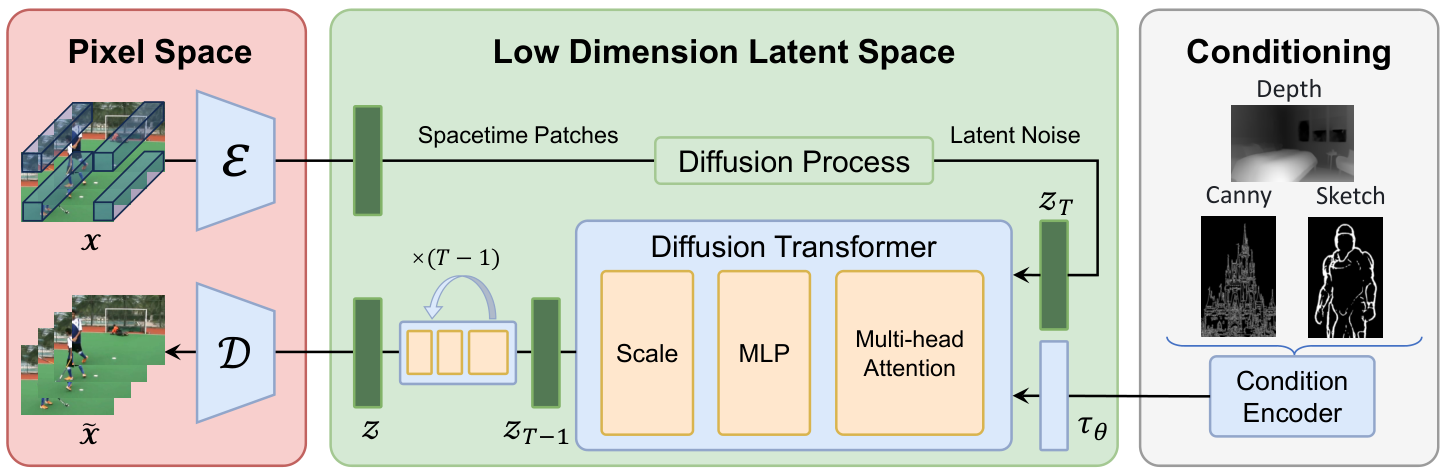
Prompt-only T2V: required prompt, artifact open-sora-plan.mp4. There is no local I2V or V2V on this card (the paper discusses condition controllers; they are not this binding). Use v1.3.0 for GPU. LanguageBind also published v1.0.0–v1.2.0 and a v1.5.0 line aimed at Ascend / MindSpeed — that last one is not the validated WorldFoundry GPU path. Compare open T2V quality on VBench without treating it as an ingested rank.
Inference
Studio/API validation replayed the official v1.3 GPU script (sample_t2v_v1_3.sh / Tokyo street):
| Knob | Recorded value |
|---|---|
| Size | 640×352 (any93x640x640; decodes as 93 non-empty 640×352 frames) |
| Frames | 93 |
| FPS | 18 |
| Sampler | EulerAncestralDiscrete, v_prediction, --rescale_betas_zero_snr |
| Steps | 100 |
| Guidance | 7.5 |
| Seed | 1234 |
| Text encoder | google/mt5-xxl (max_sequence_length=512) |
| VAE | WF-VAE WFVAEModel_D8_4x8x8 under the checkpoint vae/ subdir |
Visual QA on that prompt is recorded. Catalog runner evidence is still not recorded. The wrapper default is nproc_per_node=1 for a single prompt; the official multi-prompt script uses torchrun --nproc_per_node=8. Catalog VRAM is unset.
Running in WorldFoundry
worldfoundry-eval run open-sora-plan in worldfoundry-unified-cu128 (Python 3.11, CUDA 12.8). Stage LanguageBind/Open-Sora-Plan-v1.3.0 and google/mt5-xxl. scripts/inference/prepare_model_infer.sh places the ~50 GB text encoder once so it is not copied into both WORLDFOUNDRY_CKPT_DIR and WORLDFOUNDRY_HFD_ROOT. License on the recorded v1.3 card is MIT. Status: Runner parity pending.



