Qwen2.5-Omni
Alibaba Qwen omni-modal 7B: text, image, audio, and video in. WorldFoundry records the text-response path — prompt plus optional image or video, JSON out.
Qwen2.5-Omni is Alibaba Qwen's end-to-end omni-modal model. The official paper is Qwen2.5-Omni Technical Report (arXiv 2503.20215). Code and cards live at QwenLM/Qwen2.5-Omni and Qwen/Qwen2.5-Omni-7B. In this catalog it is an understanding / reasoning entry — not a video generator — with model_response artifacts. Aliases qwen2p5-omni, qwen2p5_omni, and Qwen/Qwen2.5-Omni-7B resolve here.
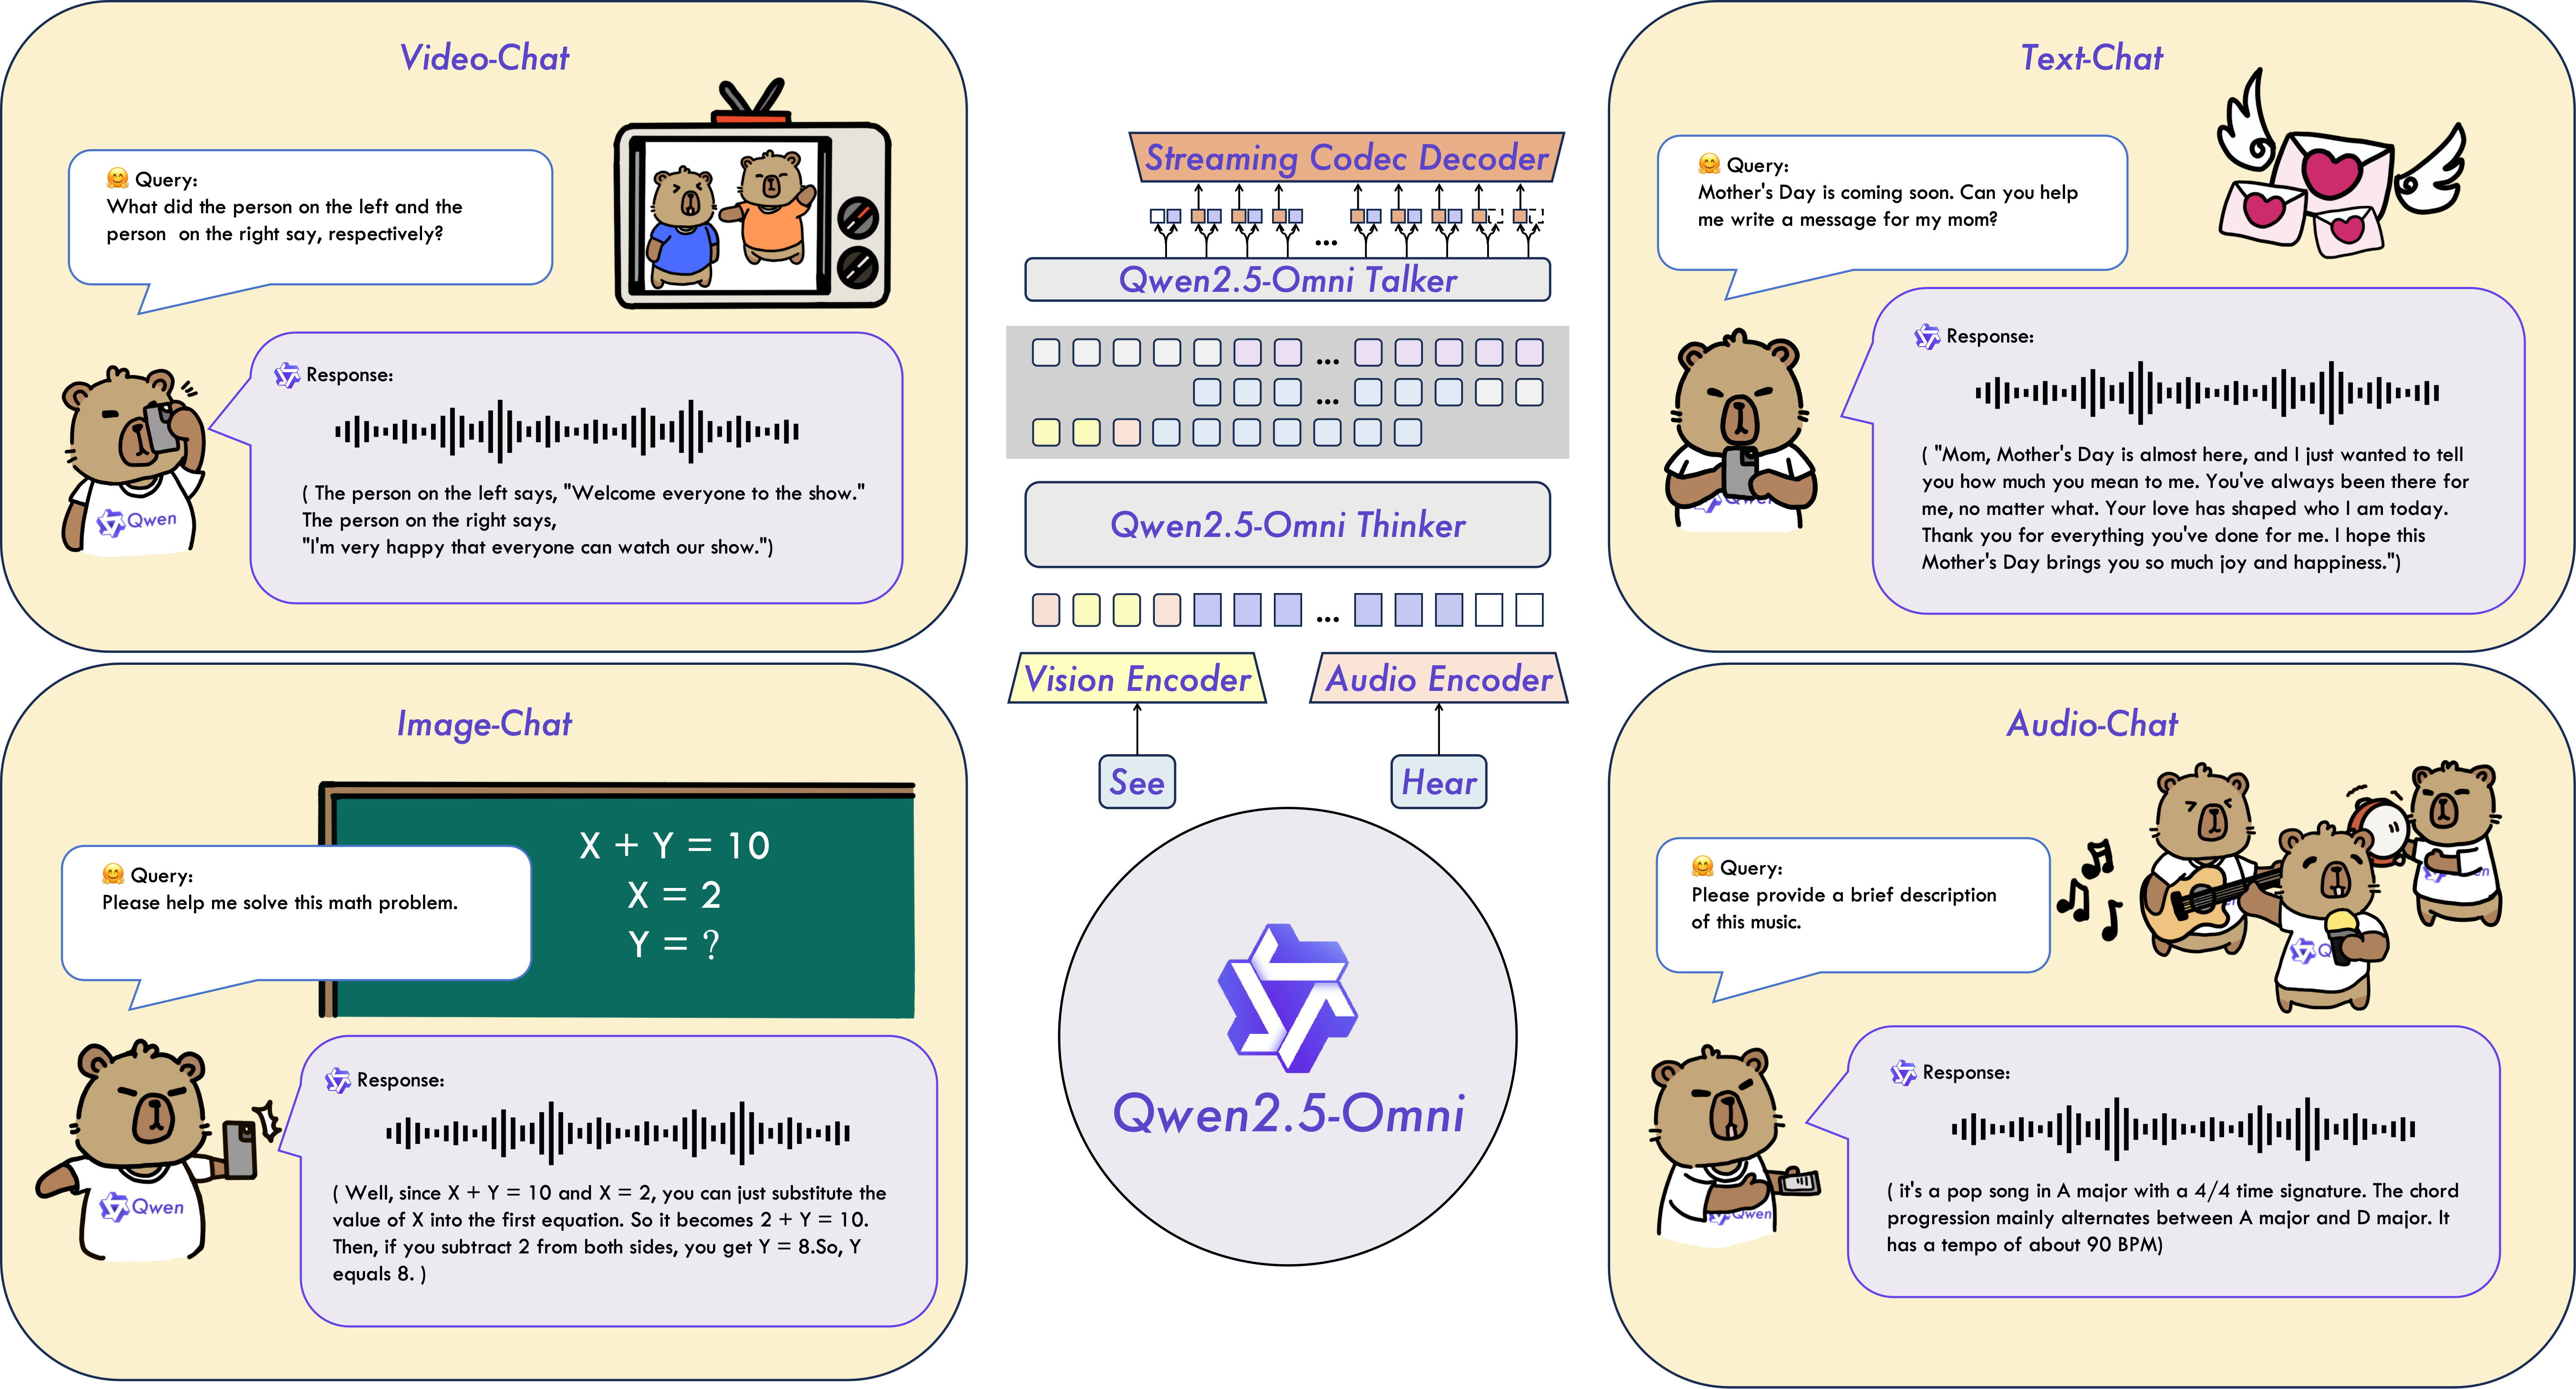
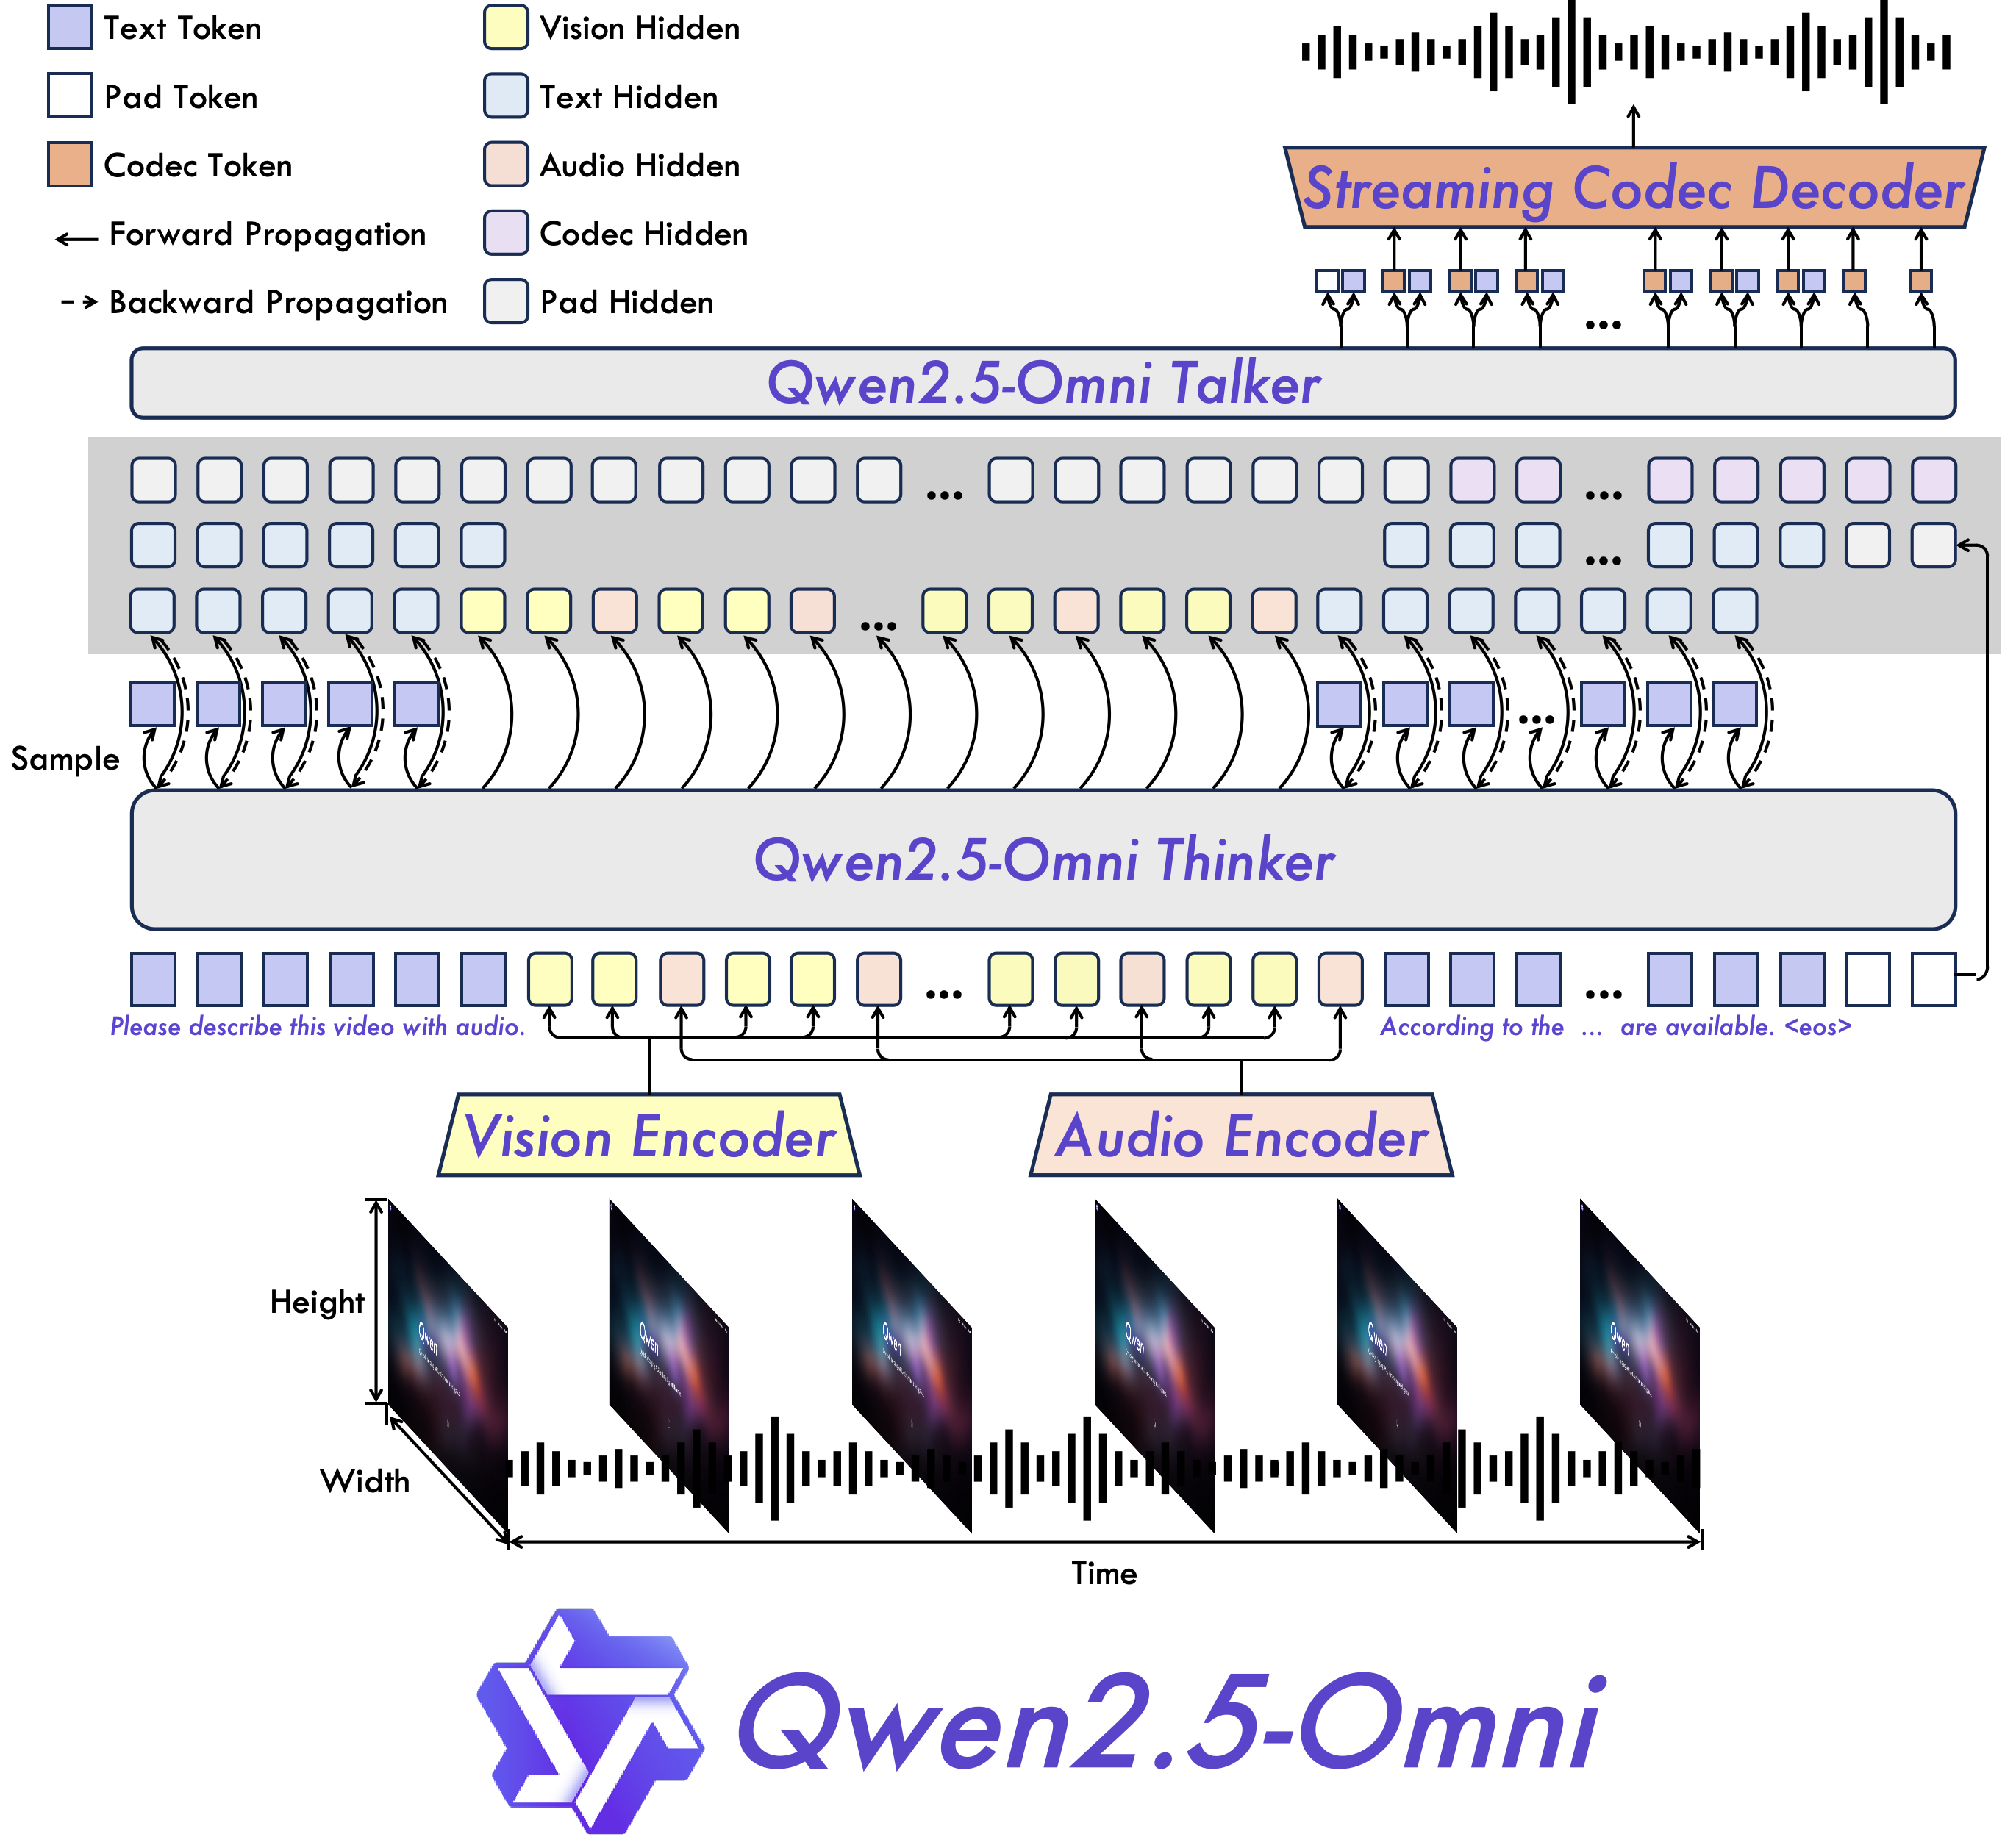
The paper describes a Thinker-Talker stack with TMRoPE (time-aligned multimodal RoPE) so audio and video share a clock. Officially the model perceives text, images, audio, and video and can stream text and speech together. Audio frames in TMRoPE are aligned at 40 ms per temporal id. WorldFoundry only wires the text-response path: required prompt, optional image / video, artifact qwen2.5-omni.json. The recorded weight is the 7B release. This catalog does not record a license; the Hugging Face card metadata is other — review it before production use.
Build your run
Qwen25OmniPipelineworldfoundry.pipelines.video_official.pipeline_official_videoworldfoundry.pipelineworldfoundry-eval run \
qwen2.5-omni \
--pipeline.task-profile multimodal-reasoning \
--jsonWhat it is for
Caption, interrogate, or QA stills and clips produced by other catalog entries. Recorded task profiles are multimodal-reasoning (default), audio-reasoning, image-question-answering, and video-question-answering. All four share the same input contract and write qwen2.5-omni.json through Qwen25OmniPipeline.
Stage Qwen/Qwen2.5-Omni-7B first. Missing weights surface at runtime; the runner does not download them. The 7B scale is intended for a single modern GPU.
audio-reasoning is a catalog task name. The recorded WorldFoundry fields still do not include an audio input — do not treat this page as a verified speech-in / speech-out recipe.
Runtime contract
Backend is the official Hugging Face Transformers runtime (official_hf_transformers_runtime). Loading is from_pretrained. Status: Runner parity pending — a checkpoint-backed GPU artifact has not been verified in this workspace. Talker / streaming-speech decode is out of scope for the recorded route.
Running in WorldFoundry
Launch worldfoundry-eval run qwen2.5-omni --pipeline.task-profile multimodal-reasoning in the unified environment worldfoundry-unified-cu128 (Python 3.11, CUDA 12.8). Prepare / inspect helpers are bash scripts/inference/prepare_model_infer.sh qwen2.5-omni and worldfoundry-eval zoo model-show --model-id qwen2.5-omni.



