RoboFlamingo
OpenFlamingo plus an LSTM action head; WorldFoundry GPU-validated predict needs three staged checkpoints.
RoboFlamingo turns OpenFlamingo into a language-conditioned robot policy: the VLM encodes a camera frame with a task instruction, and a recurrent head emits continuous controls (typically 7-DoF pose plus gripper). The official paper is Vision-Language Foundation Models as Effective Robot Imitators (arXiv 2311.01378). The project page is roboflamingo.github.io. The GitHub tree is RoboFlamingo/RoboFlamingo.
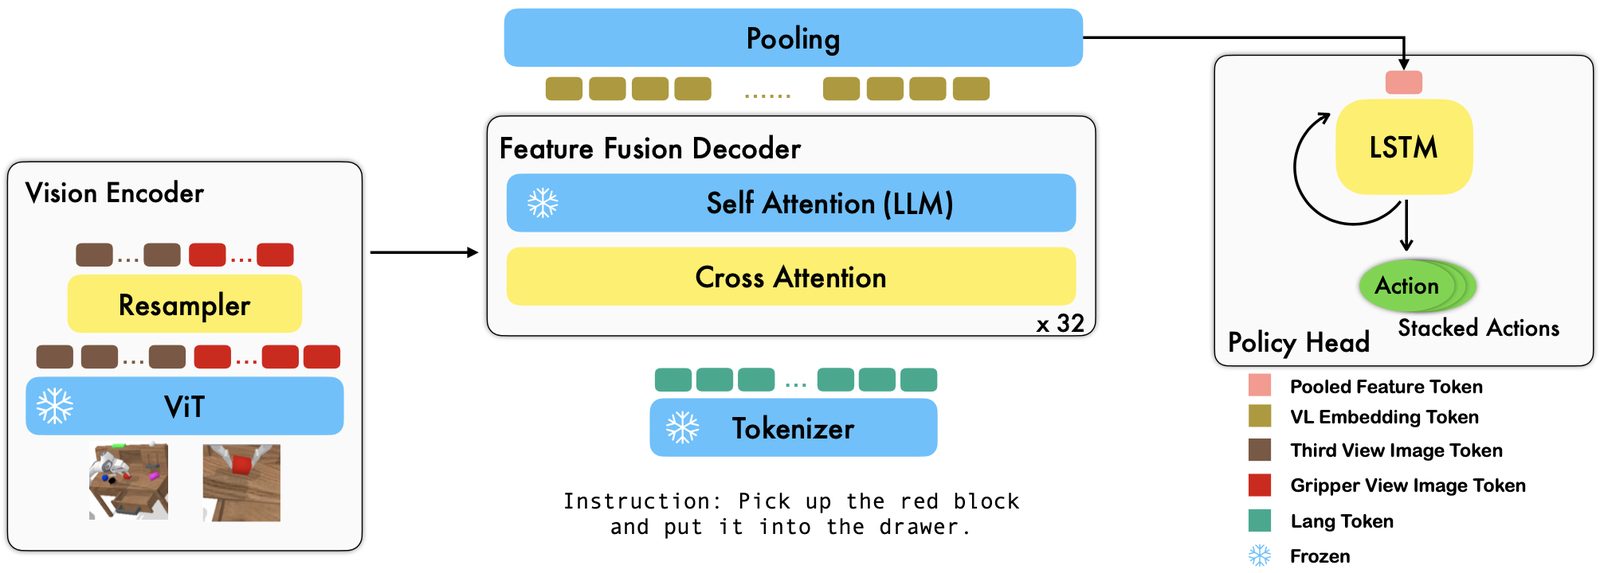
WorldFoundry vendors the architecture and inference source under worldfoundry/synthesis/action_generation/roboflamingo. There is a single catalog card — no extra variants. The public pipeline passed CUDA action_trace validation with three staged stacks: the released CALVIN policy, the OpenFlamingo VLM, and the MPT language backbone. Keep this model on embodied action maps, not video-generation scorecards. Alias robo-flamingo resolves here.
Build your run
RoboFlamingoPipelineworldfoundry.pipelines.component_pipelinesinteractive-videoworldfoundry.pipelineworldfoundry-eval run \
roboflamingo \
--pipeline.task-profile interactive-video \
--jsonWhat it is for
Language-conditioned manipulation on a CALVIN-style long-horizon suite is the intended route. Required inputs are image, instruction, prompt, and video. RoboFlamingoPipeline writes roboflamingo_action_trace.json.
Use this card when you need a GPU-ready OpenFlamingo policy with explicit backbone staging — not a chunking or diffusion action head.
Runtime contract
In-tree architecture defaults:
- Vision: ViT-L-14 (OpenCLIP), language: MPT-1B (
mpt_dolly_3bin config) window_size12,n_obs_steps2, fusionpost- Policy head: LSTM (
decoder_type/head_typebothlstm) - Gripper camera on, proprioception off (
use_state=false), fp32
Checkpoint directories — all must already exist under ${WORLDFOUNDRY_HFD_ROOT}:
robovlms/RoboFlamingo→robovlms--RoboFlamingo(released CALVIN policy)openflamingo/OpenFlamingo-3B-vitl-mpt1b-langinstruct→openflamingo--OpenFlamingo-3B-vitl-mpt1b-langinstructanas-awadalla/mpt-1b-redpajama-200b-dolly→anas-awadalla--mpt-1b-redpajama-200b-dolly
The vision encoder file is also declared at ${WORLDFOUNDRY_CKPT_DIR}/open_clip/ViT-L-14.pt. Full official CALVIN eval still needs the CALVIN assets themselves.
Running in WorldFoundry
The environment profile is worldfoundry-unified-cu128. The recorded env YAML is Python 3.8 with a prepare-only CUDA tag; the runner still completed a CUDA action_trace with those three checkpoints staged. After staging:
worldfoundry-eval run roboflamingoNo license is recorded in this repository. Confirm RoboFlamingo / OpenFlamingo / MPT terms before production use.