StarVLA
StarVLA: vla and wam; Verified; 2 variants.
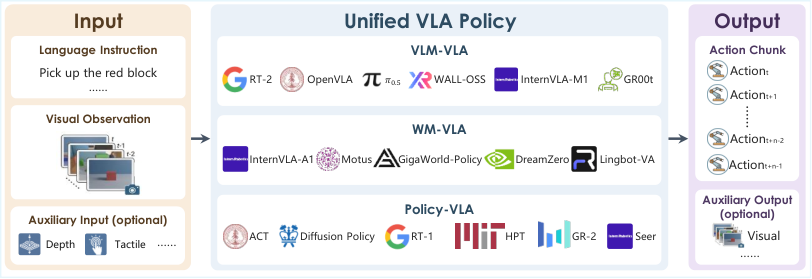
StarVLA is a Lego-like modular VLA framework; this catalog entry is GPU-validated: the official QwenOFT predict_action ran on an 80GB CUDA GPU with the local Qwen3-VL-OFT-LIBERO-4in1 checkpoint and Qwen3-VL-4B base VLM. A WM4A world-action checkpoint (Wan2.2-based) is also staged with tensor/import probes but is not promoted by the policy run.
The recorded paper is arXiv 2604.05014.
Project page: starvla.github.io/contributors. Code: starVLA/starVLA.
Build your run
StarVLAPipelineworldfoundry.pipelines.component_pipelinesinteractive-videoworldfoundry.evaluation.models.runners.pipeline:WorldFoundryPipelineRunnerworldfoundry-eval run \
starvla-qwen3-vl-oft-libero-4in1 \
--pipeline.task-profile interactive-video \
--jsonVariants
- StatusRunner parity pending
starvla-qwen3-vl-oft-libero-4in1vla.policy_rollout
Runtime profile
starvlaPipeline binding
starvla - StatusRunner parity pending
starvla-wm4a-wan2d2-oft-libero-4in1wam.world_action_modeling
Runtime profile
starvlaPipeline binding
starvla
What it is for
Pick starvla-qwen3-vl-oft-libero-4in1 when you want the catalog VLA policy: instruction and observation in, an action trace out. Use it to roll the recorded policy, not to train a new one.
The validated path is QwenOFT: a Qwen3-VL-4B backbone with OFT-style parallel action decoding, fine-tuned on four LIBERO suites in one checkpoint (4in1). The WM4A variant couples the policy with a Wan2.2 world model and remains probe-level.
Catalog tasks include vla, wam, vla policy rollout, and wam world action modeling. Catalog aliases include Qwen3-VL-OFT-LIBERO-4in1 and WM4A-Wan2d2-OFT-LIBERO-4in1. Also recorded: starvla-wm4a-wan2d2-oft-libero-4in1.
Recorded evaluation entry points include LIBERO (The 4in1 checkpoint covers four LIBERO suites).
Runtime contract
Optional prompt, input_path, interactions, fps, and checkpoint_dir; artifacts action_trace and starvla_action_trace.json.
CLI task profiles: interactive-video. WorldFoundry binds StarVLAPipeline.
Start on starvla-qwen3-vl-oft-libero-4in1. The family registers 2 catalog variants (cards above): starvla-qwen3-vl-oft-libero-4in1 (vla.policy_rollout) — Runner parity pending; starvla-wm4a-wan2d2-oft-libero-4in1 (wam.world_action_modeling) — Runner parity pending. Family status: Verified.
Use the QwenOFT 4in1 checkpoint for LIBERO evaluation; treat WM4A as staged-but-unvalidated. Stage the Qwen3-VL-4B-Instruct base alongside the policy checkpoint.
WorldFoundry runtime executed official StarVLA QwenOFT predict_action with local Qwen3-VL-OFT-LIBERO-4in1 checkpoint and Qwen3-VL-4B base VLM on an 80GB CUDA GPU.
Running in WorldFoundry
The catalog launch is worldfoundry-eval run starvla-qwen3-vl-oft-libero-4in1 --pipeline.task-profile interactive-video. The command builder above switches --pipeline.task-profile among recorded tasks and still emits worldfoundry-eval run.
It runs in the unified environment worldfoundry-unified-cu128 (Python 3.11, CUDA 12.8).
Recorded weight repositories include StarVLA/Qwen3-VL-OFT-LIBERO-4in1, StarVLA/WM4A-Wan2d2-OFT-LIBERO-4in1, and Qwen/Qwen3-VL-4B-Instruct among others. Prepare the environment and check local assets with bash scripts/inference/prepare_model_infer.sh starvla-qwen3-vl-oft-libero-4in1. Add --download to fetch missing public checkpoints.
Recorded licenses include mit; status: Verified.