
Vchitect-2.0 T2V
Vchitect-2.0 T2V from Shanghai AI Laboratory (Vchitect): text-to-video and video-generation; Static load only.
Vchitect-2.0 is Shanghai AI Lab's open text-to-video diffusion transformer; this entry serves the 2B checkpoint through a fully native assembly. It carries an unusually strong structural guarantee: the native DiT matches all 1019 checkpoint tensors and the native SD3 decoder matches all 138 decoder tensors. Aliases include vchitect, vchitect-2, and vchitect2-t2v.
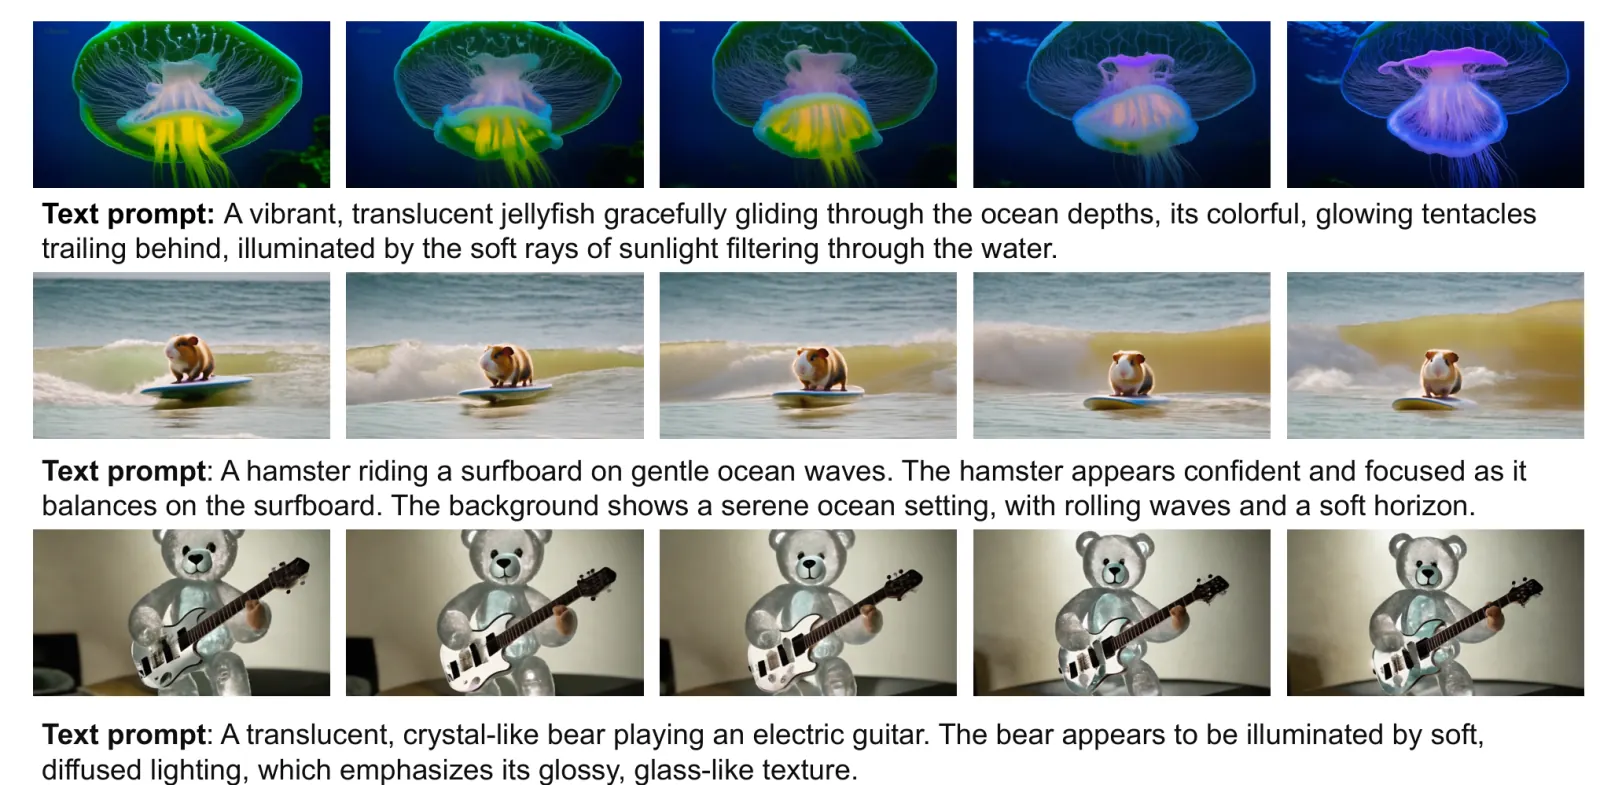
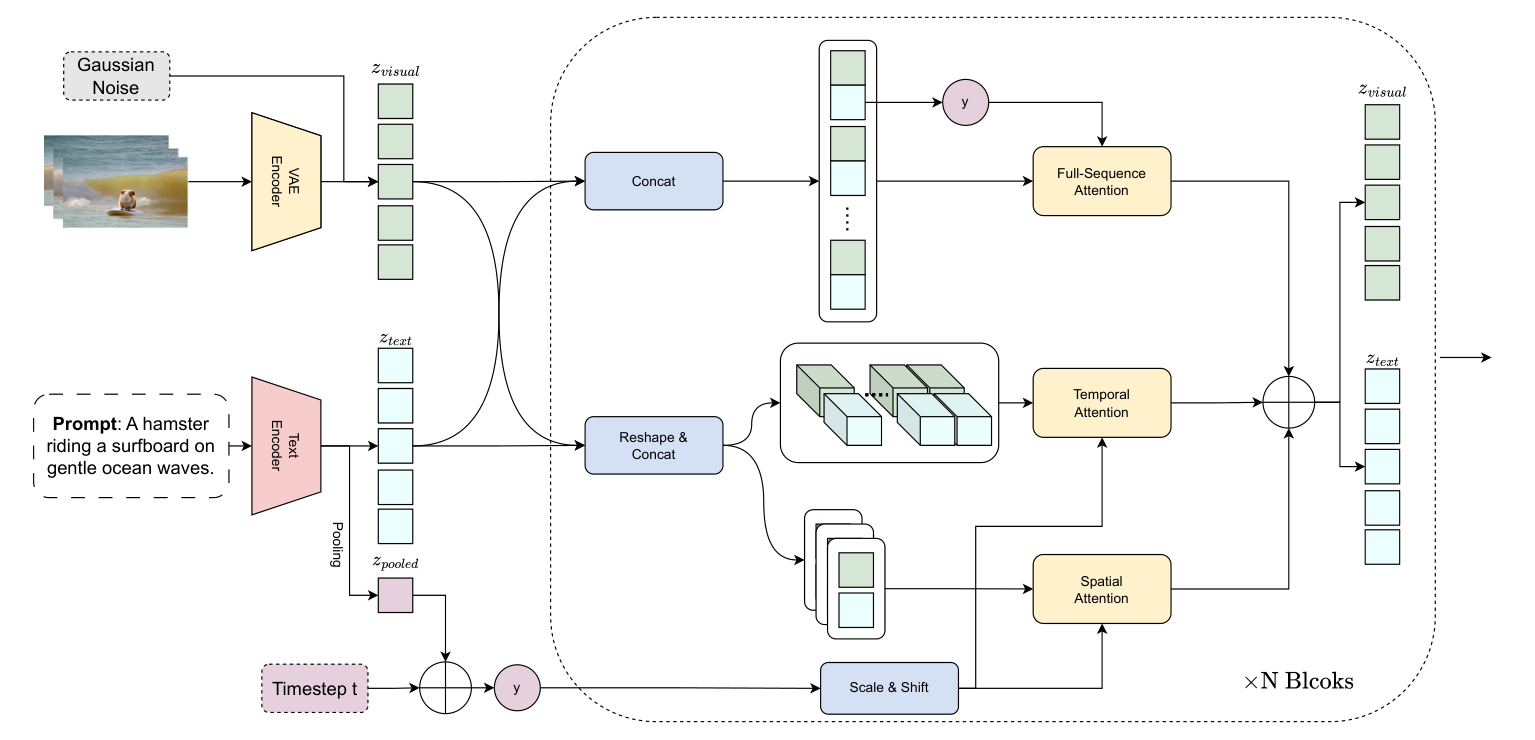
The recorded paper is arXiv 2501.08453.
Code: Vchitect/Vchitect-2.0.
Build your run
Vchitect2T2VPipelineworldfoundry.pipelines.vchitect.pipeline_vchitect_2_t2vinteractive-videoworldfoundry.pipelineworldfoundry-eval run \
vchitect-2-t2v \
--pipeline.task-profile interactive-video \
--jsonWhat it is for
vchitect-2-t2v is the recorded prompt-to-video route — not image editing and not a policy. Start here when the job is a clip from text.
A parallel diffusion transformer paired with an SD3-family VAE decoder, assembled from role-based DiT, conditioner, scheduler, initializer, and decoder components. The pinned official source revision is recorded in the profile (Vchitect-2.0 @ be56767f). It is published by Shanghai AI Laboratory (Vchitect).
Catalog tasks include text-to-video and video-generation. Catalog aliases include vchitect, vchitect-2, vchitect2-t2v, and vchitect_2_t2v. Documented modalities: text in, video out.
Recorded evaluation entry points include VBench (Standard T2V quality suite).
Runtime contract
Optional prompt, negative_prompt, frames, fps, and height; artifacts generated_video and vchitect_2_t2v_public_runner.mp4.
CLI task profiles: interactive-video. WorldFoundry binds Vchitect2T2VPipeline.
Family status: Static load only.
Runner status is Static load only: the default path loads the shared native pipeline and does not emit blocked plan artifacts. Weights are apache-2.0 at Vchitect/Vchitect-2.0-2B. Use id vchitect-2-t2v.
Use id vchitect-2-t2v. The public pipeline is assembled from native role-based components.
Running in WorldFoundry
Launch worldfoundry-eval run vchitect-2-t2v --pipeline.task-profile interactive-video to sample the clip. The command builder above switches --pipeline.task-profile among recorded tasks and still emits worldfoundry-eval run.
It runs in the unified environment worldfoundry-unified-cu128 (Python 3.11, CUDA 12.8).
Recorded weight repositories include Vchitect/Vchitect-2.0-2B. Prepare the environment and check local assets with bash scripts/inference/prepare_model_infer.sh vchitect-2-t2v. Add --download to fetch missing public checkpoints.
Recorded licenses include apache-2.0; status: Static load only.


