Allegro
Allegro from Rhymes AI: text-to-video and image-to-video; Runner parity pending.
Allegro is an open text-to-video and image-to-video generation model, cataloged here through its TI2V (text+image to video) route. WorldFoundry wraps the in-tree Allegro TI2V runtime, so a prompt — optionally anchored by a start image — produces a video artifact through the standard pipeline contract. The entry also resolves the aliases allegro_ti2v and allegro-ti2v.
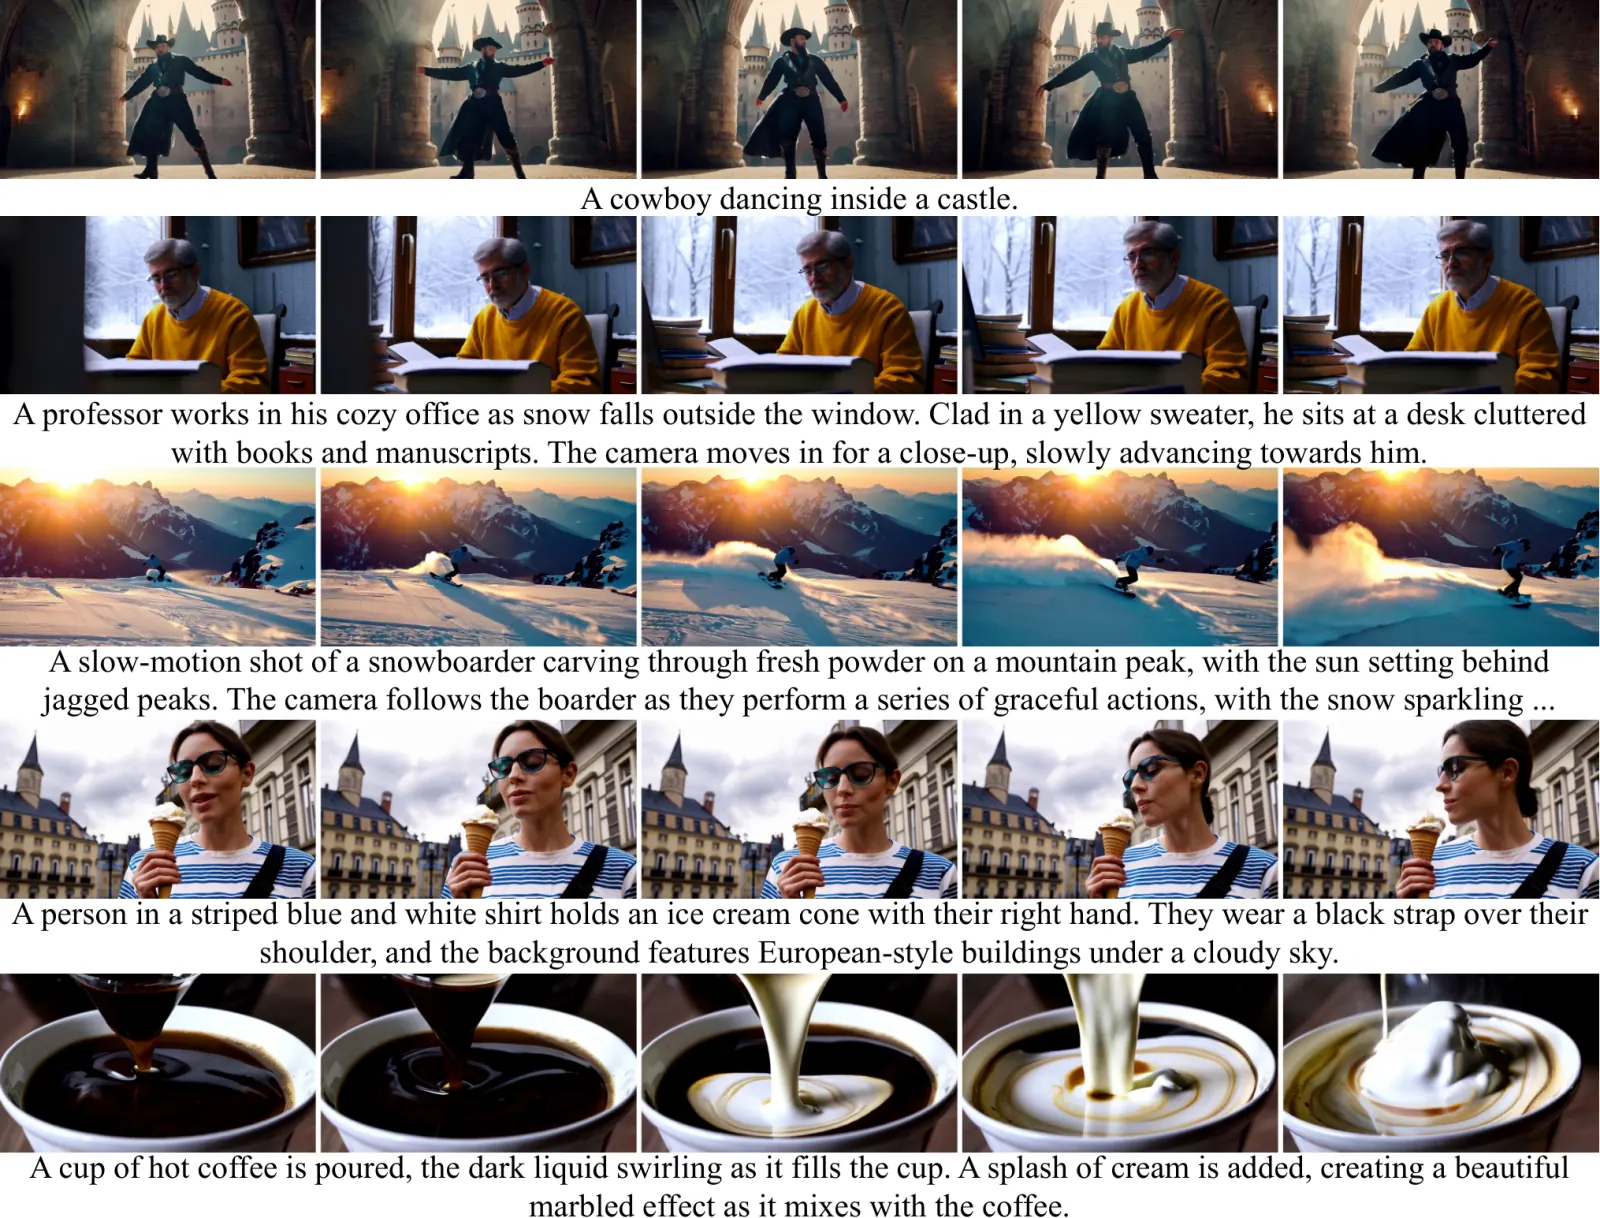
The recorded paper is arXiv 2410.15458.
Code: rhymes-ai/Allegro.
The official paper is on arXiv 2410.15458. Code: rhymes-ai/Allegro. Catalog license and publisher extras beyond "Rhymes AI" are unset. Local checkpoints stay external.
Integration is recorded; runner and demo parity are pending. A registered pipeline is not a checkpoint-backed GPU artifact.
Build your run
AllegroTi2VPipelineworldfoundry.pipelines.allegro.pipeline_allegro_ti2vinteractive-videoworldfoundry.pipelineworldfoundry-eval run \
allegro \
--pipeline.task-profile interactive-video \
--jsonWhat it is for
allegro is the recorded text/image-to-video line. Use it when you want both prompt and still conditioning on the same catalog card.
Allegro is a diffusion-transformer video generator released by Rhymes AI; the manifest records the in-tree runtime wrapper and the TI2V conditioning path (prompt, image, video, actions in the input schema), while local checkpoint assets remain external. Deeper architecture internals are not recorded in this repository — consult the upstream release for layer-level details. It is published by Rhymes AI.
Catalog tasks include text-to-video and image-to-video. Catalog aliases include allegro_ti2v and allegro-ti2v. Documented modalities: text and image in, video out.
Recorded evaluation entry points include VBench (Multi-dimension video generation quality suite that fits Allegro's T2V/I2V output).
Runtime contract
Optional prompt, negative_prompt, input_path, frames, and fps; artifacts allegro-ti2v.mp4.
CLI task profiles: interactive-video. WorldFoundry binds AllegroTi2VPipeline.
Family status: Runner parity pending.
The catalog marks the integration as integrated with runner parity pending: the pipeline target is registered, but artifact parity with the official demo configuration still requires a full official run. Stage the Allegro checkpoints locally before launching, and use the model-show command on this page to inspect the recorded contract first.
GitHub verification succeeded after retry; the first attempt hit a transient TLS error.
Running in WorldFoundry
Launch worldfoundry-eval run allegro --pipeline.task-profile interactive-video to sample the clip. The command builder above switches --pipeline.task-profile among recorded tasks and still emits worldfoundry-eval run.
It runs in the unified environment worldfoundry-unified-cu128 (Python 3.11, CUDA 12.8).
Recorded weight repositories include rhymes-ai/Allegro and rhymes-ai/Allegro-TI2V. Prepare the environment and check local assets with bash scripts/inference/prepare_model_infer.sh allegro. Add --download to fetch missing public checkpoints.
Recorded licenses include apache-2.0; status: Runner parity pending.



