VGGT
VGGT(Meta AI (FAIR) / University of Oxford (VGG)):3D 重建、3dgs;Runner 一致性待确认。
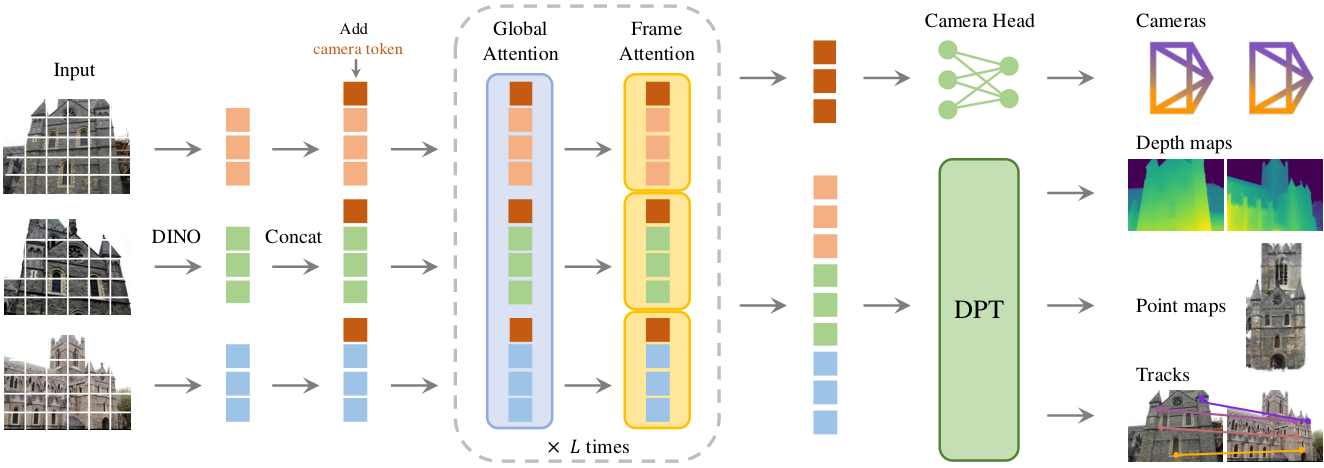
VGGT(Visual Geometry Grounded Transformer,CVPR 2025)是前馈网络:单次前向即可从一到数百个视图推断相机、深度图、点图与 3D 点轨迹——无需逐场景优化。本 catalog 中已注册树内两段式 3DGS pipeline,与 vggt-omega、vggt-world 条目相互独立。
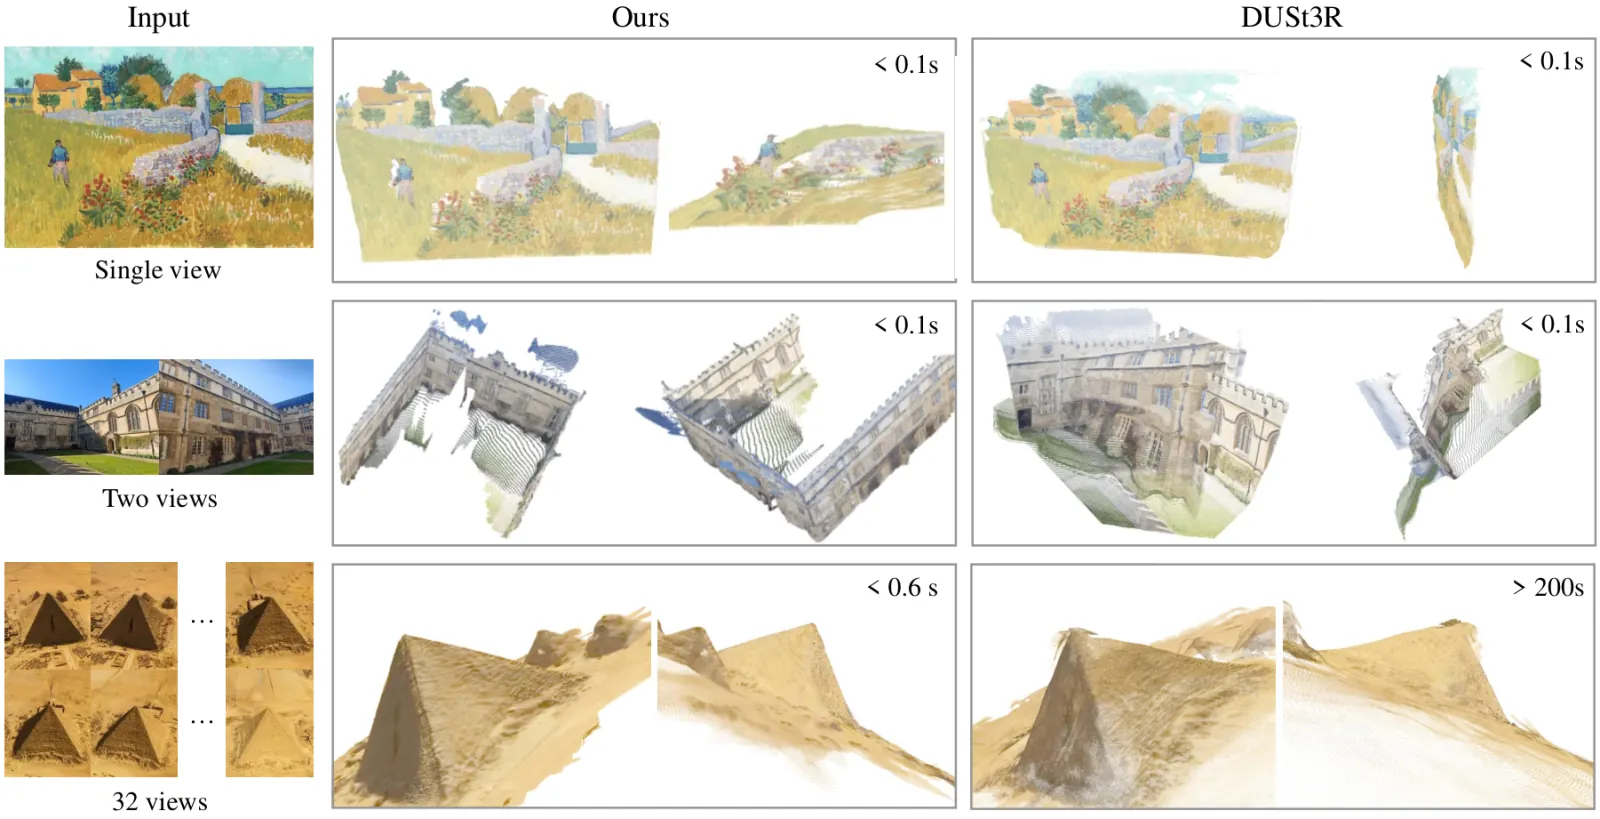
项目页:vgg-t.github.io。代码:facebookresearch/vggt。
论文是 Paper。项目页:vgg-t.github.io。代码:facebookresearch/vggt。
构建运行命令
VGGTPipelineworldfoundry.pipelines.vggt.pipeline_vggtinteractive-videoworldfoundry.pipelineworldfoundry-eval run \
vggt \
--pipeline.task-profile interactive-video \
--json用来做什么
用 vggt 做 catalog 几何推理。产物是重建而不是生成视频时选它。
按 CVPR 2025 论文,大型 Transformer 在图像 token 上交替执行帧内与全局注意力,任务头分别输出相机、深度、点图与跟踪。权重为 apache-2.0(facebookresearch/vggt);记录路径分两段从 VGGT 几何构建 3DGS。该模型由Meta AI(FAIR)/ 牛津大学 VGG 组发布。
catalog 记录的任务包括 3D 重建、3dgs、点云。输出模态为点云。
运行时契约
可选 input_path、interactions、fps、height、width。
CLI task profile:interactive-video。绑定的 pipeline 类是 VGGTPipeline。
系列状态:Runner 一致性待确认。
需要已验证的场景导出路径请用 vggt-omega;需要基于基础 VGGT 几何的两段式 3DGS pipeline 时用本条目。
In-tree VGGT two-stage 3DGS pipeline is registered; distinct from vggt-omega and vggt-world catalog entries.
在 WorldFoundry 中运行
启动 worldfoundry-eval run vggt --pipeline.task-profile interactive-video 写出几何。上方命令构建器按已记录任务切换 --pipeline.task-profile,发出的仍是 worldfoundry-eval run。
运行环境未记录。
记录的权重仓库包括 facebook/VGGT-1B。准备环境并检查本地资产:bash scripts/inference/prepare_model_infer.sh vggt;下载缺失的公开权重时加 --download。
状态:Runner 一致性待确认。